PowerTable turns your Fabric data into a no-code app. Teams can edit, track, approve and govern their data, right where it lives. From master and reference data to products, projects, tasks, timesheets and budgets, every team gets one secure place to work. No exporting to spreadsheets, and no waiting on IT. New to PowerTable? Start with What are PowerTable sheets in planning? on Microsoft Learn.
The PowerTable November 2026 release brings exciting enhancements across data management, analytics, project management, and automation. We’ve strengthened Security & Governance, enhanced Microsoft Teams integration across approvals and automations for more proactive tracking, and introduced JSON data type support to expand unstructured data capabilities. Crosstab gets richer pivot functionality, while Kanban brings improvements for easier data updates and tracking. We’re also introducing Earned Value Management metrics in Gantt to help monitor project and task health.
PowerTable security now lets you control who sees and changes each column, and who manages the security settings themselves.
Column Access, in Security, sets Read, Insert and Update permissions for each column of a table, per role. Read shows or hides the column. Insert controls whether a user can enter a value in a new row. Update controls whether a user can change a value in an existing row. Settings apply to all roles or to specific roles. When a user has several roles, an access is granted if any of those roles grant it.
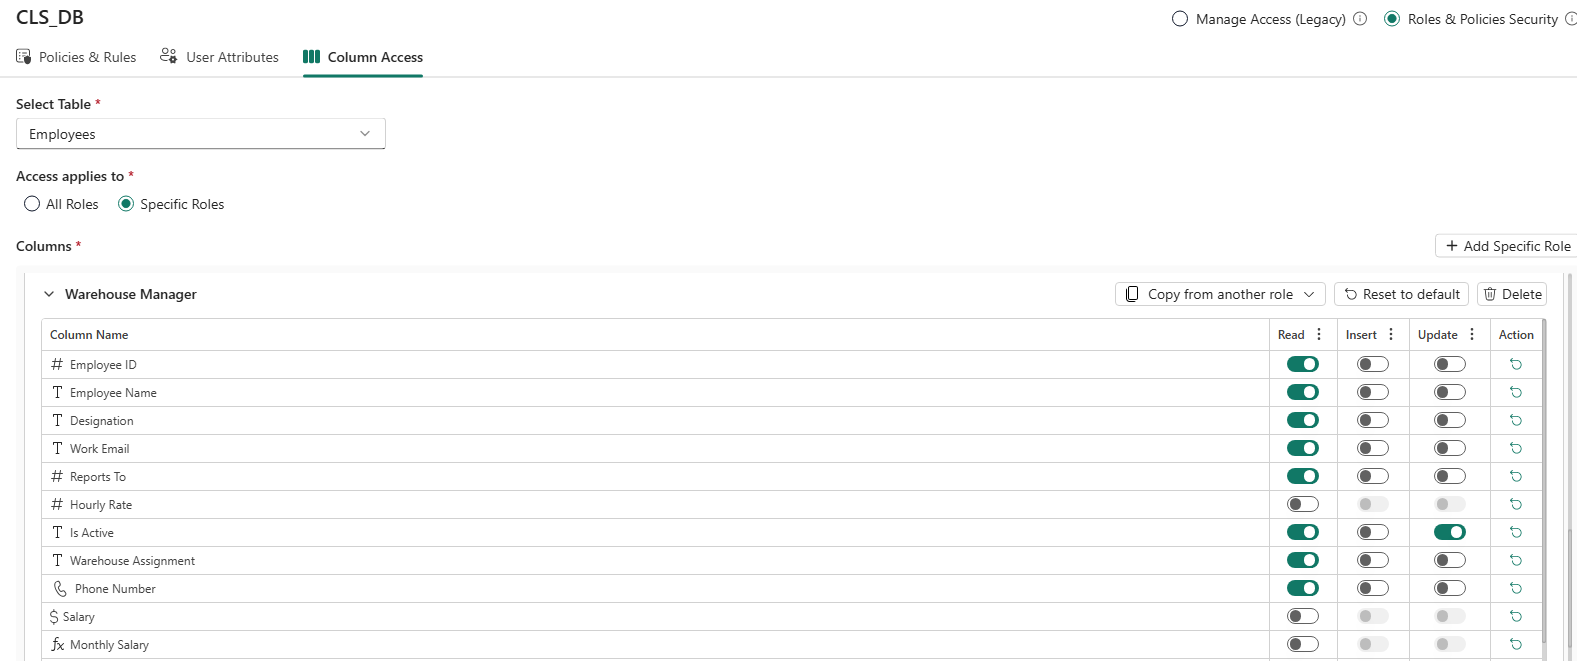
Use case: An HR team shares one employee table with the whole business. Managers can see salaries for their reports but can’t change them, while HR administrators keep them up to date. For everyone else, the salary column simply isn’t there, so one table serves every team with no oversharing.
For a full walkthrough, see Column Access: Column-Level Security for PowerTable.
The new Security access page sets whether Workspace Contributors can edit security and governance settings. Choose Yes for all Contributors, No for none, or Specific Contributors only for the Contributors you add to a list. The item owner, Workspace Admins and Workspace Members always have full edit access. The setting covers roles, user attributes, policies, approvals, row and column access, and creating and deleting sheets. It does not affect editing table or planning data. The same page also links to OneLake security, where you control who can access writeback data in OneLake.
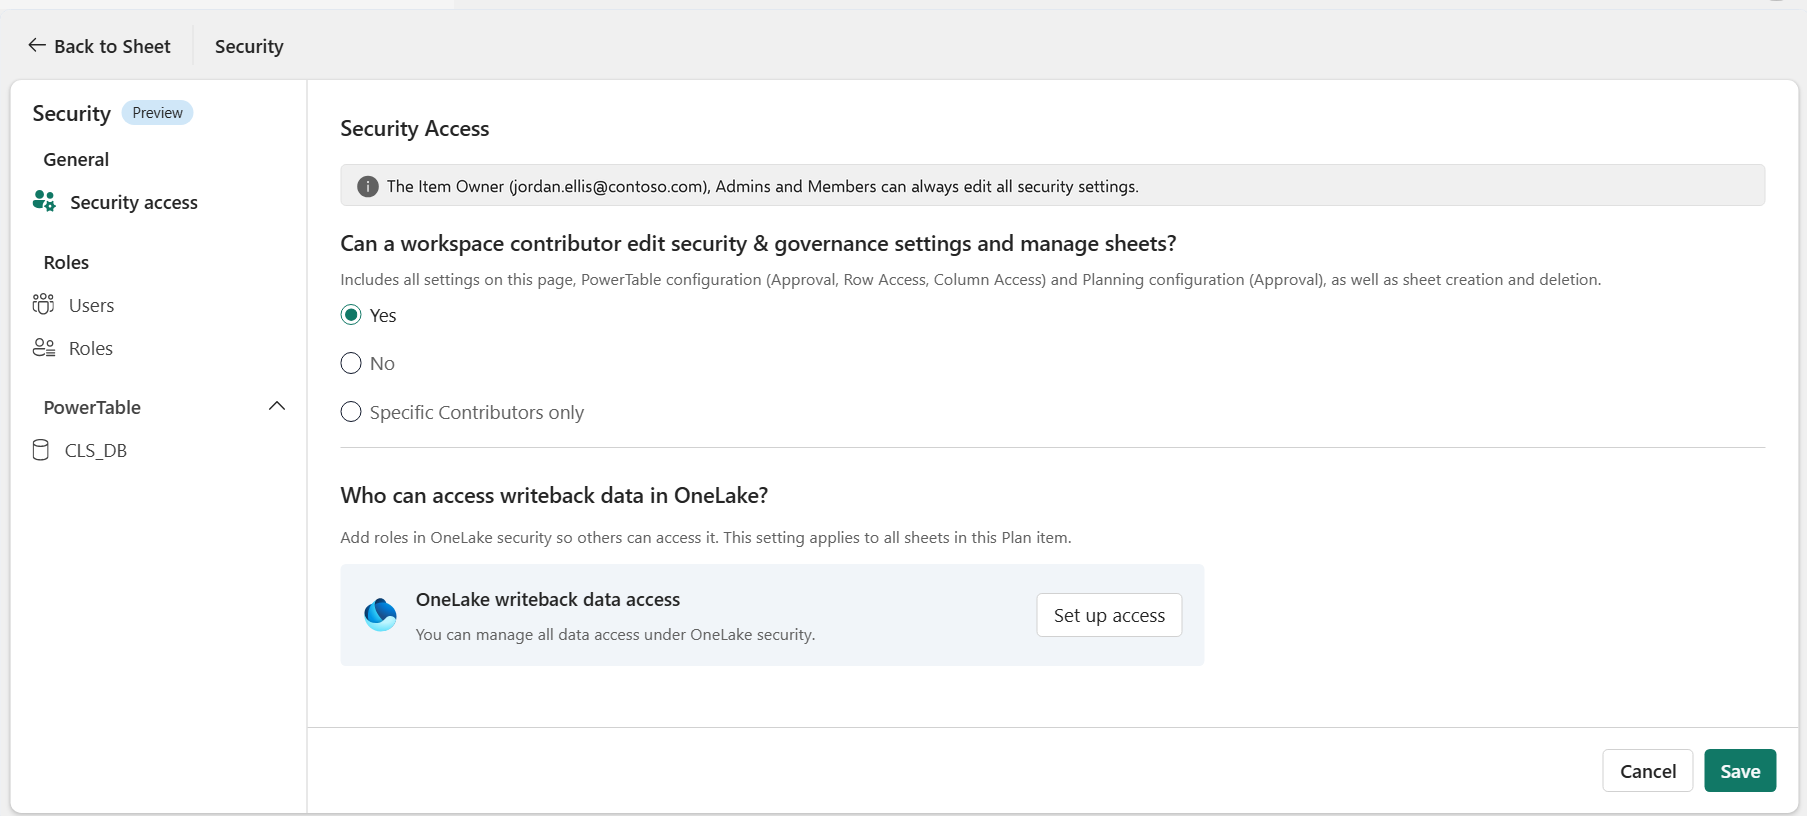
Use case: A finance team works in a shared budgeting workspace where every member is a Contributor. Everyone can update budget data, but only the two team leads are on the list of Contributors who can change approval rules and column access. The team moves fast, and the controls stay in trusted hands.
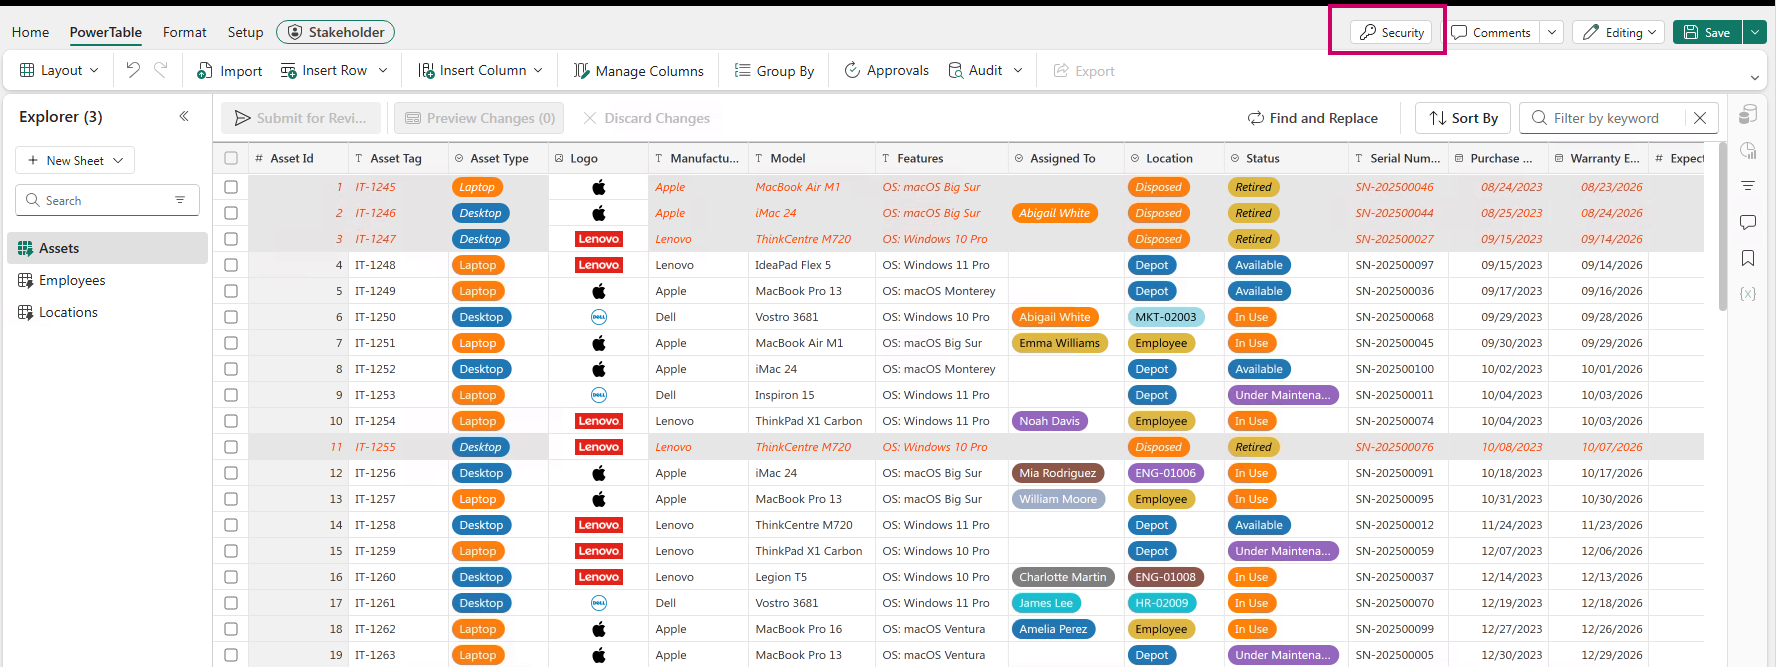
Where to find it: Open Security at the top right of the sheet. Column Access: Security › Column Access. Security access: Security › General › Security access.
Column Access
Security access
Automations and approvals can now post messages to Microsoft Teams channels.
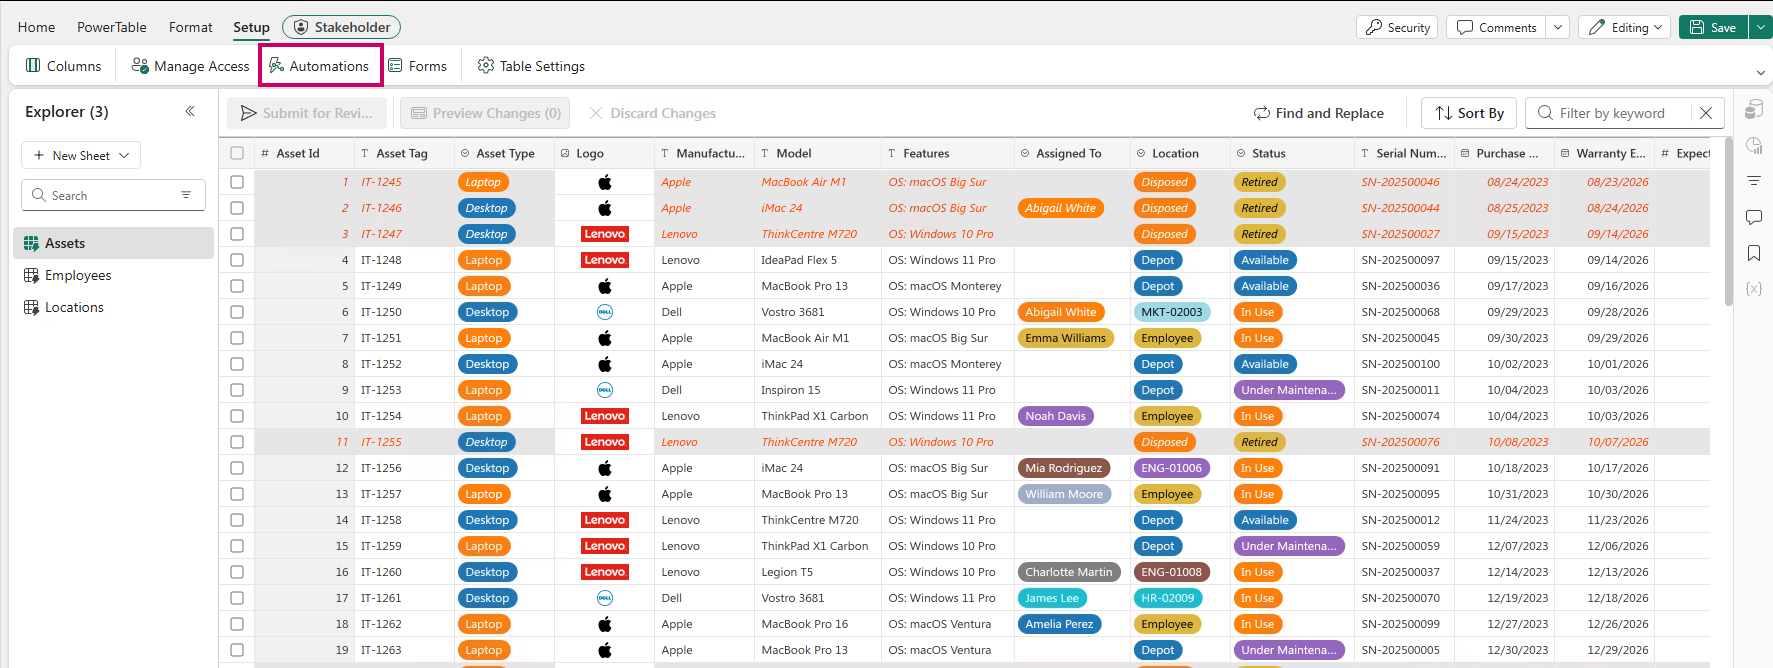
Send a message in a channel is now available as an action in PowerTable automations. It works with Update, Insert, Delete, Insert using Forms and Button triggers. Write the message, then connect to Microsoft Teams and choose the team and channel to post to. Messages can include dynamic content. Insert fields from the record that triggered the automation, such as a task’s name or start date. Or add predefined values, such as the current date and time. Messages are sent with the permissions of the user who triggers the automation.
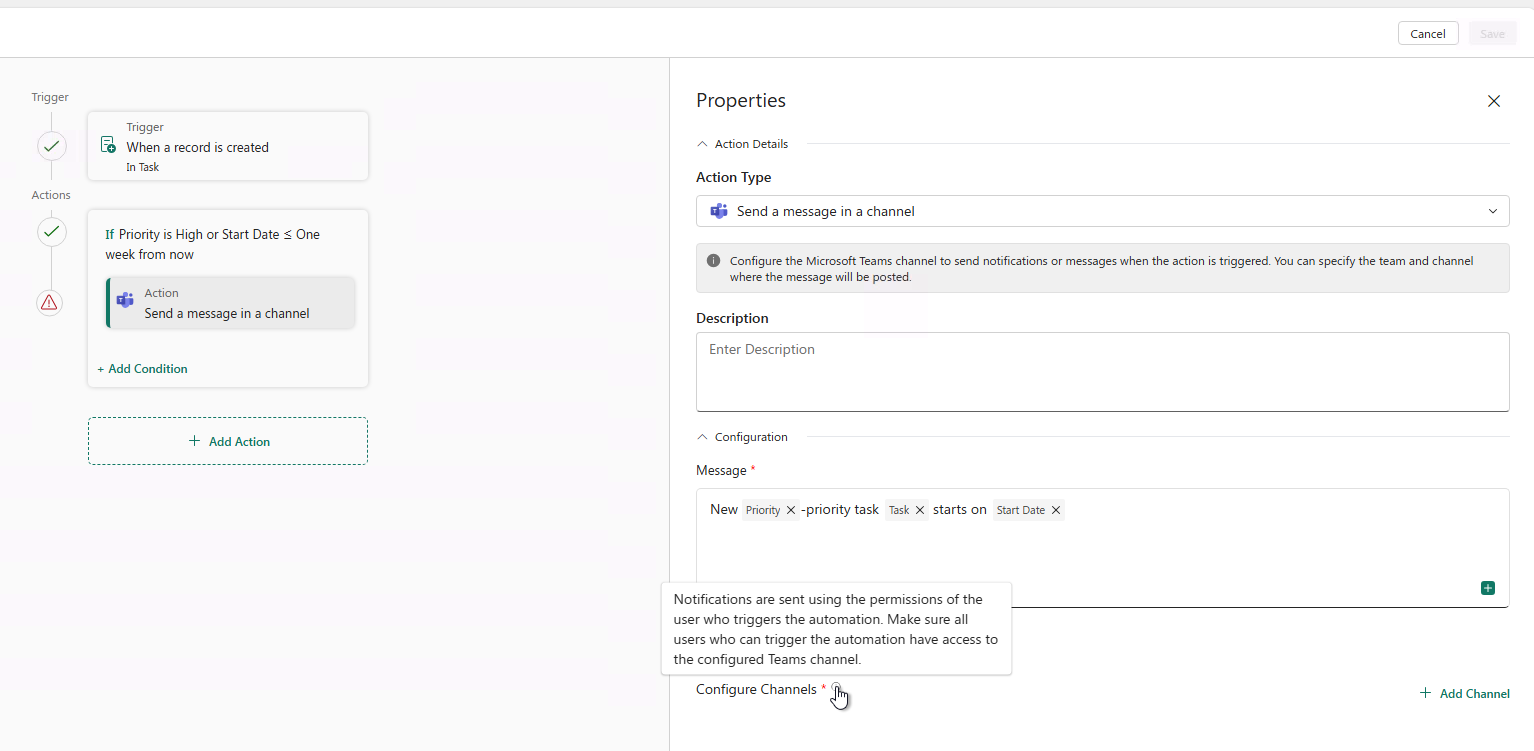
Use case: A high-priority task is created, and the delivery team’s channel hears about it in seconds: “New high-priority task Payment Gateway Integration starts on November 25, 2026.” No one has to refresh a grid or forward an update to keep everyone in the loop.
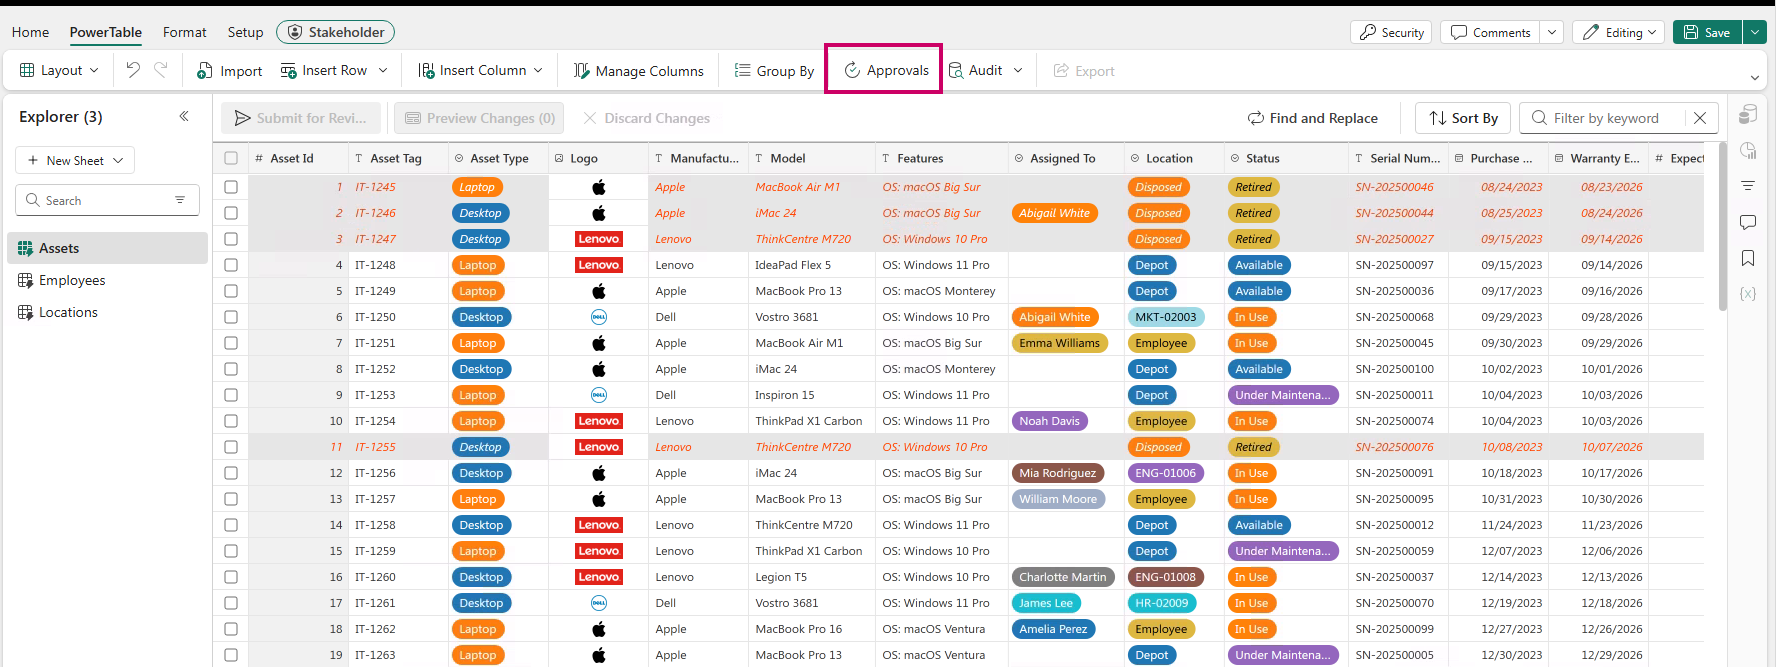
Approvals can now notify Teams channels in addition to the approvers. In Approvals Configuration, under Notifications, add one or more Teams channels. Each channel is listed with its team and the person who added it, and can be removed at any time.
Use case: A regional manager submits a budget change late in the quarter. The request shows up right away in the finance approvers’ Teams channel, where they’re already working together. Approvals keep moving without anyone digging through an inbox.
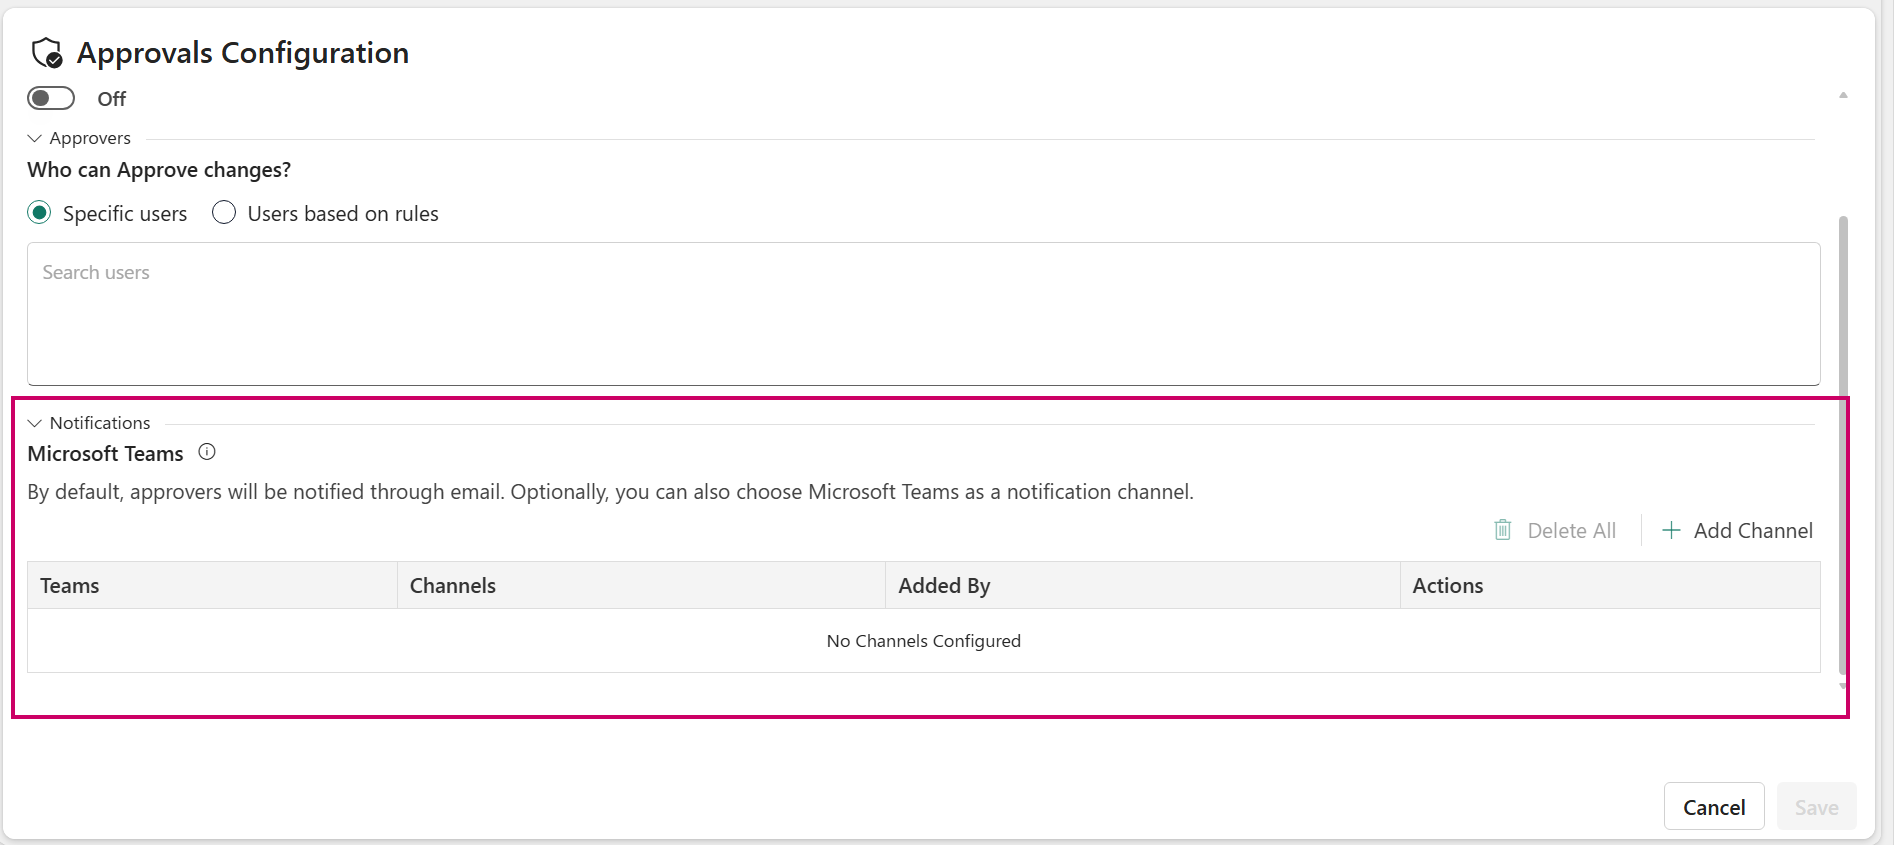
Where to find it: Automations: Setup › Automations. Approvals: PowerTable › Approvals.
Automations
Approvals
The JSON data type lets you store key-value pairs, nested objects and arrays in a single column, and edit them like any other field.
Use cases: Not all business data fits neatly into fixed columns. Now it doesn’t have to. JSON opens PowerTable to semi-structured data in every industry:
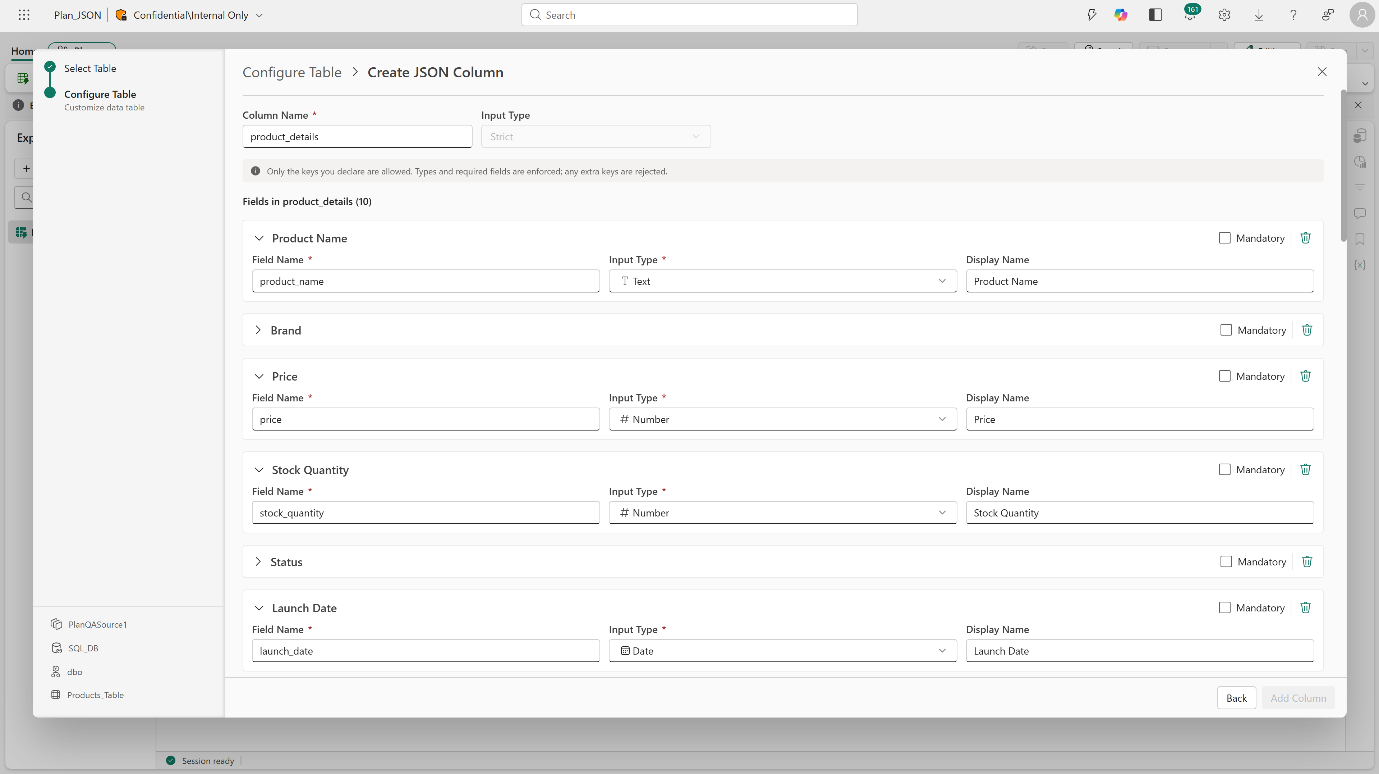
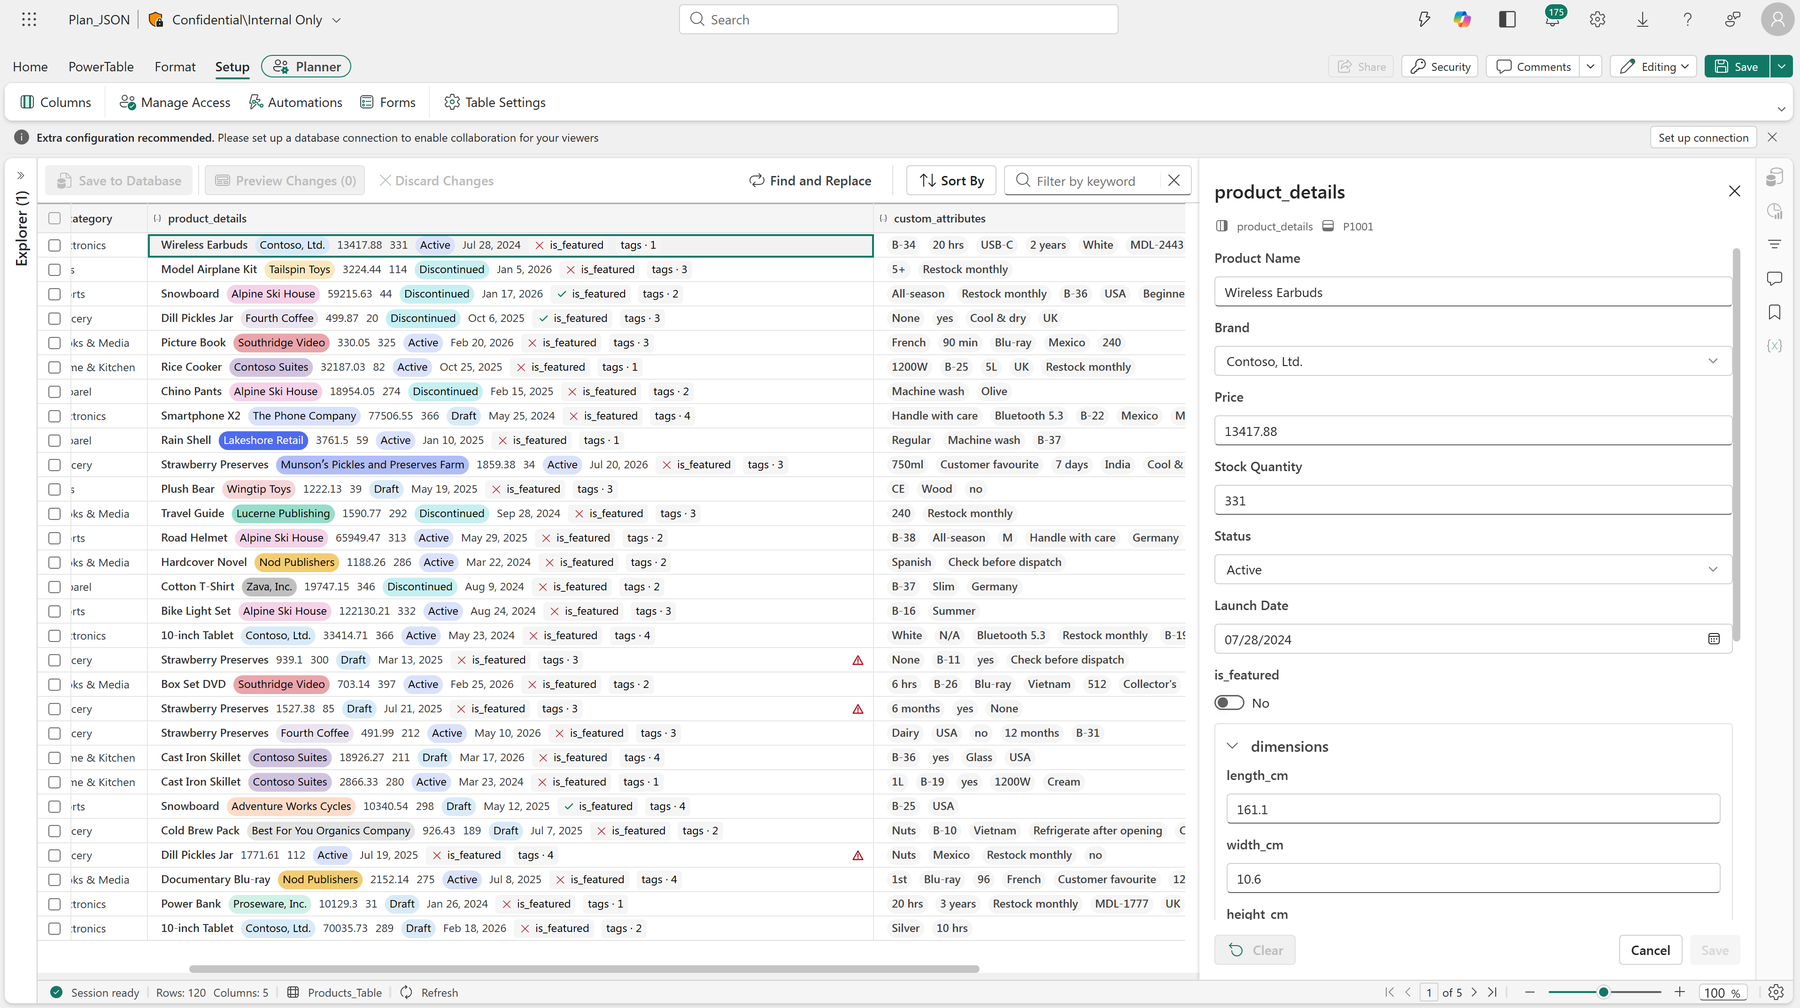
How it works:
Where to find it: For a new column, PowerTable › Insert Column › Database Column. For an existing table, Setup › Columns.
Crosstab displays table data as a pivot. Dimensions sit in Rows and Columns, and the values in the cells are editable. Every change is written back to the source table.
Crosstab now lets you generate the grid you need, enter data at any level of detail, and decide how every value is summarized.
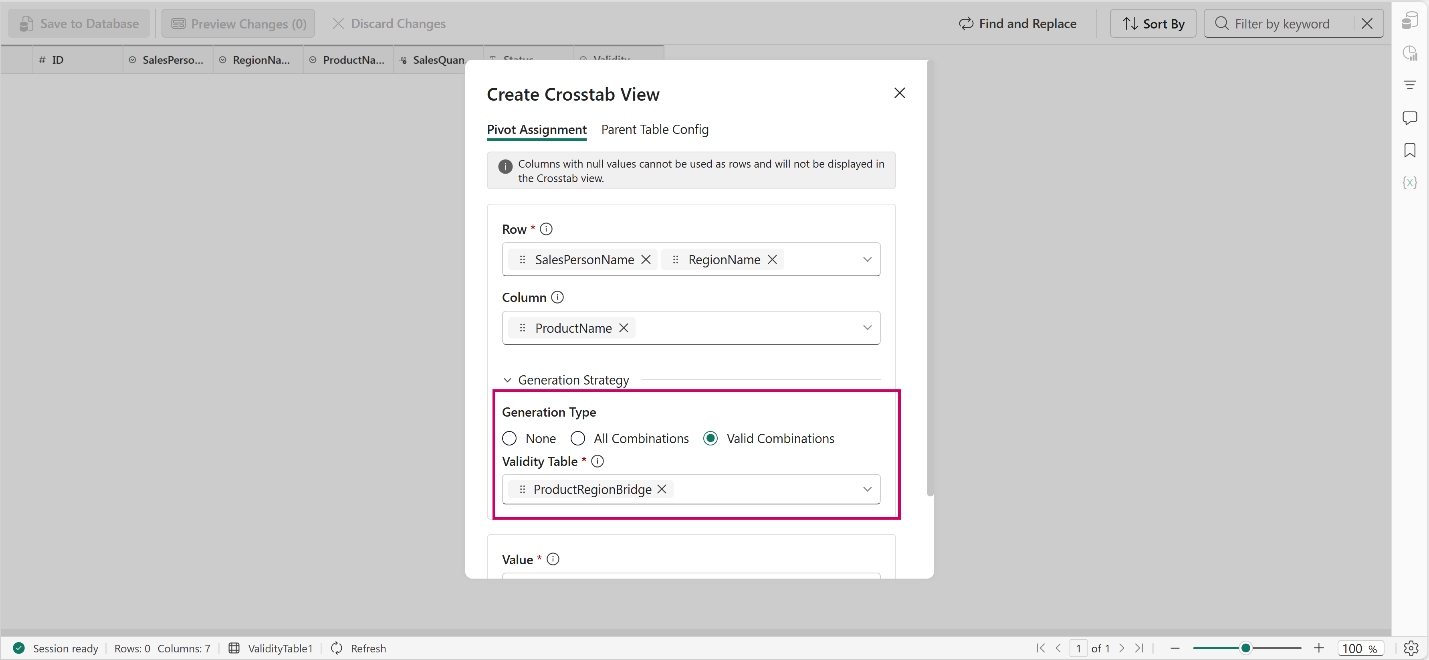
Generation Strategy sets which rows and columns Crosstab creates:
Use case: Picture a sales team planning by product, region and salesperson. Pair a product-region map with a region-salesperson map, and the planning grid builds itself. Every valid combination is ready to fill, and nothing that doesn’t belong gets in the way.
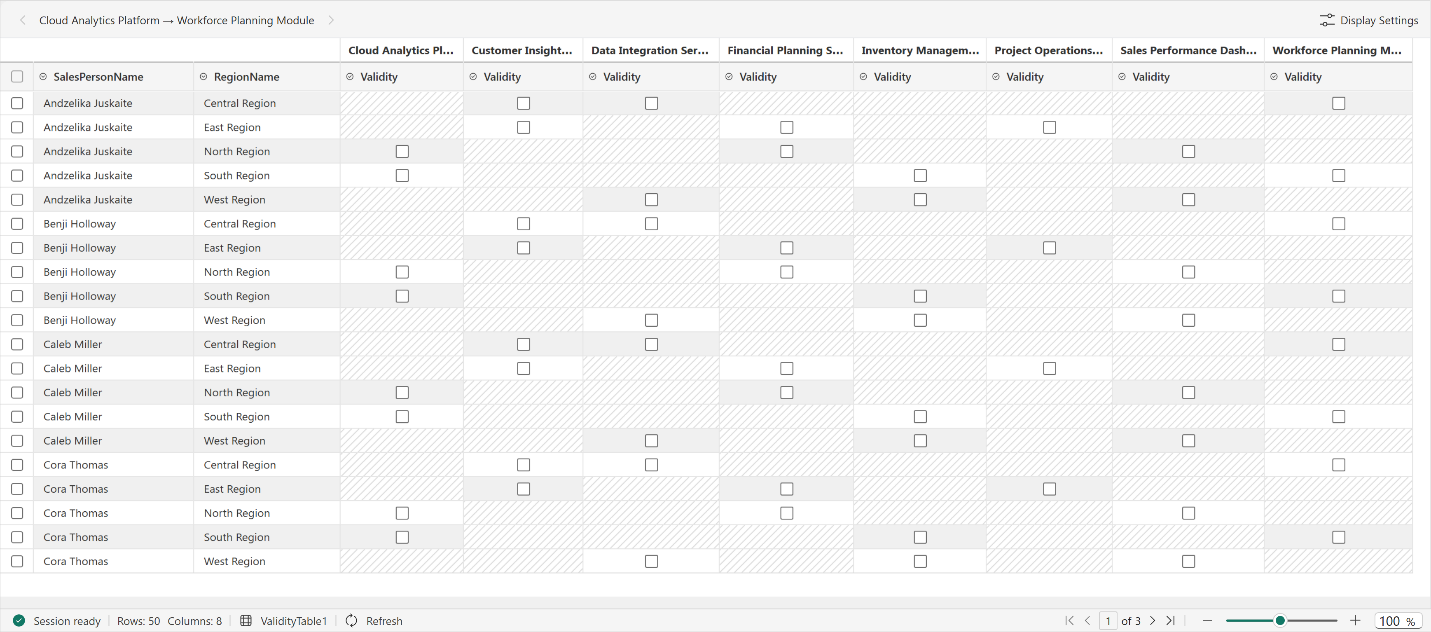
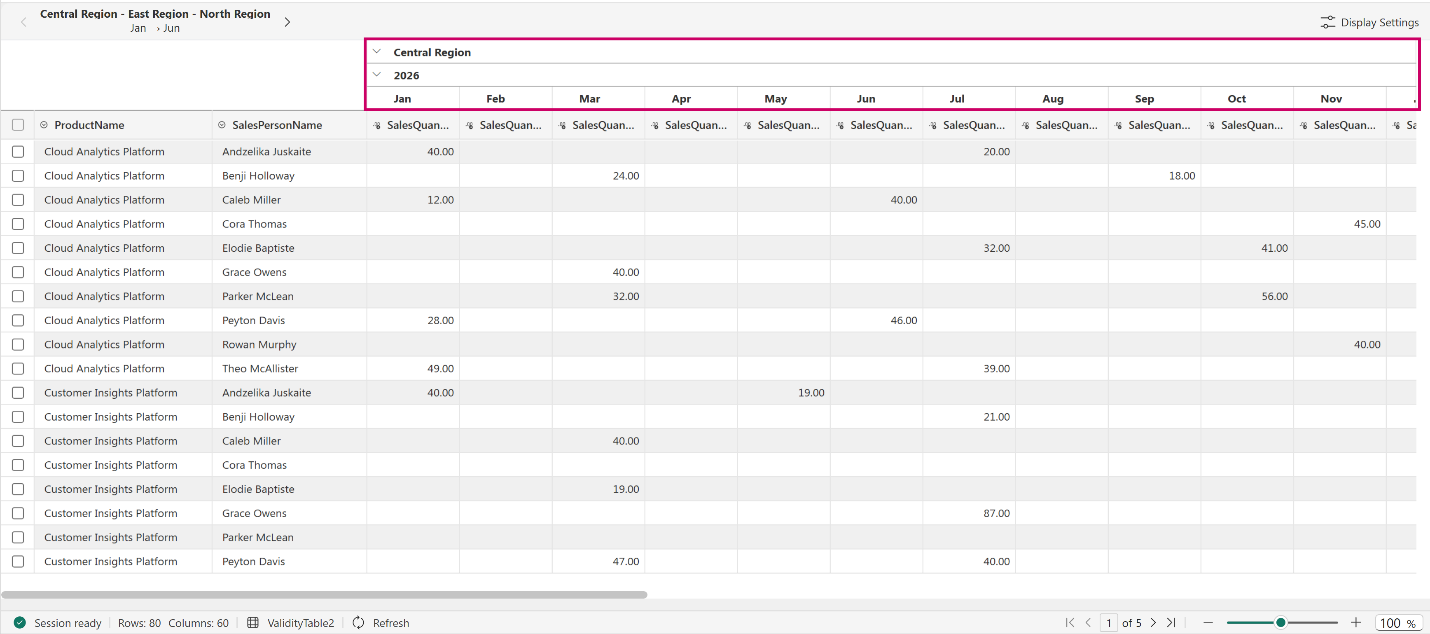
The Columns field accepts multiple dimensions, such as Region, Salesperson and Month. Their order sets the header hierarchy. Date, single-select and lookup fields can be combined.
Use case: A sales director reviews targets across the whole organization. With Region, Salesperson and Month stacked in Columns, every salesperson in every region appears side by side, month by month, in one view. No more stitching reports together to see how the team is tracking.
Date fields can now be added to Rows. They use the same Time Interval, Date Range and Date Hierarchy settings as in Columns. Crosstab generates a row for each period in the range, and can add Year and Quarter columns from the hierarchy.
Use case: A product planner builds a monthly forecast with months down the side and regions across the top. The year and quarter stay in view next to every month, so seasonal patterns are easy to spot. Forecasting feels as easy as a spreadsheet, with every number saved straight to the source.
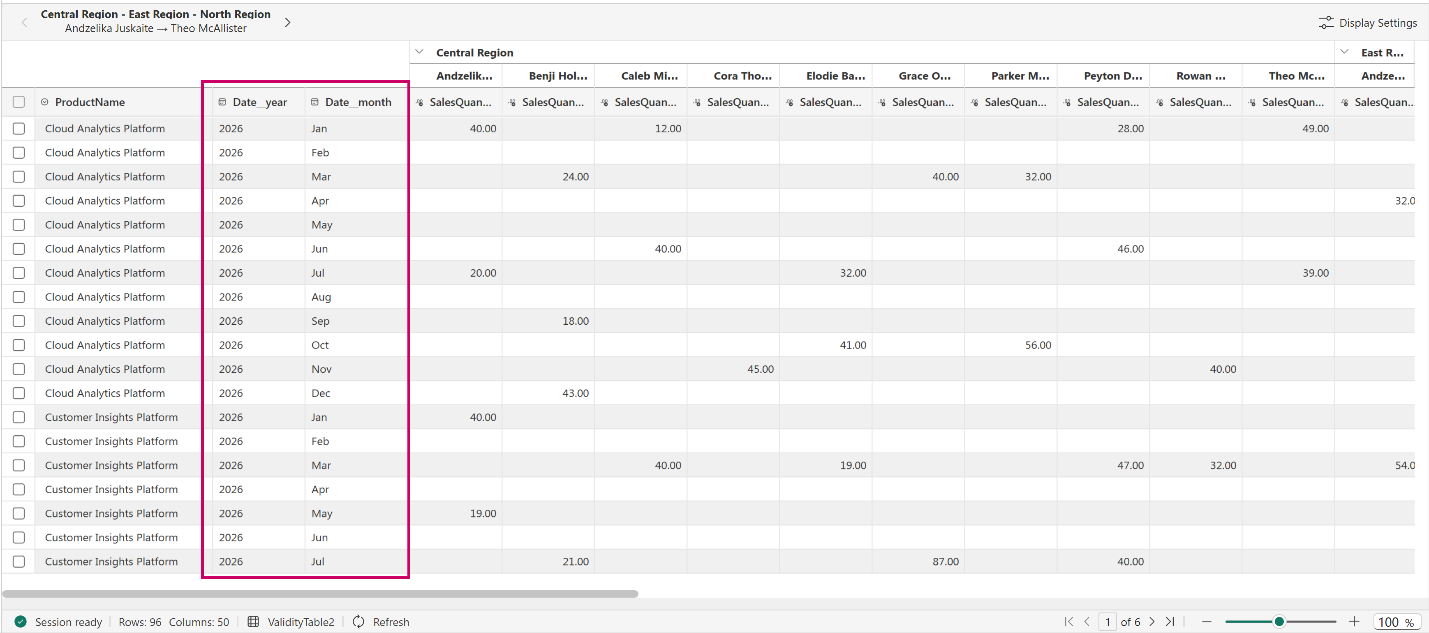
A Crosstab can be configured with only Rows and Values, without a Column dimension. Generation, aggregation and subtotals work the same way.
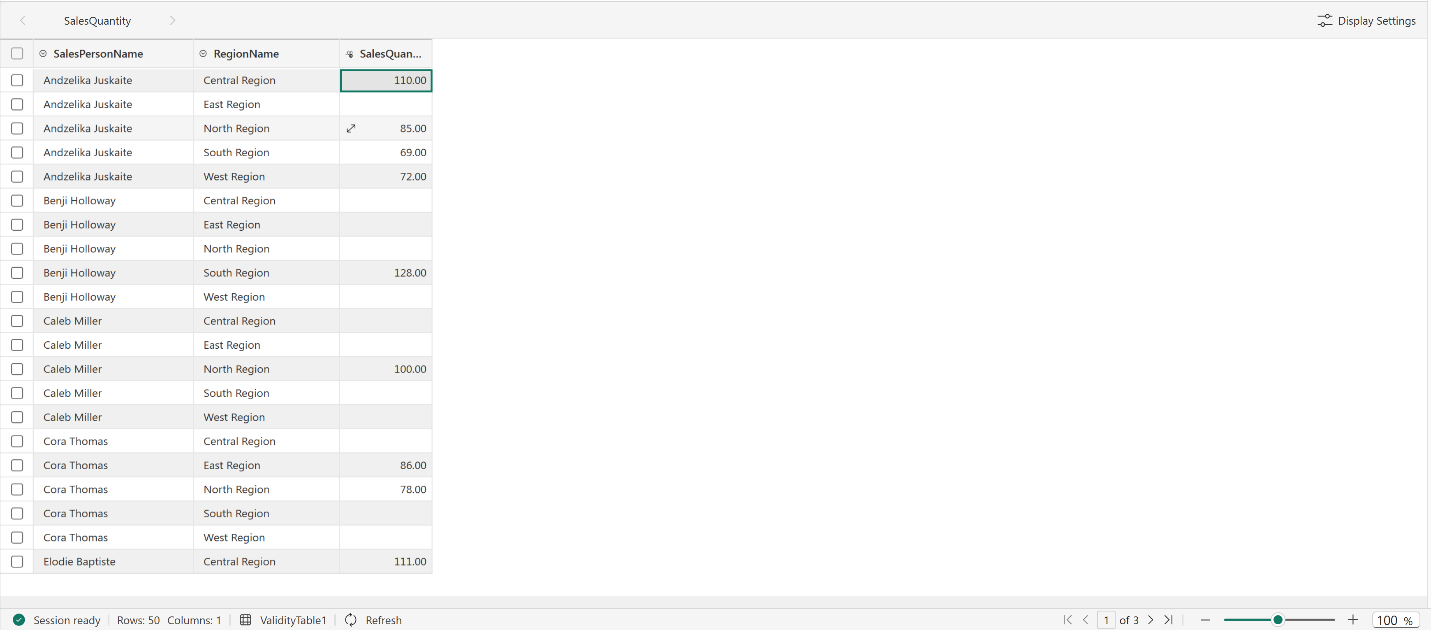
Use case: A finance team collects budget lines by department and cost center. A row-only Crosstab gives them a clean list to fill in, with subtotals for each department rolling up on their own. No extra columns and no manual totals.
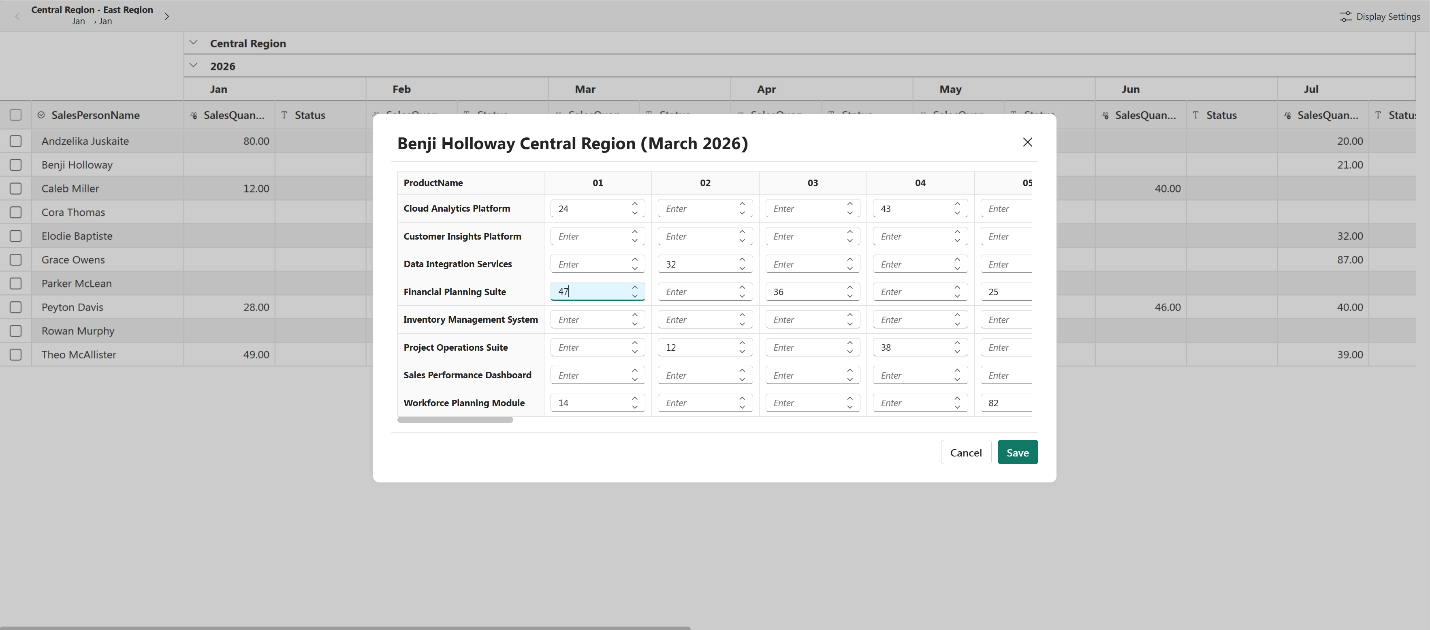
With Drilldown on, selecting a cell opens a detail view of the values behind it. Drill by field, such as Task under Project. Or drill by time, such as Week or Day under Month. Values entered in the detail view are written to the matching record and date. With Drilldown off, a Period Reference Date sets which date each summary value is read from and written to. Choose First Day, Last Day or a specific day.
Use case: A project manager reviews logged hours by project and month. When a month looks light, they open the cell and enter hours week by week, task by task. The big picture and the fine detail stay one click apart, and every value lands on the right record and date.
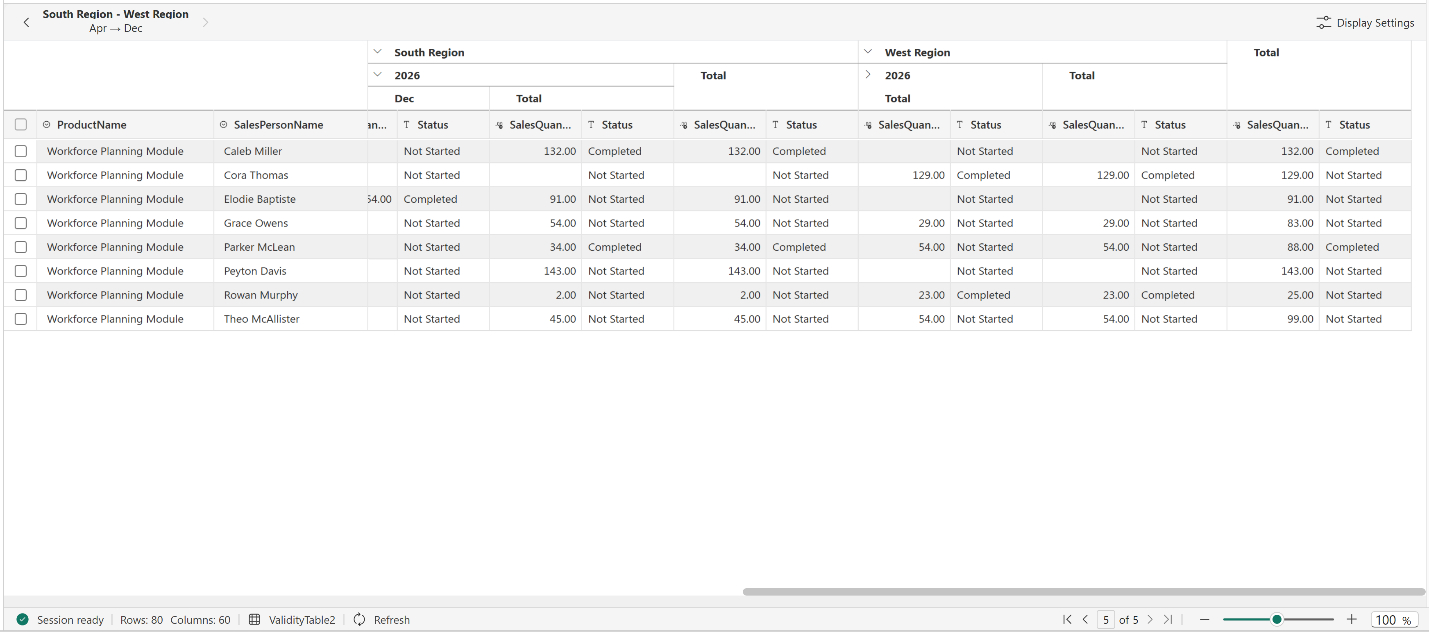
Each field in Values has its own aggregation, set from its ellipsis menu. Number fields support Sum, Average, Minimum, Maximum, Count and Count Distinct. Text and date fields support First, Last, Count and Count Distinct. Binary fields support Count and Count Distinct. The aggregation applies to subtotals, grand totals, drilldowns and collapsed column groups.
Use case: A delivery lead tracks hours and status for every task in one Crosstab. Hours are summed for each period, while Status shows the latest value, so effort and progress sit side by side. Every number tells the story it should.
Where to find it: PowerTable › Layout › Crosstab. To change an existing Crosstab, PowerTable › Layout › Manage Layout.
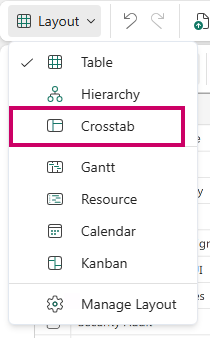
Kanban groups table rows into stacks by a status column. Moving a card to another stack updates its status.
Kanban now lets you set a limit on each stage and add new stages without leaving the board.
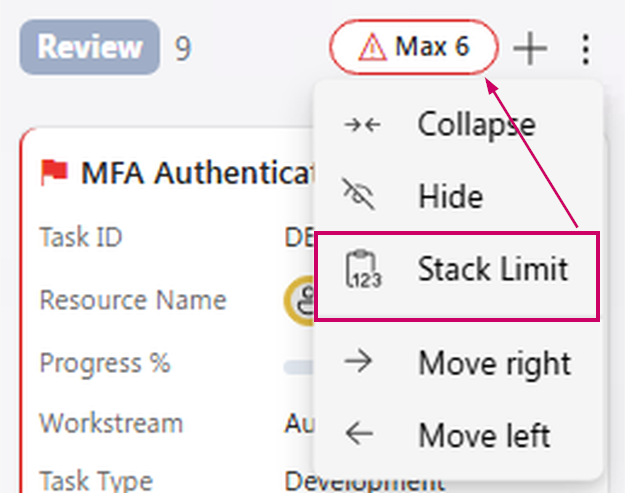
Stack Limit, in each stack’s menu, sets the maximum number of cards a stack can hold. It works for any stack, whether the board is grouped by stage, owner, priority or any other column. The header shows the current count against the limit. A red Max marker appears when the count goes over it. Each stack can have its own limit, or none.
Use case: A development team caps its Review stack at six cards. When a seventh card lands, the Max marker appears on the header, and the team knows it’s time to finish reviews before starting anything new. Bottlenecks show up before they become problems.
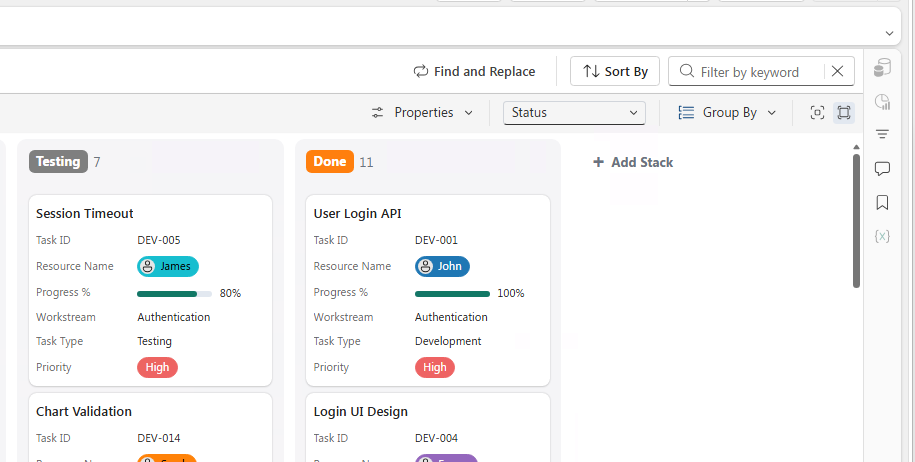
The + Add Stack button sits after the last stack. The name is added as a new value of the status column. Cards moved into the stack take that value when saved.
Use case: Work on an integration stalls while the team waits on a vendor. The team lead adds a Blocked stage straight from the board and moves the affected cards into it. Everyone can see what’s stuck, and the board stays an honest picture of the work.
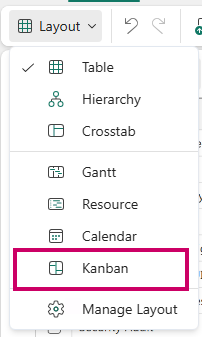
Where to find it: PowerTable › Layout › Kanban.
Stack limits
New stages
Earned Value Management lets you see whether a project is on schedule and on budget, in the same plan your team works in.
Earned Value Management (EVM) is the standard project control method for tracking schedule and cost together. It complements your Gantt schedule by showing whether spending is in line with progress. EVM compares three figures against an approved baseline. These are the budgeted value of work planned to date, the budgeted value of work completed, and the actual cost so far.
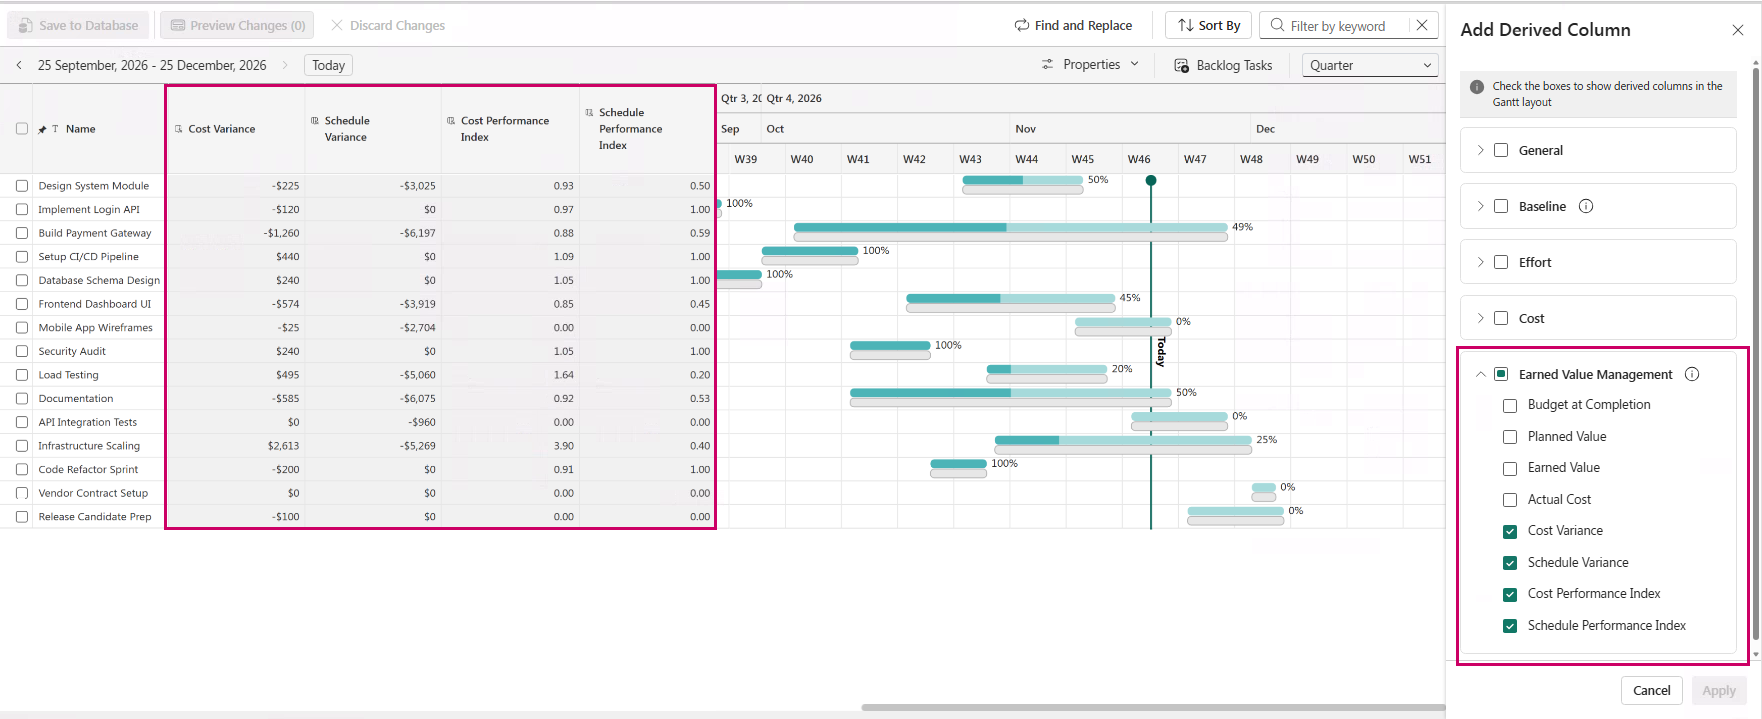
PowerTable now calculates EVM on your project plans. Inputs from your task, resource and time-entry tables are mapped once in Layout Configuration. PowerTable then calculates Budget at Completion, which is locked when you save a baseline. It also calculates Planned Value, Earned Value, Actual Cost, Schedule Variance, Cost Variance, Schedule Performance Index (SPI) and Cost Performance Index (CPI). Variances show how far ahead or behind a project is in money terms. An SPI or CPI below 1.0 means the project is behind schedule or over budget.
Use case: Take a $100K project with an SPI of 0.88 and a CPI of 0.78. An SPI of 0.88 means the team has completed 12% less work than scheduled so far. A CPI of 0.78 means every dollar spent is earning 78 cents of budgeted work. Your PMO knows while there’s still time to act.
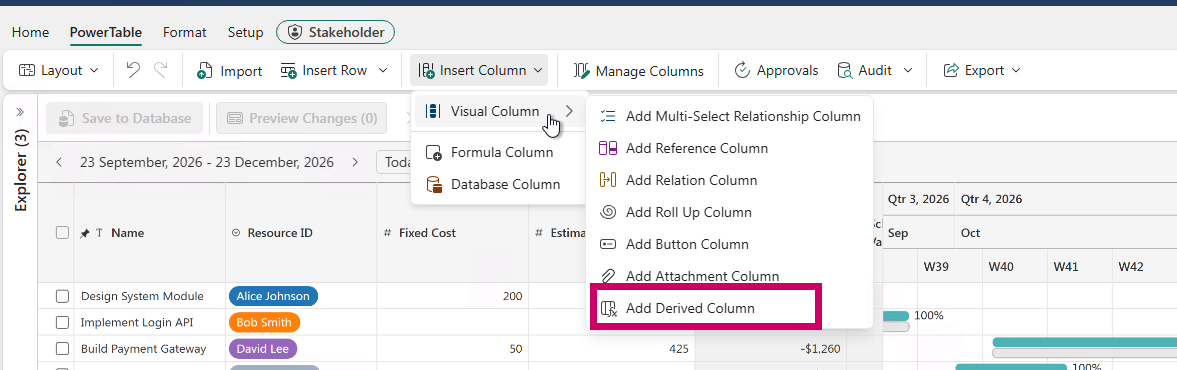
Where to find it: On a Gantt layout, PowerTable › Insert Column › Visual Column › Add Derived Column.
This release helps teams spend less time wrangling data and more time acting on it. Because it all runs on your Fabric data, everything stays in one governed place.
Start with the update closest to a challenge your team has today: a sensitive column, a product table full of empty cells, or a board that’s always overloaded. Turn it on, and see what changes.
Secure data, flexible structure and plans that build themselves, all in the place your teams already work.
Feature details reflect Fabric Plan at the time of writing.
The Native Planning Engine stores planning data and application metadata as files in OneLake. That one architectural shift, together with optimizations across the product, makes Fabric Plan faster from the first click to the final writeback.
This is Part 3 of our three-part Native Planning Engine series, covering the Fabric Plan performance improvements beyond calculation and writeback. Part 1 introduces the Native Planning Engine, and Part 2 covers writeback to OneLake.
Covered in Parts 1 and 2: 10× more scale (12M cells), 10× faster calculation and up to 13× faster writeback.
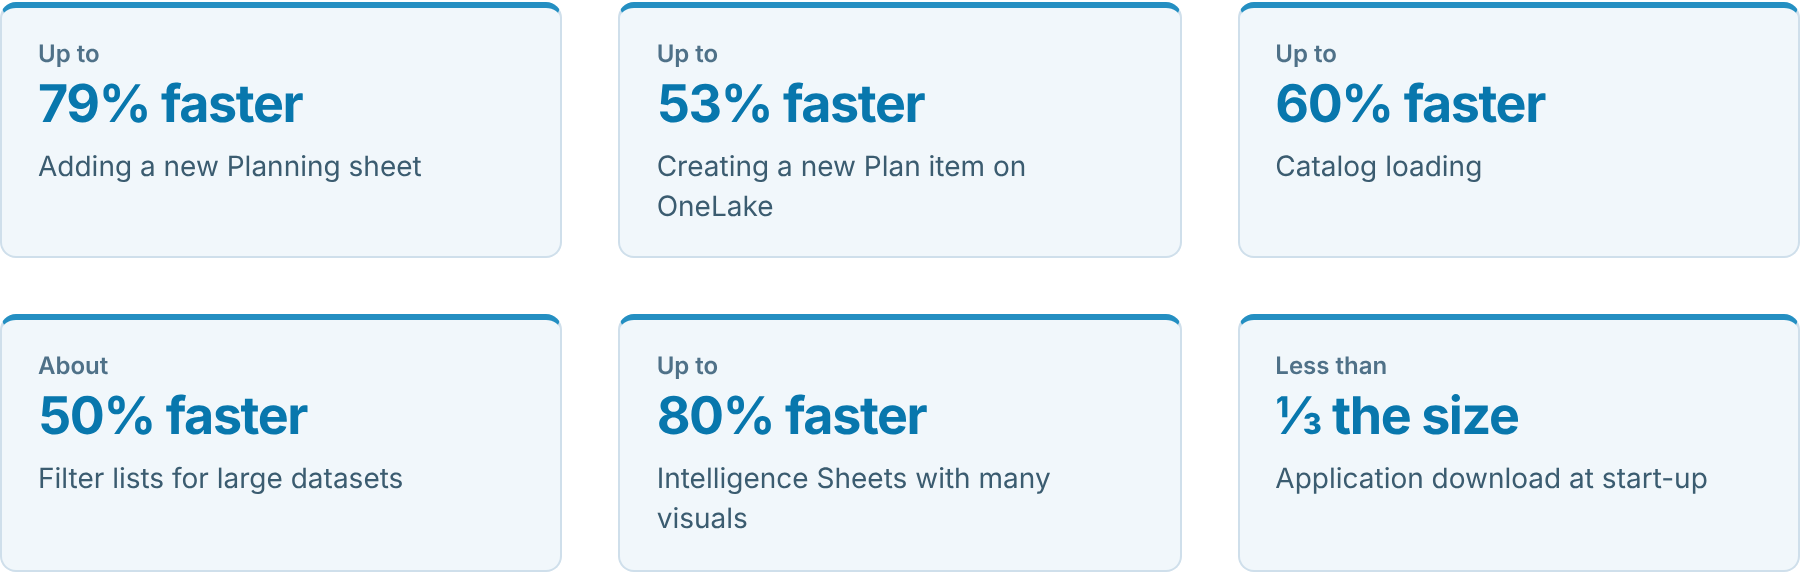
Figures come from our testing. Performance varies with workload, model design, data size and capacity.
With the Native Planning Engine, planning data and application metadata are stored as files in OneLake, and Plan items no longer need a separate system database. The benefits go well beyond the calculation and scale gains in Part 1 and the writeback gains in Part 2: creating and opening Plan items, adding Planning sheets and returning to views you use often are all faster too.
We also optimized start-up, the catalog, filters and Intelligence Sheets. Some of these improvements reach every Plan item; the full set comes with the Native Planning Engine and OneLake.
In this article:
The same everyday tasks, from launch to writeback, before and after the Native Planning Engine and OneLake.
| What you do | Before | After | Change |
|---|---|---|---|
| Launch Fabric Plan | A large application to download first | A compact package that loads quickly, even on slower networks | Less than ⅓ the size |
| Create a Plan item | Set-up took about twice as long | Ready for planning in about half the time | Up to 53% faster |
| Open a Plan item | Slower to open | Opens up to a third sooner | Up to 33% faster |
| Add a Planning sheet | Adding a sheet took up to five times as long | New sheets are ready in a fraction of the time | Up to 79% faster |
| Browse the catalog | The full catalog loaded up front | Each section loads as you open it | Up to 60% faster |
| Open a filter | Long member lists took time to appear | Lists appear with only the members you need | About 50% faster |
| Plan at scale | Up to 1.2 million cells in aggregate | Up to 12 million cells in aggregate (Part 1) | 10× more scale |
| Calculate the plan | Calculations on the previous planning engine | In-memory calculation on the Native Planning Engine (Part 1) | 10× faster |
| Load an Intelligence Sheet | Visuals competed for shared resources while loading | Visuals load side by side without waiting on each other | Up to 80% faster |
| Return to a view you use often | Data was fetched again each time | A fast local copy is used first | Faster repeat visits |
| Write back results | SQL-based writes | File-based Delta Parquet writes directly to OneLake (Part 2) | Up to 13× faster |
What it means for your team: less waiting during planning sessions, more scenarios tested before a deadline, and a tool that more people keep using.
Some of the result depends on how your environment is set up. These four steps make the biggest difference.
The file-based architecture is what unlocks the full set of improvements in this blog. Plan items still on the previous planning engine miss many of them.
Turn on Store new Plan items in OneLake at the tenant and workspace levels, start with new Plan items, then migrate your existing ones gradually. Part 1 walks through each step.
Saving planning results to OneLake makes everything above even more effective. Your plans, forecasts and assumptions sit in one governed place, and reporting across Fabric reads them directly.
File-based Delta Parquet writes to OneLake are about 5–6× faster than SQL-based writes at typical volumes and up to 13× faster at 12M cells. Fabric SQL remains a fully supported writeback destination. Part 2 shows how to set it up.
Fabric Plan reads data from your semantic model, and how long that takes depends on how well the model performs.
Outside Fabric Plan’s scope. The improvements in this blog cover what happens inside Fabric Plan. They do not change how quickly your semantic model loads. If you want data to arrive faster, work with your semantic model owner to keep the model well designed and efficient.
The more detail a planning sheet holds, the more work it has to do. Detail that nobody plans against makes the sheet slower without adding value.
For scaling techniques such as context filtering, dimension partitioning, cubes and PowerTable, see Key Considerations for Planning at Scale with Microsoft Fabric Plan.
Move your Plan items to the Native Planning Engine, write back to OneLake, and keep your data model and sheets lean. You get faster planning everywhere, from the first click to the final writeback.
Start with Part 1: turn on the Native Planning Engine, then Part 2: write back to OneLake.
Learn more in the Fabric Plan documentation and on Microsoft Learn.
For readers who want to know what changed behind the scenes at each step.
Improvements are described as “up to” or approximate figures, and results vary with workload, model design, data size and capacity.
Write back Fabric Plan results as Delta Parquet, use them in Direct Lake semantic models, and reuse them across Fabric.
This is Part 2 of our three-part Native Planning Engine series. Part 1 introduces the Native Planning Engine, and Part 3 covers the performance improvements across Fabric Plan.
Alongside the brand new Native Planning Engine, now in Public Preview (Part 1), Fabric Plan now supports writeback to OneLake as a new writeback destination, in Delta Parquet format.
Writeback outputs land as Delta tables in OneLake. You can add them to a semantic model in Direct Lake mode and reuse them across Fabric through lakehouse shortcuts, without another copy of the data. Fabric SQL remains a fully supported writeback destination.
This post assumes your Plan items run on the Native Planning Engine. If they don’t yet, turn it on first (Part 1).
In this article:
Choose OneLake to write back as Delta Parquet. File-based writes are about 5–6× faster than SQL-based writes at typical volumes, rising to 13× at 12M cells, and are tested up to 50 million cells per writeback instance. Fabric SQL remains fully supported and is a great fit for writeback up to 2.4 million cells and for SQL-based workflows.
| Writeback capability with the Native Planning Engine | Writeback destination: Fabric SQL | Direct writeback to OneLake |
|---|---|---|
| Destination support | Fabric SQL (fully supported) | OneLake (direct writeback) |
| Cells per writeback instance | 2.4M recommended | 50M tested |
| Writeback speed | 3 mins | 30 sec (about 6× faster) |
| Output format | SQL tables | Delta Parquet in OneLake |
Writeback speed measured at 2.4M cells. See Writeback performance for every volume tested. Actual speed depends on data volume, workload and capacity.
Approximately 5–6× faster at typical customer volumes. Most customers write back 1.2M–2.4M cells; those volumes are marked as typical below. The gap widens as volume grows, reaching 13× at 12M cells, because of the write approach: SQL-based writes versus file-based Delta Parquet writes.
| Volume (cells) | Writeback to Fabric SQL (SQL-based writes) | Direct writeback to OneLake (file-based Delta Parquet writes) | Approx. speedup |
|---|---|---|---|
| 120K | 13 sec | 6 sec | 2× faster |
| 480K | 30 sec | 9 sec | 3× faster |
| 1.2M (typical) | 1 min 09 sec | 15 sec | 5× faster |
| 2.4M (typical) | 2 min 54 sec | 30 sec | 6× faster |
| 4.8M | 10 min 11 sec | 52 sec | 12× faster |
| 12M | 22 min 29 sec | 1 min 40 sec | 13× faster |
| 30M | Not tested | 4 min 15 sec | N/A |
| 50M | Not tested | 9 min 05 sec | N/A |
Speedup = SQL-based writeback time ÷ file-based OneLake writeback time, rounded to the nearest whole number. SQL-based writeback was not tested at 30M and 50M cells. Actual times depend on workload, model design and capacity. Writeback volume is counted per writeback instance and is separate from the interactive planning grid, which supports up to 12 million cells in aggregate on the Native Planning Engine (see Part 1). On our roadmap, OneLake writeback will extend to support 120 million cells and beyond, matching the planning grid roadmap in Part 1.
The workflow: Plan → OneLake (Delta Parquet) → Direct Lake semantic model.
Open the Plan’s Writeback tab and select Add destination.
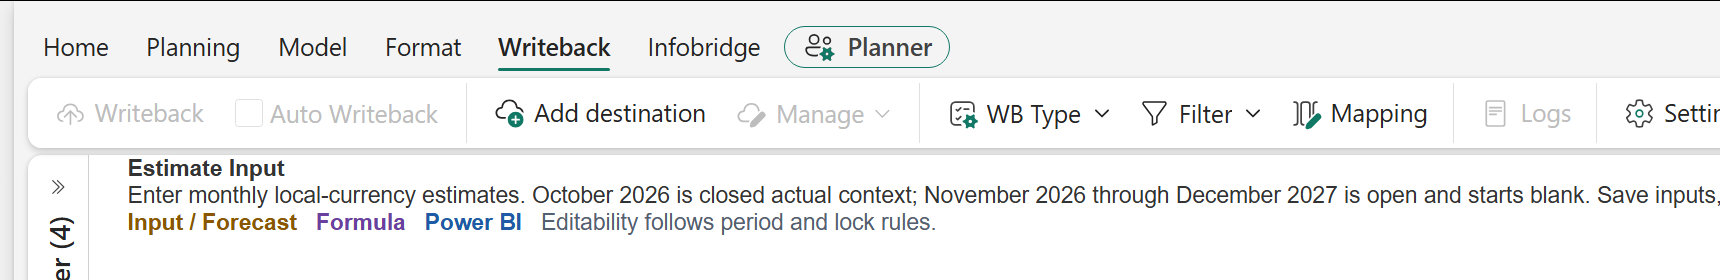
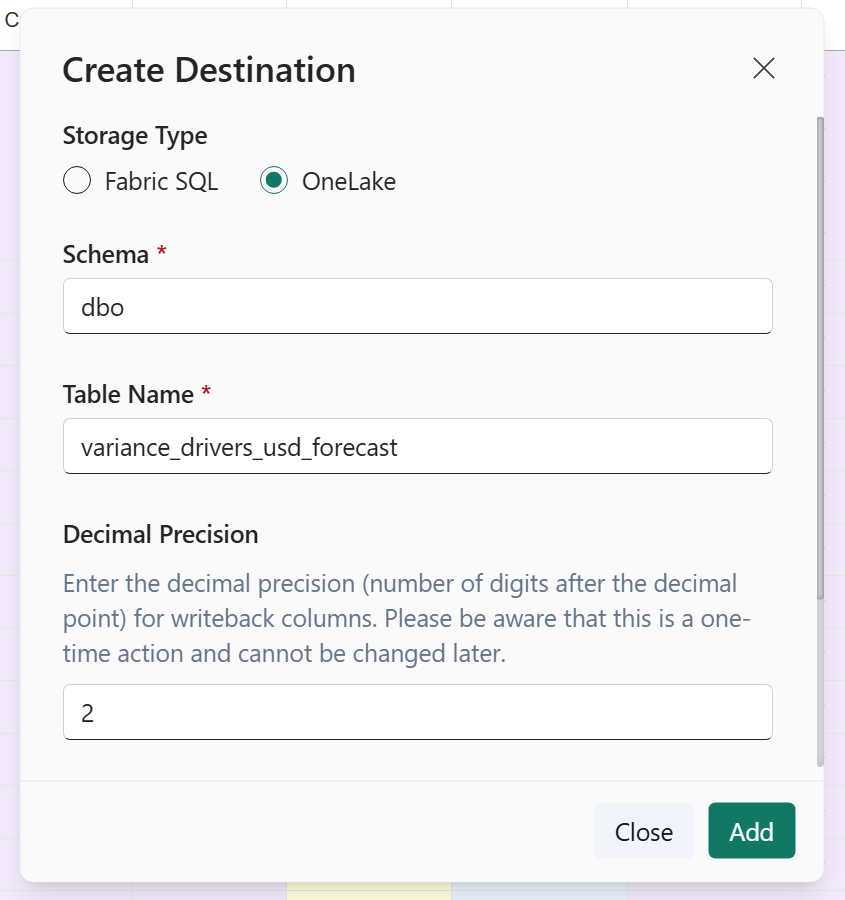
In Create Destination, select OneLake. Enter the Schema, Table Name, and Decimal Precision, then select Add.
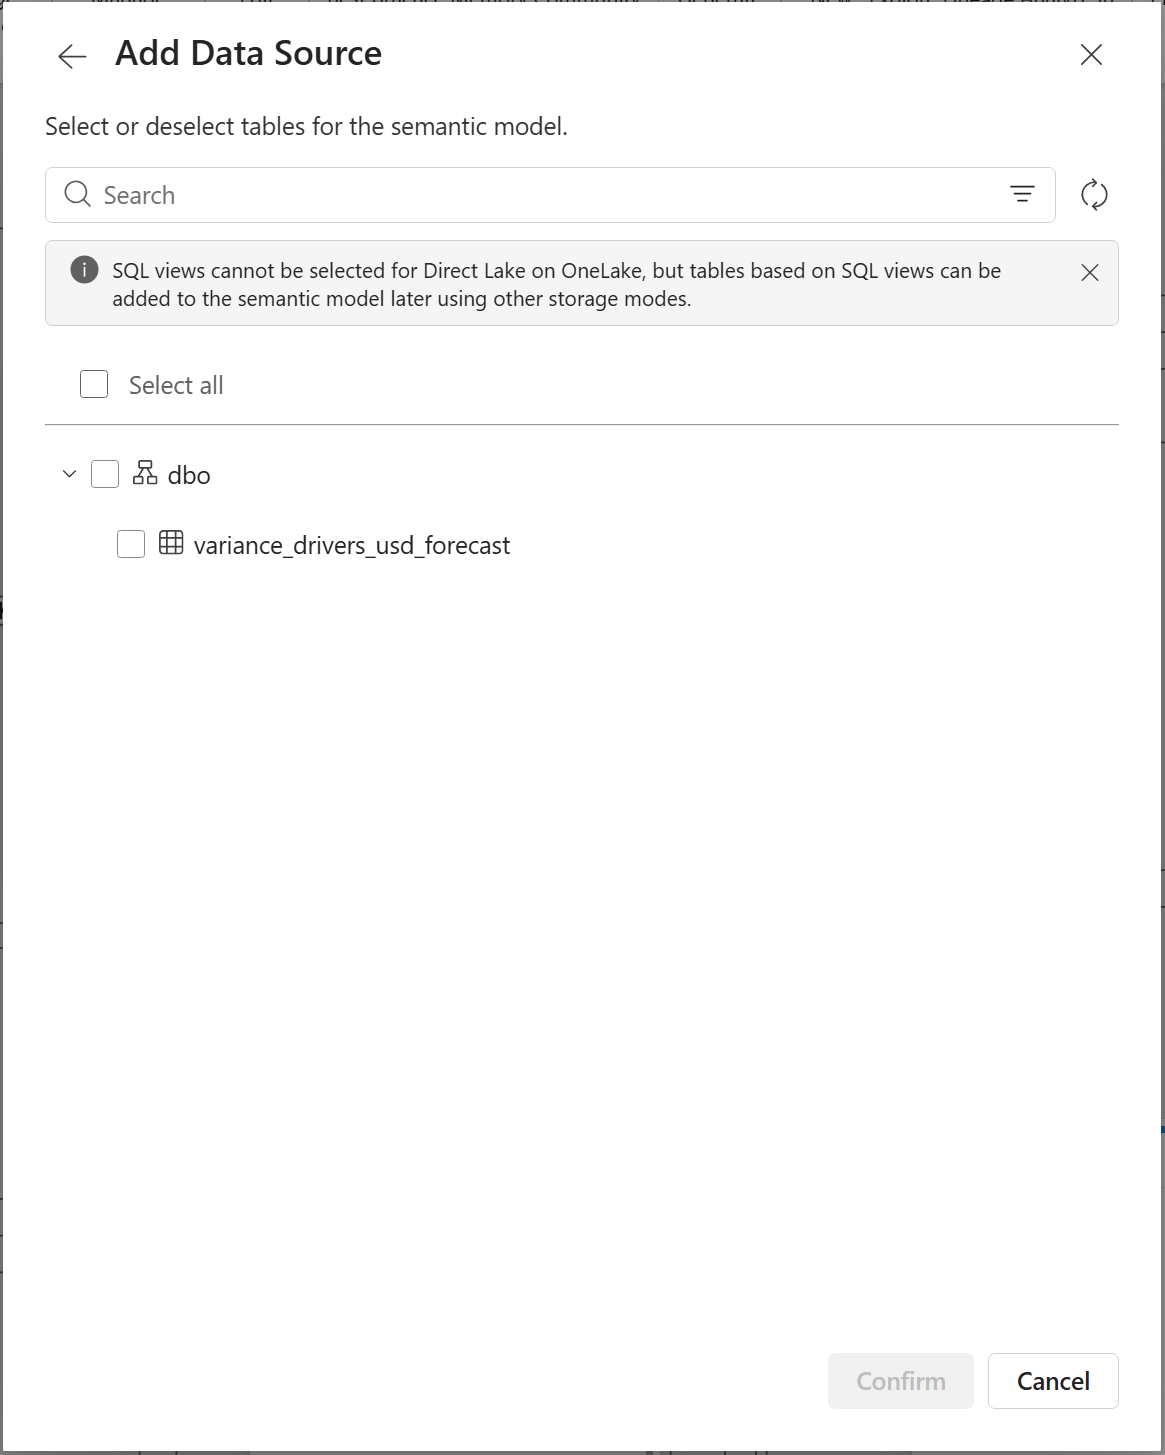
The example uses dbo, variance_drivers_usd_forecast, and two decimal places. The dialog notes that decimal precision cannot be changed later.
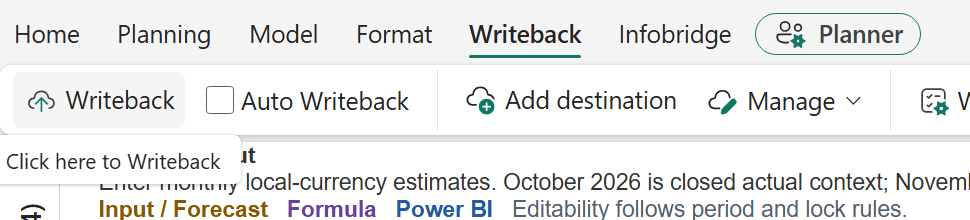
Select Writeback. When the operation finishes, the Plan displays Writeback completed.
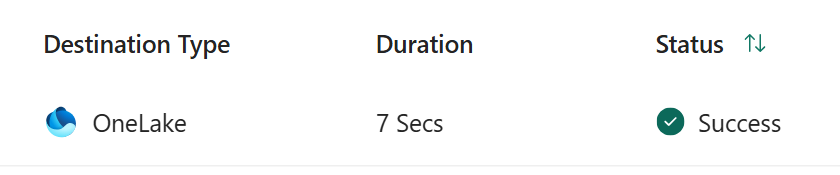
Open Logs and confirm Destination Type: OneLake and Status: Success.
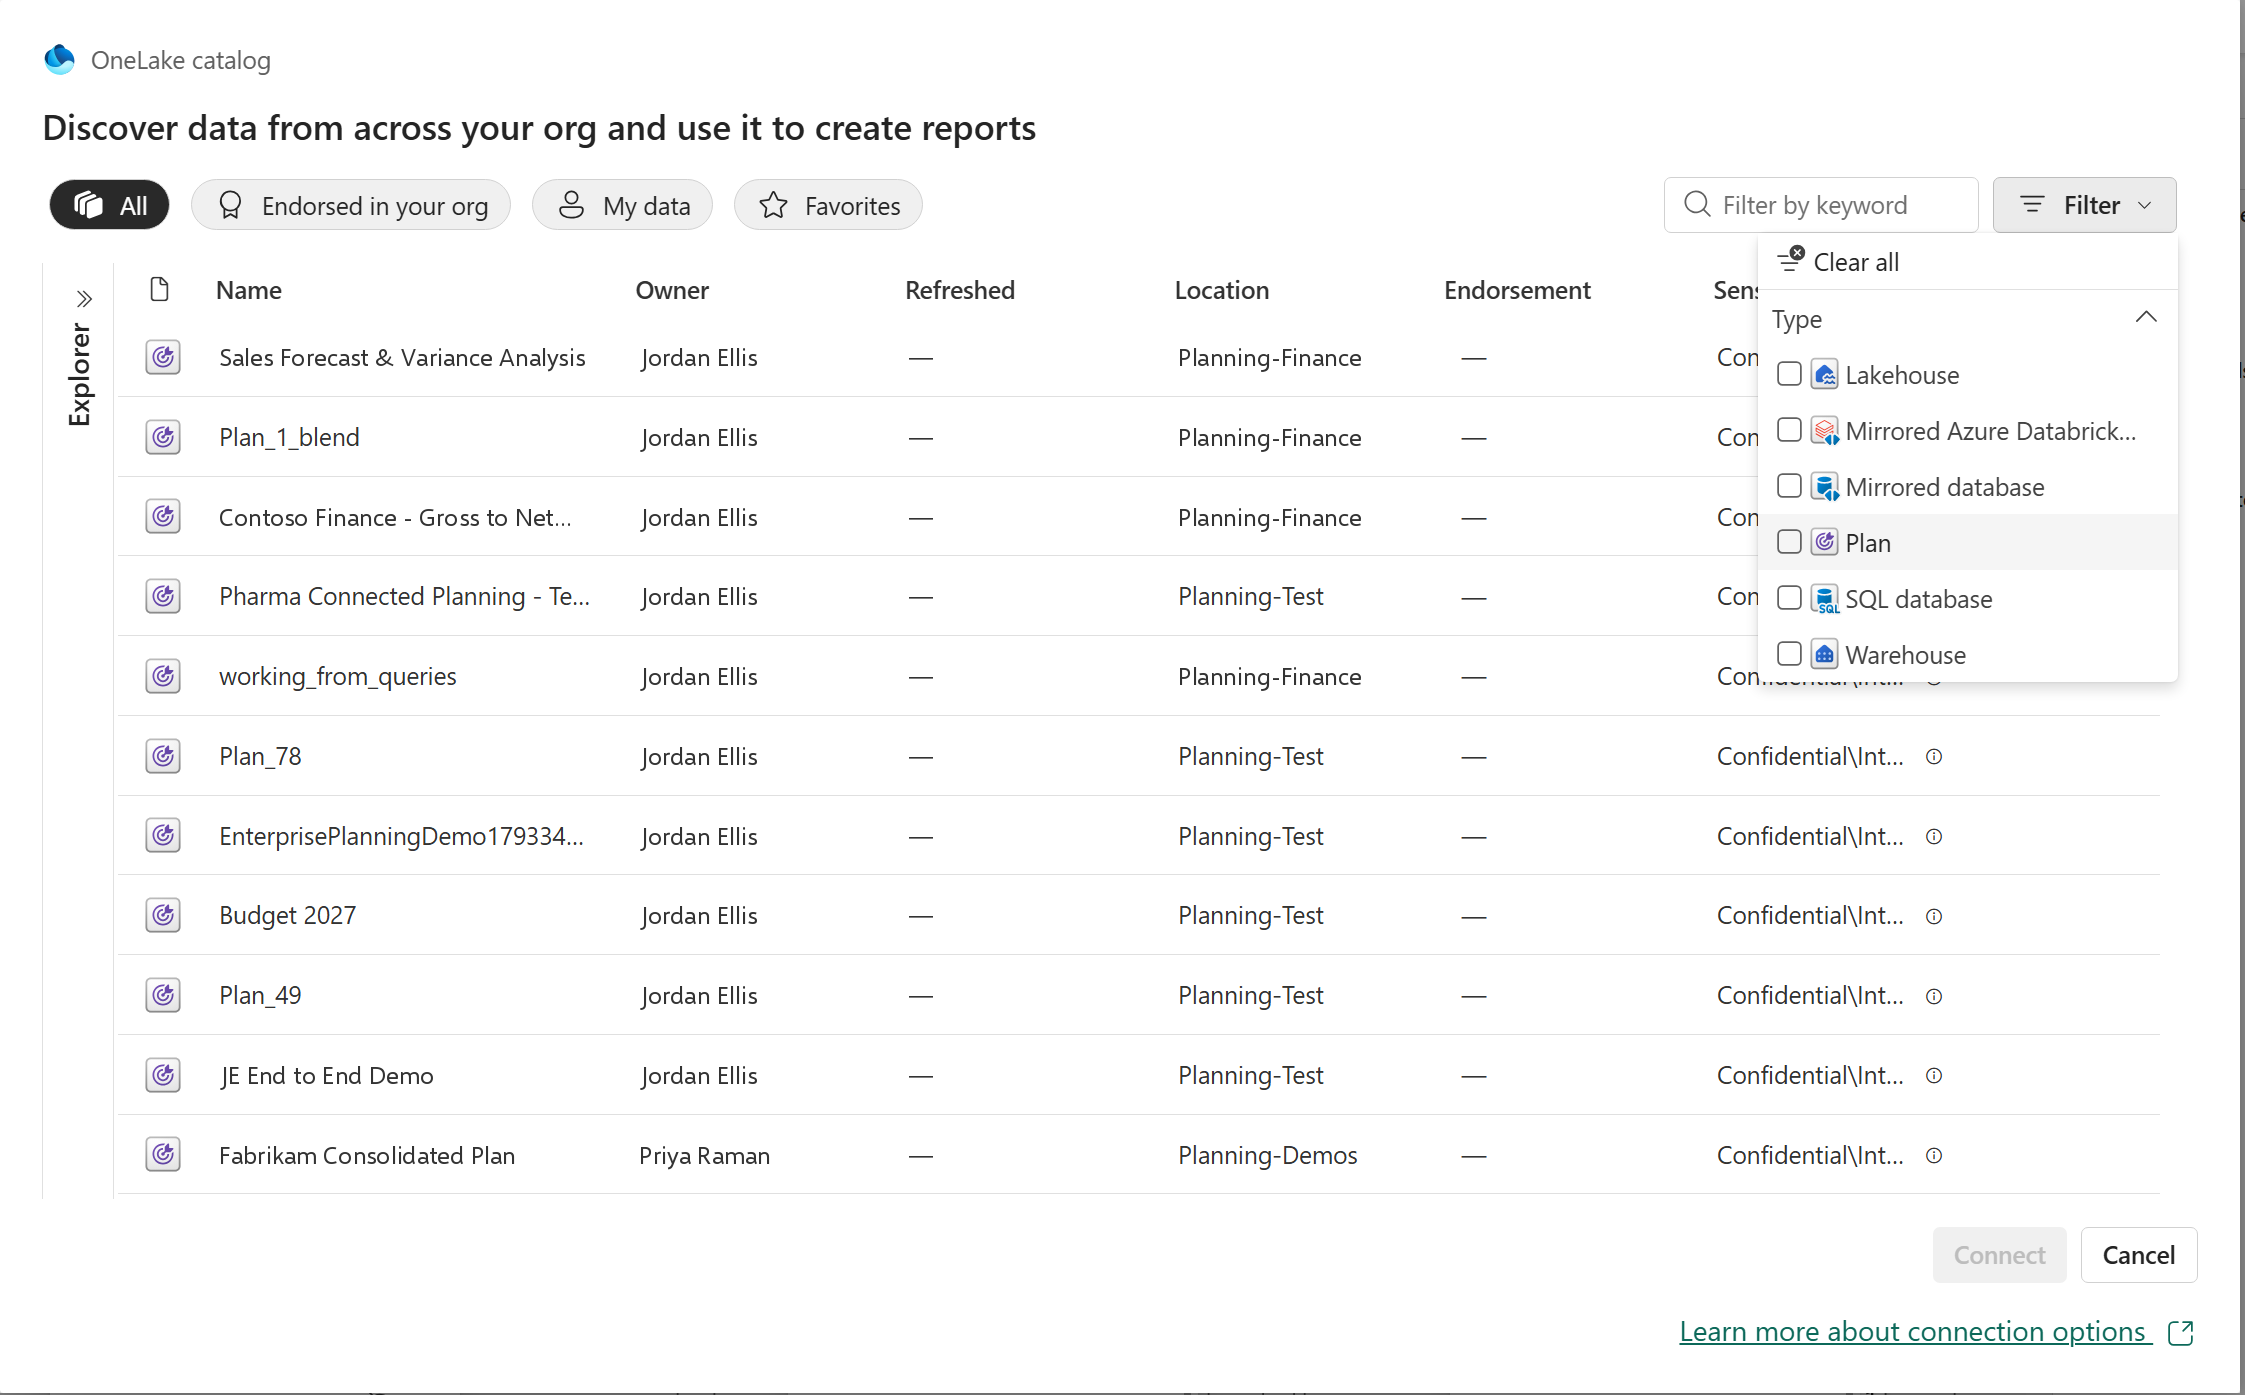
Plan items are now a supported source in the OneLake catalog. Each Plan item can contain multiple writeback tables; choose the ones your semantic model needs.
In the semantic model editor, select OneLake catalog. Open the top-right Filter, choose Type → Plan, select the Plan item, and select Connect.
The Add Data Source dialog lists the available writeback tables in the selected Plan. Expand the schema, select one or more tables, and select Confirm.
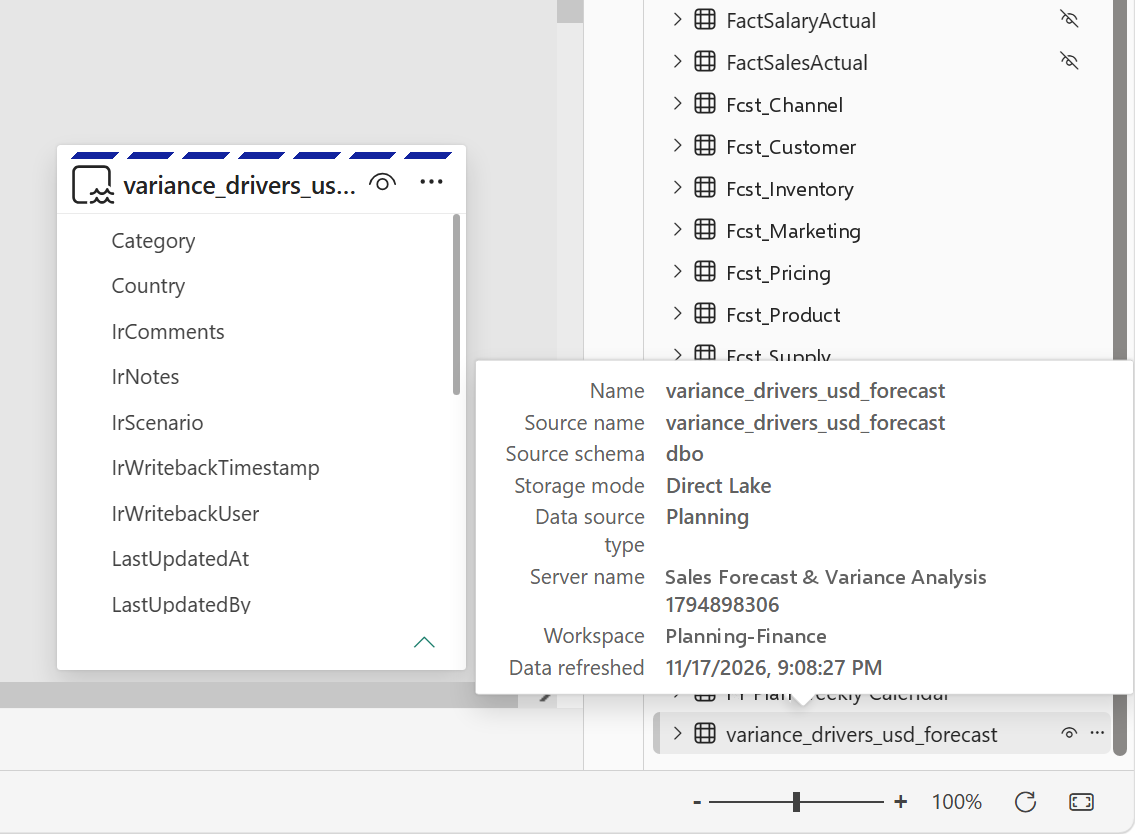
The selected table is added to the semantic model in Direct Lake mode. Hover over the table to inspect its details: Storage mode shows Direct Lake, and Data source type shows Planning.
Create a shortcut in the lakehouse’s Tables area that points to the Plan’s Delta table in OneLake. The lakehouse can use the table without another copy of the output. About OneLake shortcuts
With the writeback table available through the lakehouse, bind it to the relevant entity types and properties in Fabric ontology. This brings planning outputs into the business relationships used by that ontology. Ontology data binding
The reuse path: OneLake writeback table → Lakehouse shortcut → Ontology.
To start pipelines, refreshes or alerts automatically after each writeback, see Writeback that sets work in motion.
The screenshots show the writeback and semantic-model workflow; observed run times are examples, not performance guarantees.
A brand new in-memory engine for planning in Microsoft Fabric, with 10x+ improvements in both performance and scale. No separate system database is required anymore.
This is Part 1 of our three-part Native Planning Engine series. Part 2 covers writeback to OneLake, and Part 3 covers the performance improvements across Fabric Plan.
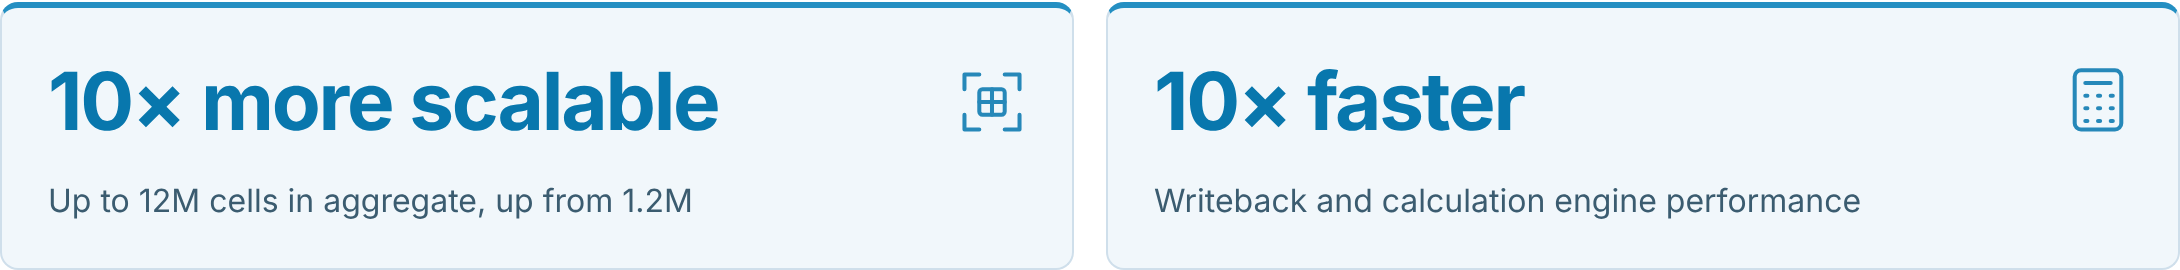
The scale figure compares the Native Planning Engine’s 12M-cell aggregate limit with 1.2M cells on the previous planning engine. The calculation figure is compared with the March preview; for writeback, the full benchmark in Part 2 shows up to 13× at 12M cells. Performance varies with semantic model design and capacity. For every user-facing improvement, see Part 3.
You can now enable the Native Planning Engine in Tenant settings as a Public Preview capability, as announced on our roadmap at FabCon Barcelona. Planning inputs are stored in OneLake as Apache Arrow files and loaded in memory for planning, so Plan items no longer need a separate system database.
We are also excited to share that you can now write back directly to OneLake as a new writeback destination, in Delta Parquet format. We cover that in Part 2: Writeback to OneLake.
In this article:
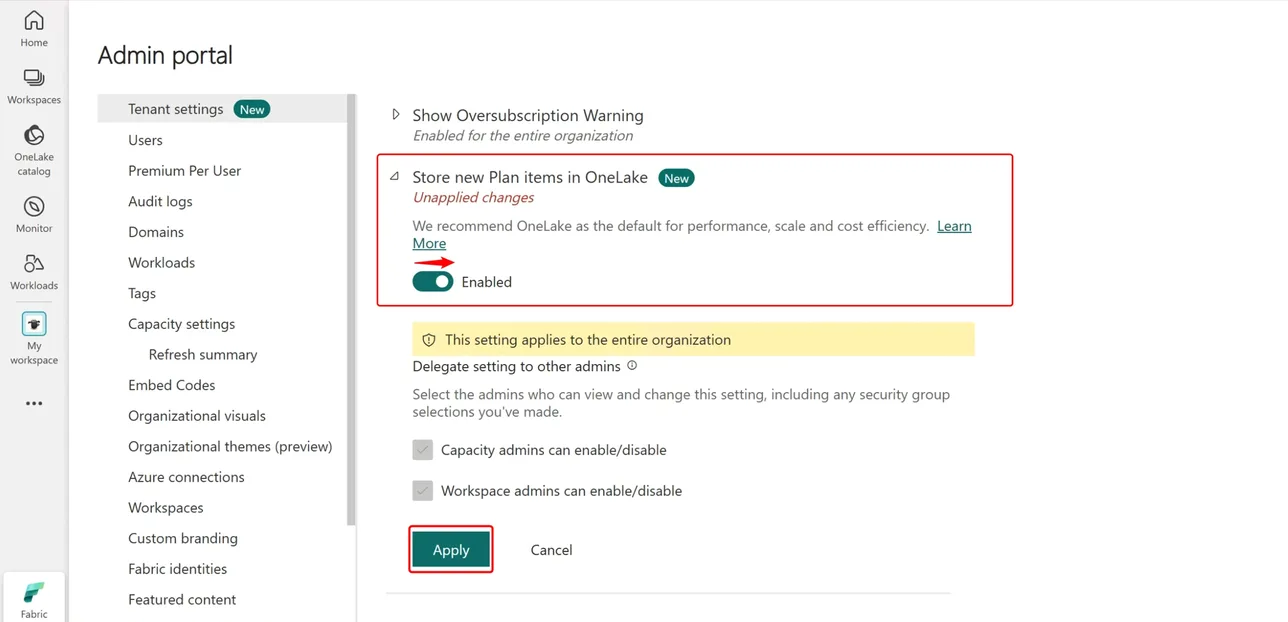
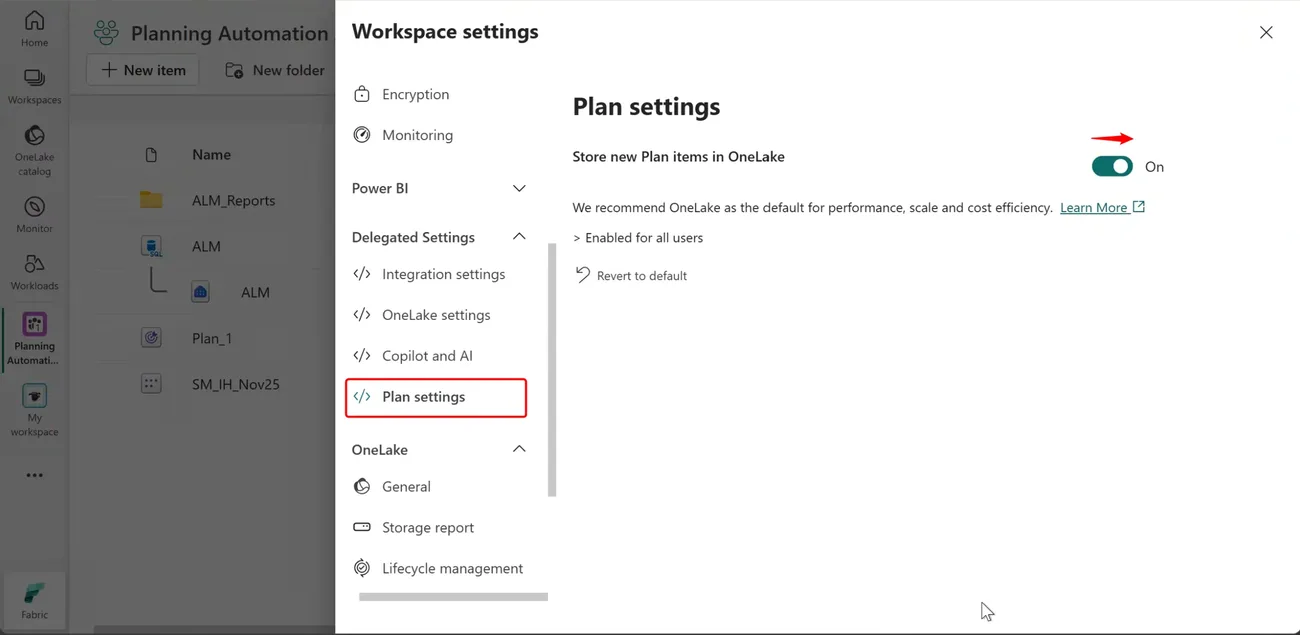
The Native Planning Engine is turned on by the Store new Plan items in OneLake setting. Once it is on, planning inputs are persisted in OneLake, and business output tables can write directly to OneLake as Delta Parquet. Turn the setting on at two levels.
Your Fabric administrator opens the Admin portal, goes to Tenant settings, turns on Store new Plan items in OneLake, and selects Apply.
In the workspace that holds your Plan items, open Workspace settings, go to Plan settings under Delegated Settings, and turn on Store new Plan items in OneLake.
At general availability, every remaining Plan item moves automatically. GA is planned in the next few weeks. Plan items still on the previous planning engine will be migrated to the Native Planning Engine, so we recommend moving and checking your key items during the preview.
Fabric Plan now runs on a brand new native, file-based, in-memory planning engine that raises the planning limit tenfold, from 1.2 million to 12 million cells in aggregate. Apache Arrow supports efficient planning data access, while Delta Parquet makes business writeback outputs available across Fabric.
Plan items no longer need their own system database. Planning inputs live in OneLake, so there’s one less item to provision and manage, and storage is billed as part of your Fabric capacity. Fabric SQL remains a fully supported writeback destination, and PowerTable uses it as its writeback database.
Power BI semantic models can be massive, from millions to billions of rows or more. Because Fabric Plan runs directly on top of those semantic models, it can support any number of dimensions, measures and scenarios. That sets it apart from other planning tools, where performance degrades as the number of dimensions, measures or scenarios grows.
Any planning method, with the controls to run it across every line of business.
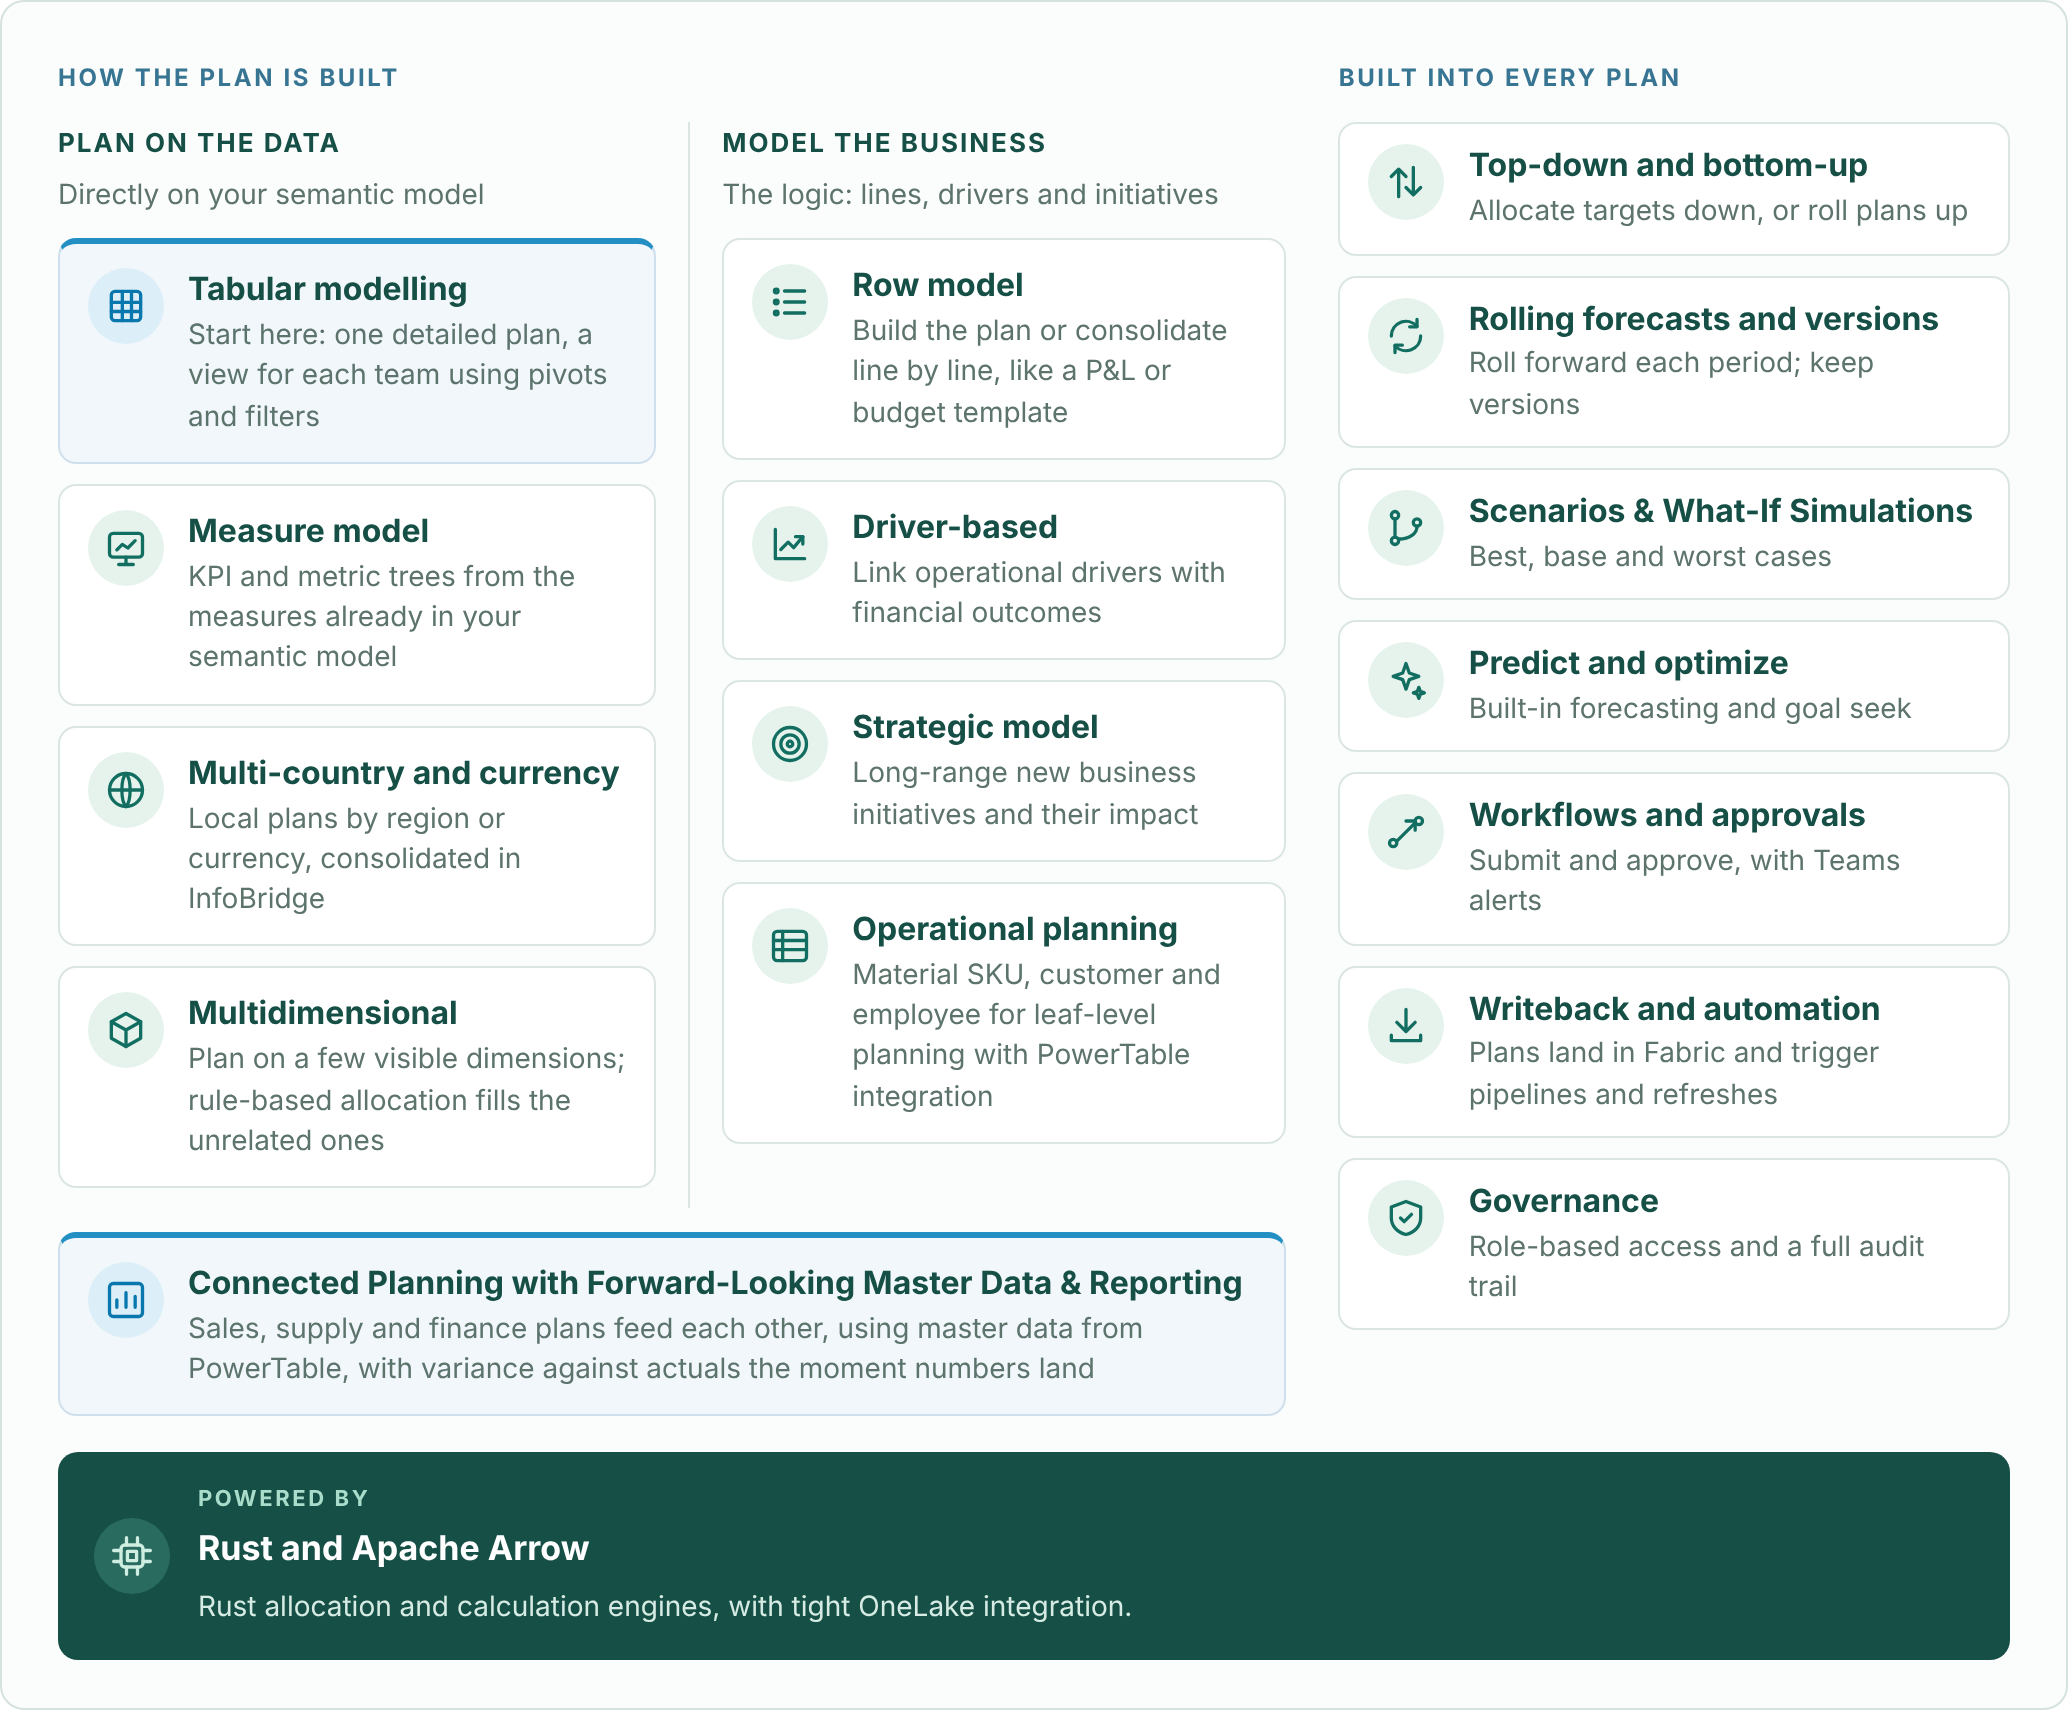
Go deeper: tabular modelling and choosing a planning method, measure models, row models, driver-based planning, operational planning with PowerTable, writeback and automation, and governance with Audit Cell History.
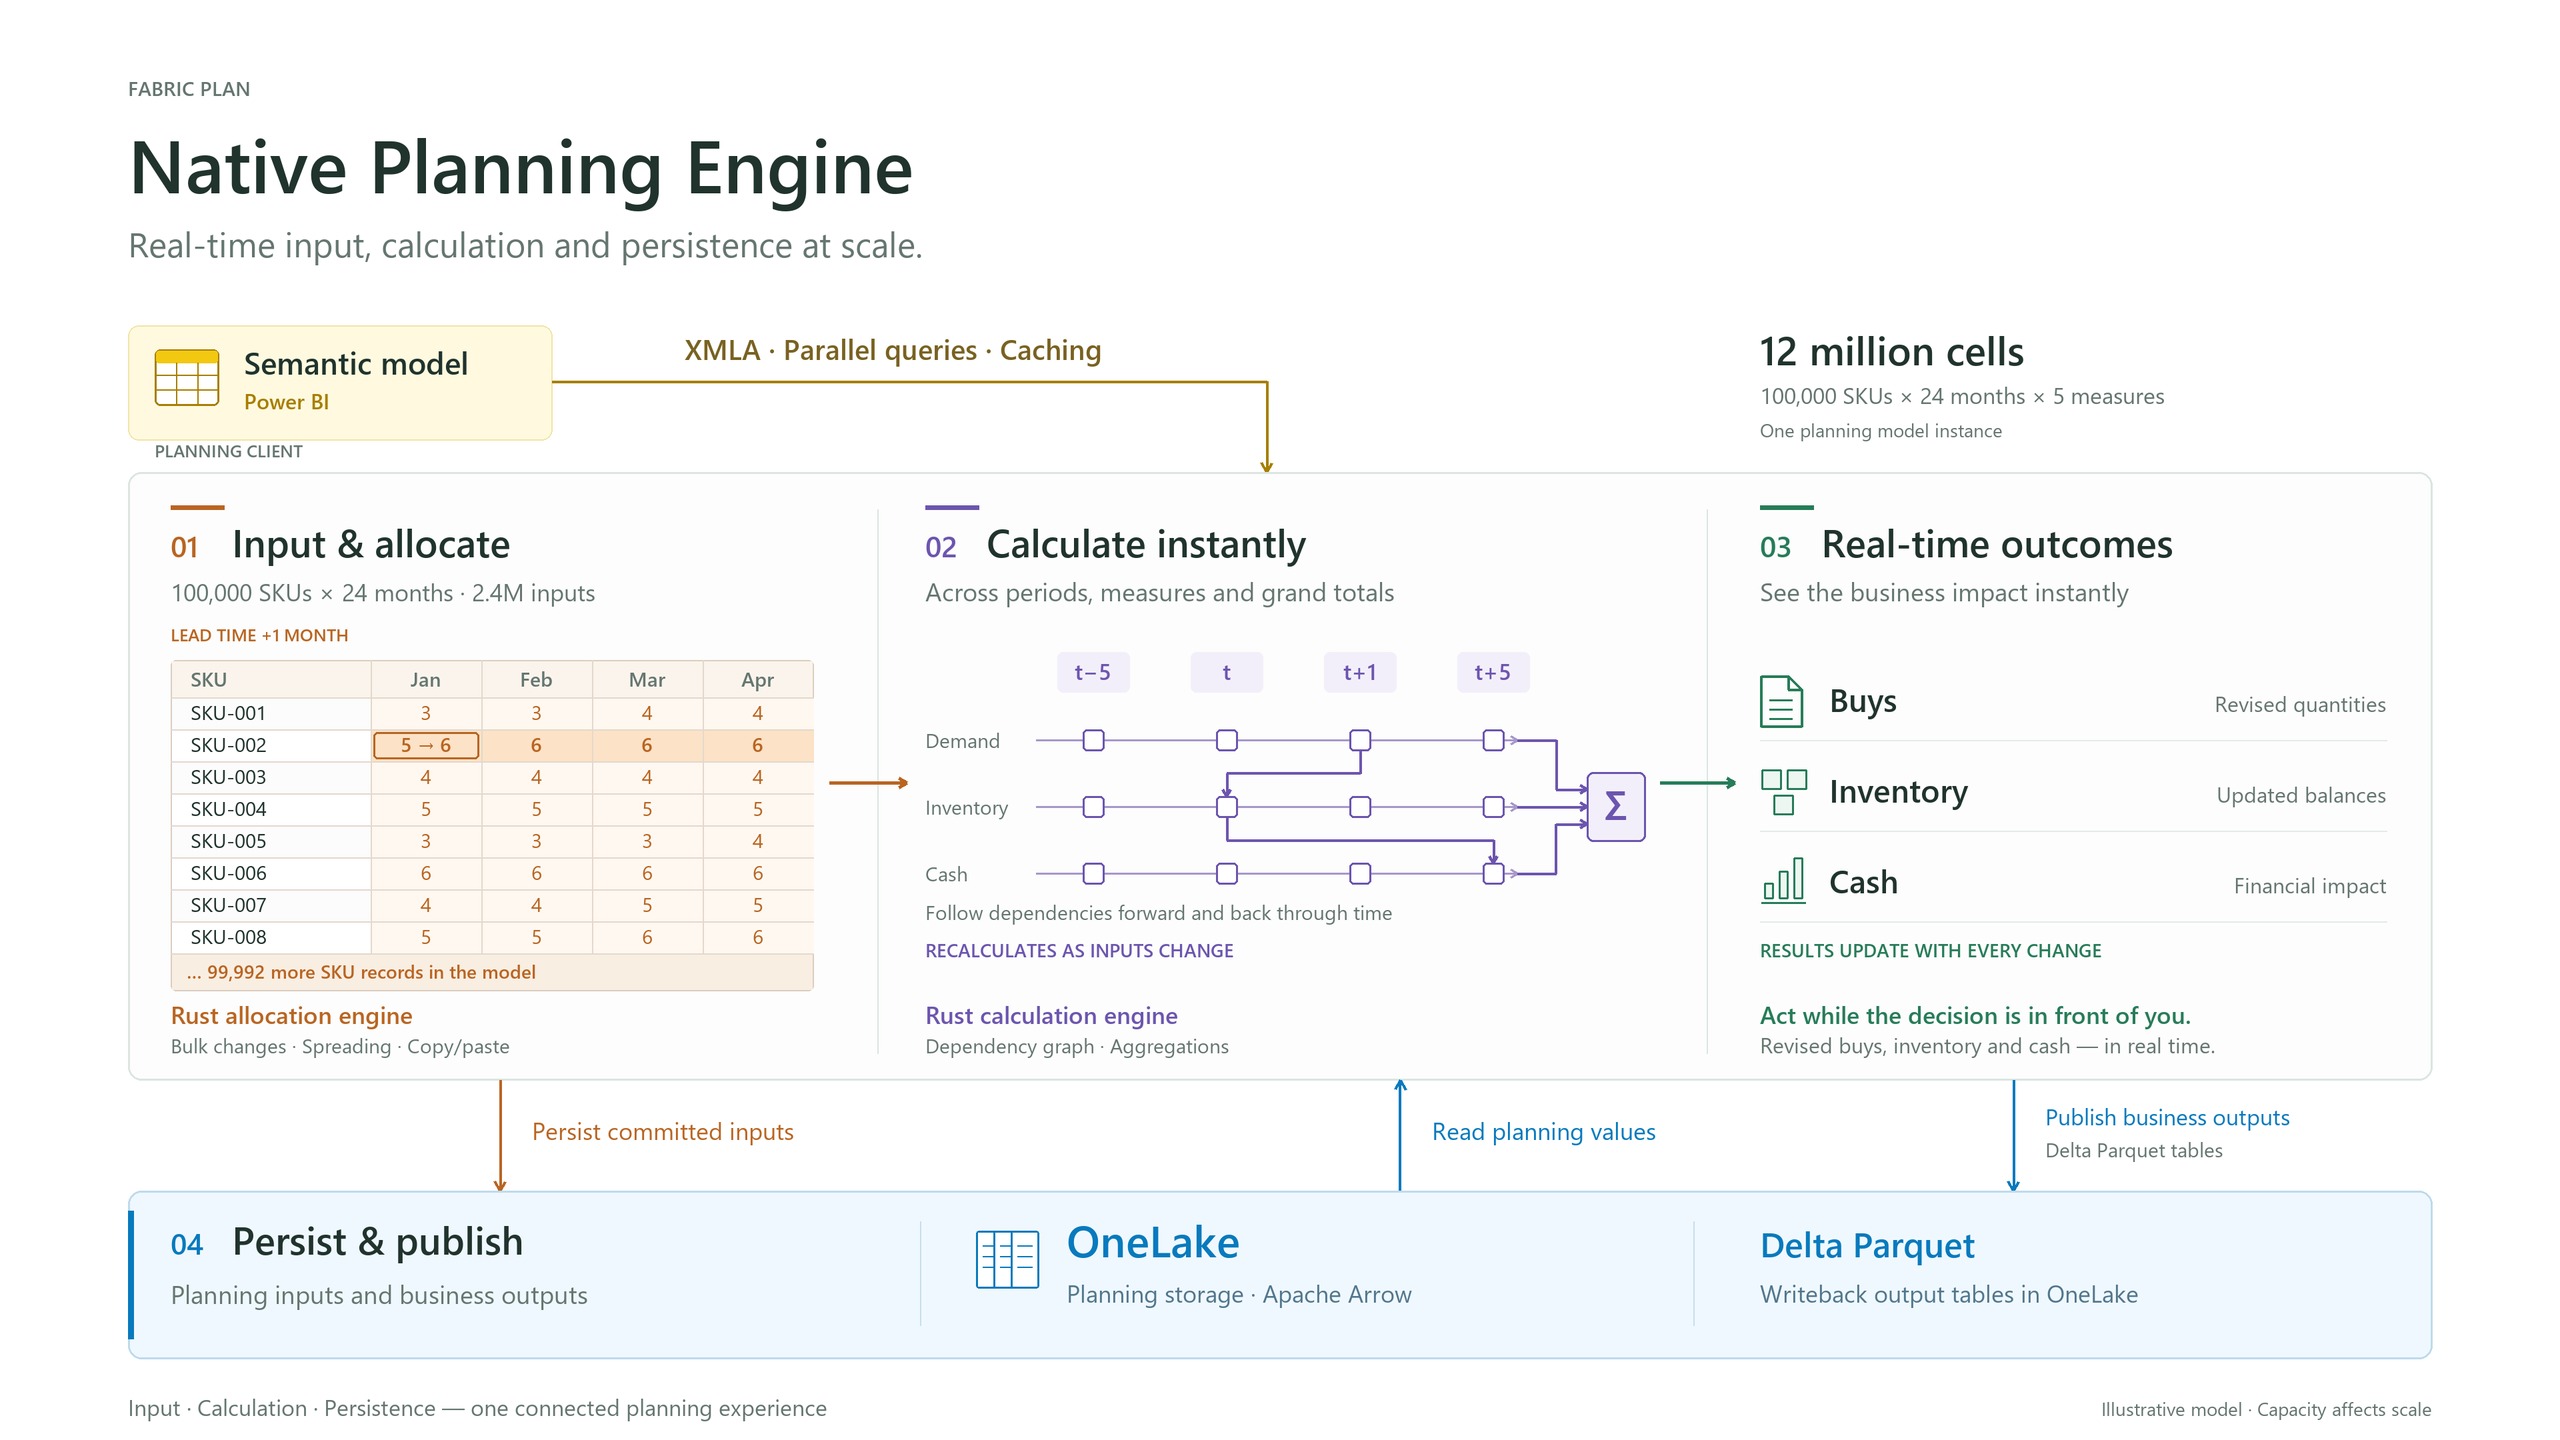
The illustration shows 12 million model cells, with 2.4 million cells affected by the bulk input operation.
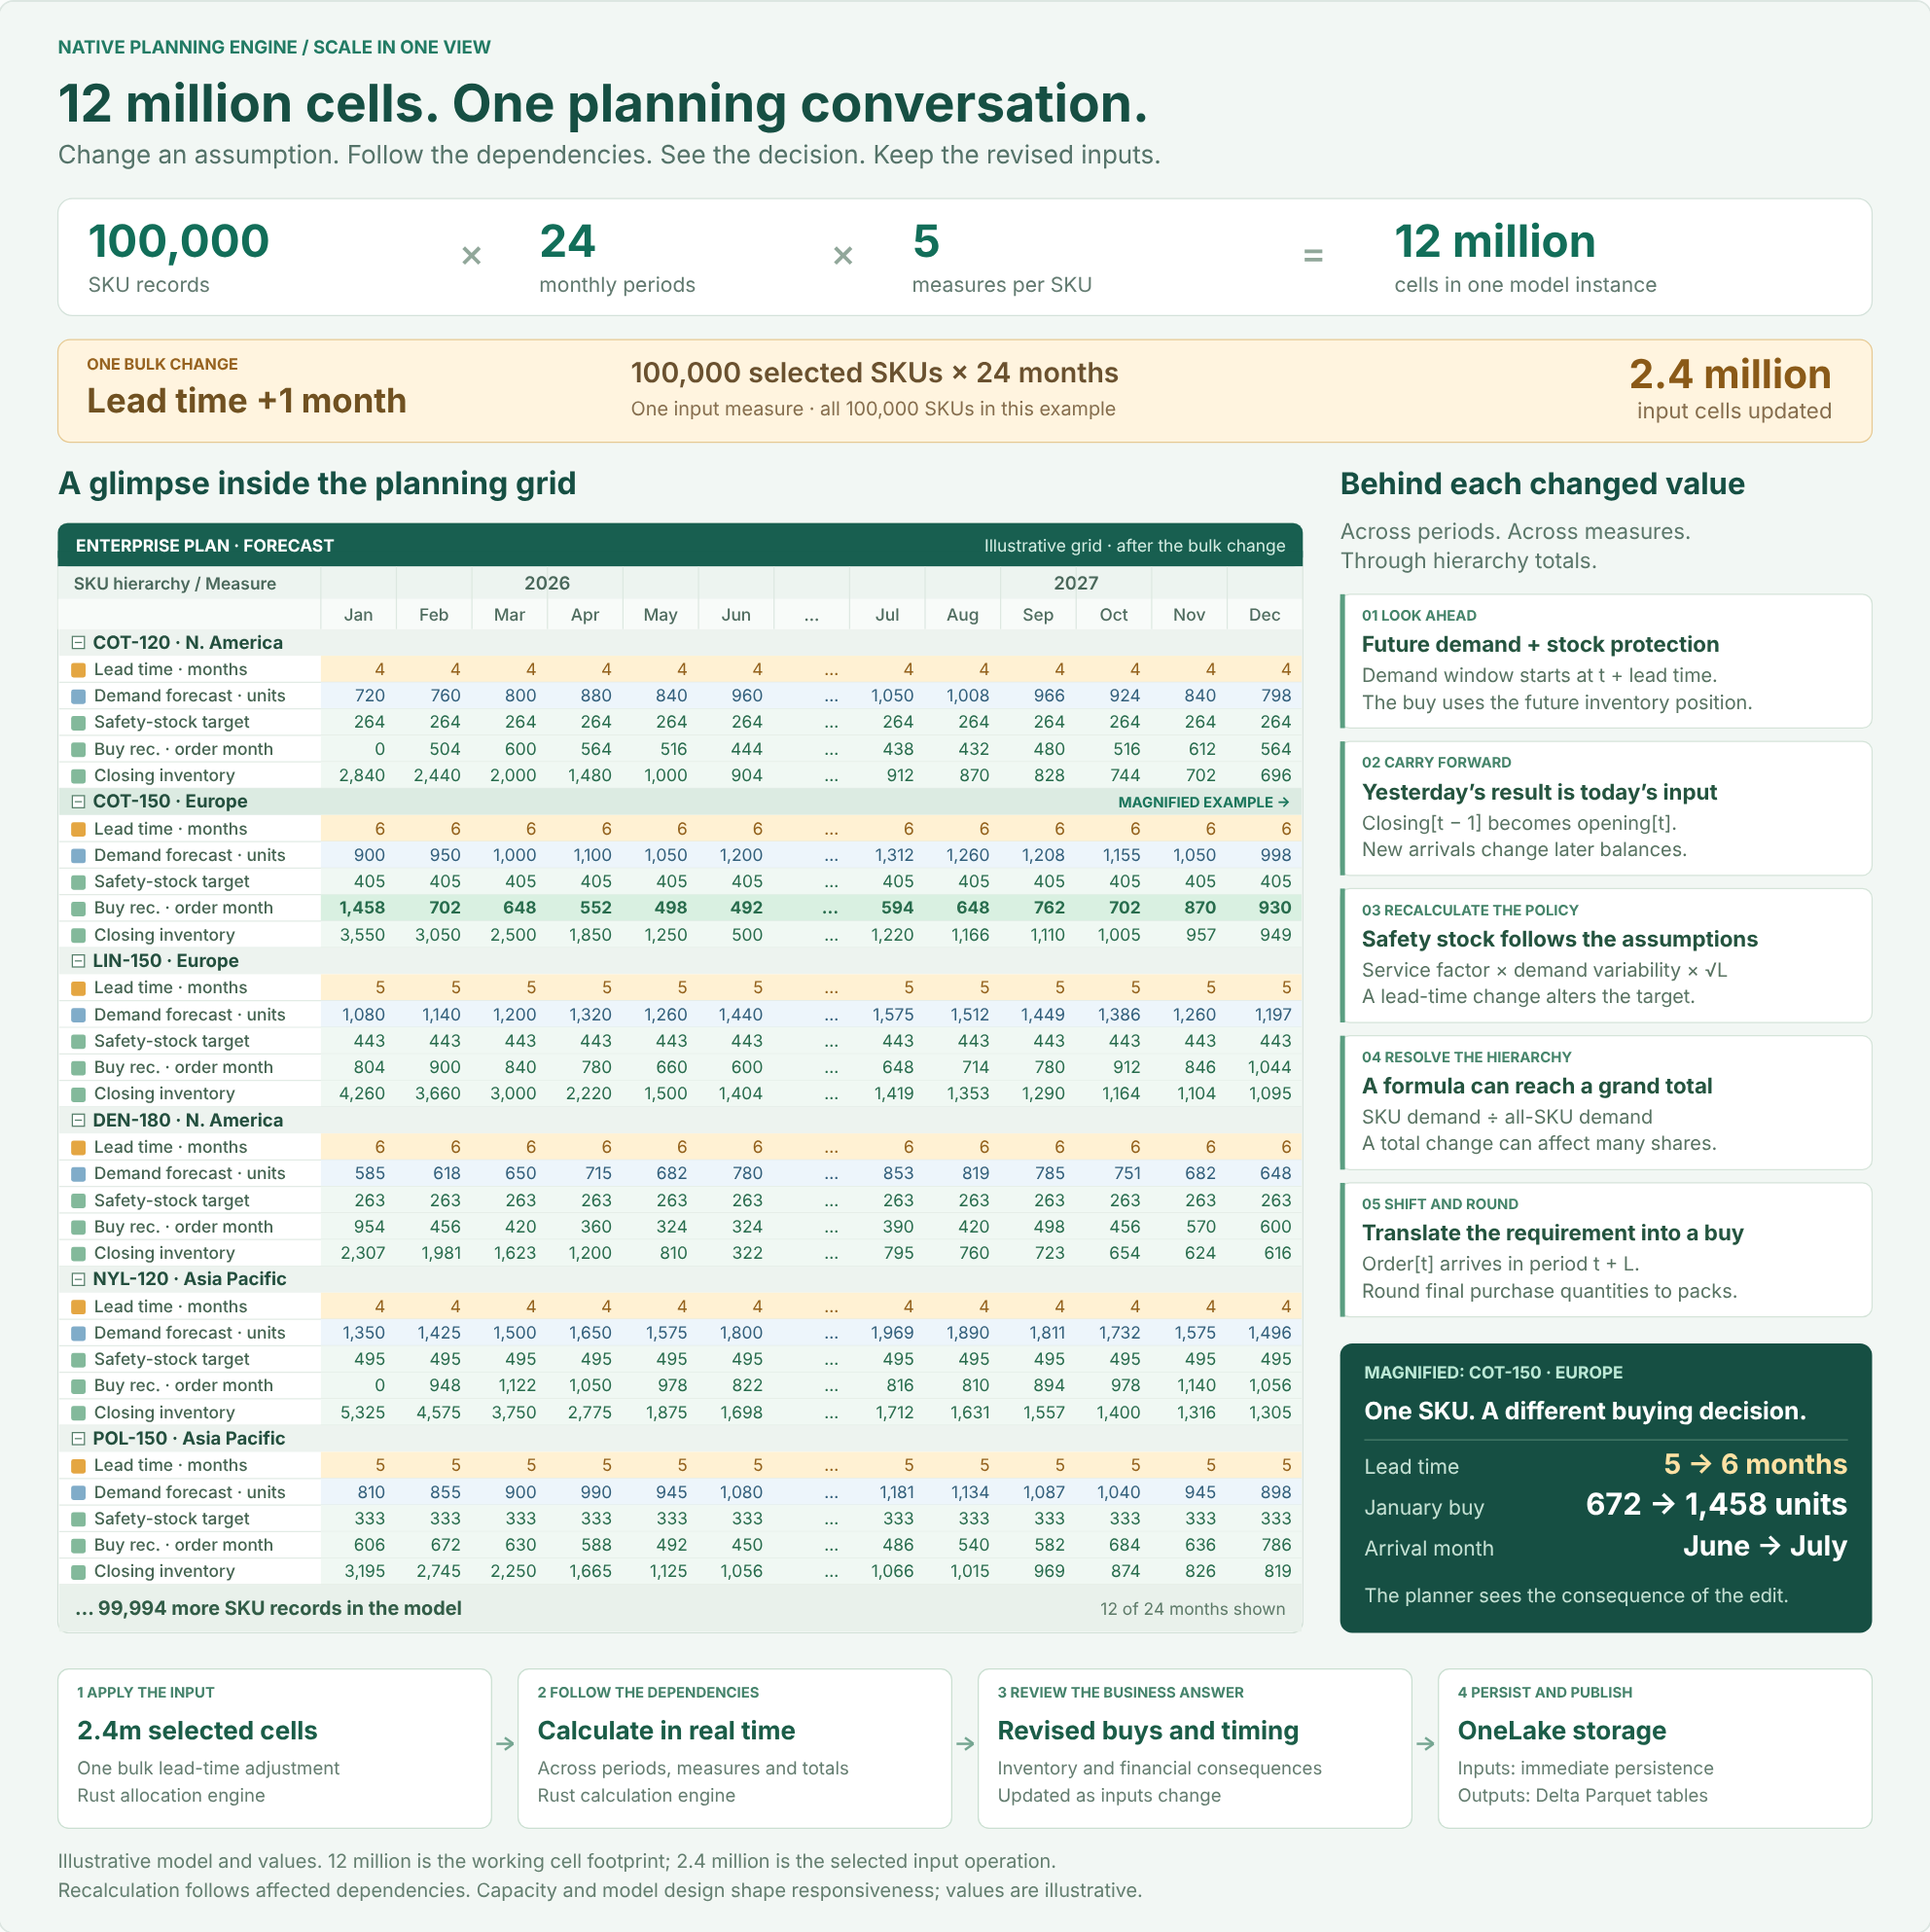
Data fetched through XMLA affects capacity and responsiveness. The size of an interactive planning model is distinct from the volume published in a writeback instance. For scaling techniques such as context filtering, dimension partitioning, cubes and PowerTable, see Key Considerations for Planning at Scale with Microsoft Fabric Plan.
Caution: watch your Power BI XMLA query and concurrency limits. Large plans can reach the XMLA query and concurrency limits of your Fabric capacity, which can cause throttling. Limits depend on your capacity size, so consider a larger capacity when you need to fetch more Actuals data per query from the semantic model.
With this release, the Native Planning Engine supports up to 12 million cells in aggregate, 10x the 1.2 million cells of the previous engine. That total covers Actuals fetched from your semantic model plus visual forecast and formula measures. Next on our roadmap is support for up to 120 million cells inside the planning grid, 100x the previous limit. At that point, the only limit will be how much data you can fetch efficiently from your semantic models without throttling. Data fetched through XMLA alone will be capped at around 12 to 24 million cells.
This is a forward-looking roadmap item; release timing may change.
The Native Planning Engine is our default recommendation going forward.
Advanced modeling features require OneLake storage. Audit cell history and driver-based modeling are available now, and snapshots (frozen versions) arrive on December 8, 2026. These capabilities are supported only by the Native Planning Engine: they require its file-based architecture and will not be supported by the previous planning engine.
Fabric SQL remains a fully supported writeback destination.
A Fabric administrator turns on Store new Plan items in OneLake in Tenant settings. The setting can be delegated so that capacity and workspace admins can enable or disable it, and it is then turned on for each workspace in Workspace settings → Plan settings. See Turn on the Native Planning Engine.
No. The setting applies to new Plan items. Existing items keep running on the previous planning engine until you migrate them, or until the automatic migration at general availability.
Yes, but not as the system database. Planning inputs are now stored in OneLake, which removes the need for a second database. PowerTable continues to use Fabric SQL as its writeback database, and Planning sheets continue to support Fabric SQL as a writeback destination, alongside OneLake writeback.
Migrating an item from Item settings moves that item to the new engine. Copying an item with deployment pipelines creates a new item without its data, which is useful for testing. The recommended path is to smoke test first: copy the item with deployment pipelines, check it on the Native Planning Engine, then migrate the original from Item settings.
No. Migration is one-way, so a migrated item can’t be moved back to the previous planning engine. Smoke test a copy first, as described above, before migrating the original.
Once every Plan item in the workspace has been migrated to OneLake, the Fabric SQL system database (the application database) can be safely deleted. If any Plan items in the workspace haven’t been migrated yet, leave the database in place so their metadata isn’t lost. Keeping it does no harm.
The pricing model doesn’t change: Fabric Plan is still billed by session type on your Fabric capacity. What changes is the other resources part of the bill. Instead of charges for a Fabric SQL system database, you now incur OneLake storage. See how Fabric Plan pricing works.
No. There are no known limitations during the preview.
The inventory illustration uses fictional data. Performance figures are examples, not performance guarantees.
Intelligence Sheets turns your Fabric data into reports people can read, analyze, and act on. Teams build variance reports, dashboards, and analysis on the same semantic model, security, and backend as the rest of Fabric Plan, with standard IBCS® notation and their plans in the same place. New to Intelligence Sheets? Start with What are intelligence sheets in planning? on Microsoft Learn.
Here’s what’s new in Intelligence Sheets for November 2026. This release brings enhancements across visuals for performance, integrated planning and reporting, security, and authoring experiences:
We have made significant improvements to performance and usability across building, reading, and sharing reports. You’ll notice the difference in how quickly reports load, how they respond as you work, and how comments behave during collaboration. These build on the platform-wide gains described in Part 3 of the Native Planning Engine series, including up to 80% faster loading for Intelligence Sheets with many visuals.
Embedded Planning Sheets in Intelligence Sheets now include the full Planning Sheet toolbar. Apply filters with Super Filters on the canvas and adjust formatting and customization at the same time, without leaving the report. The same options are available in reading view.
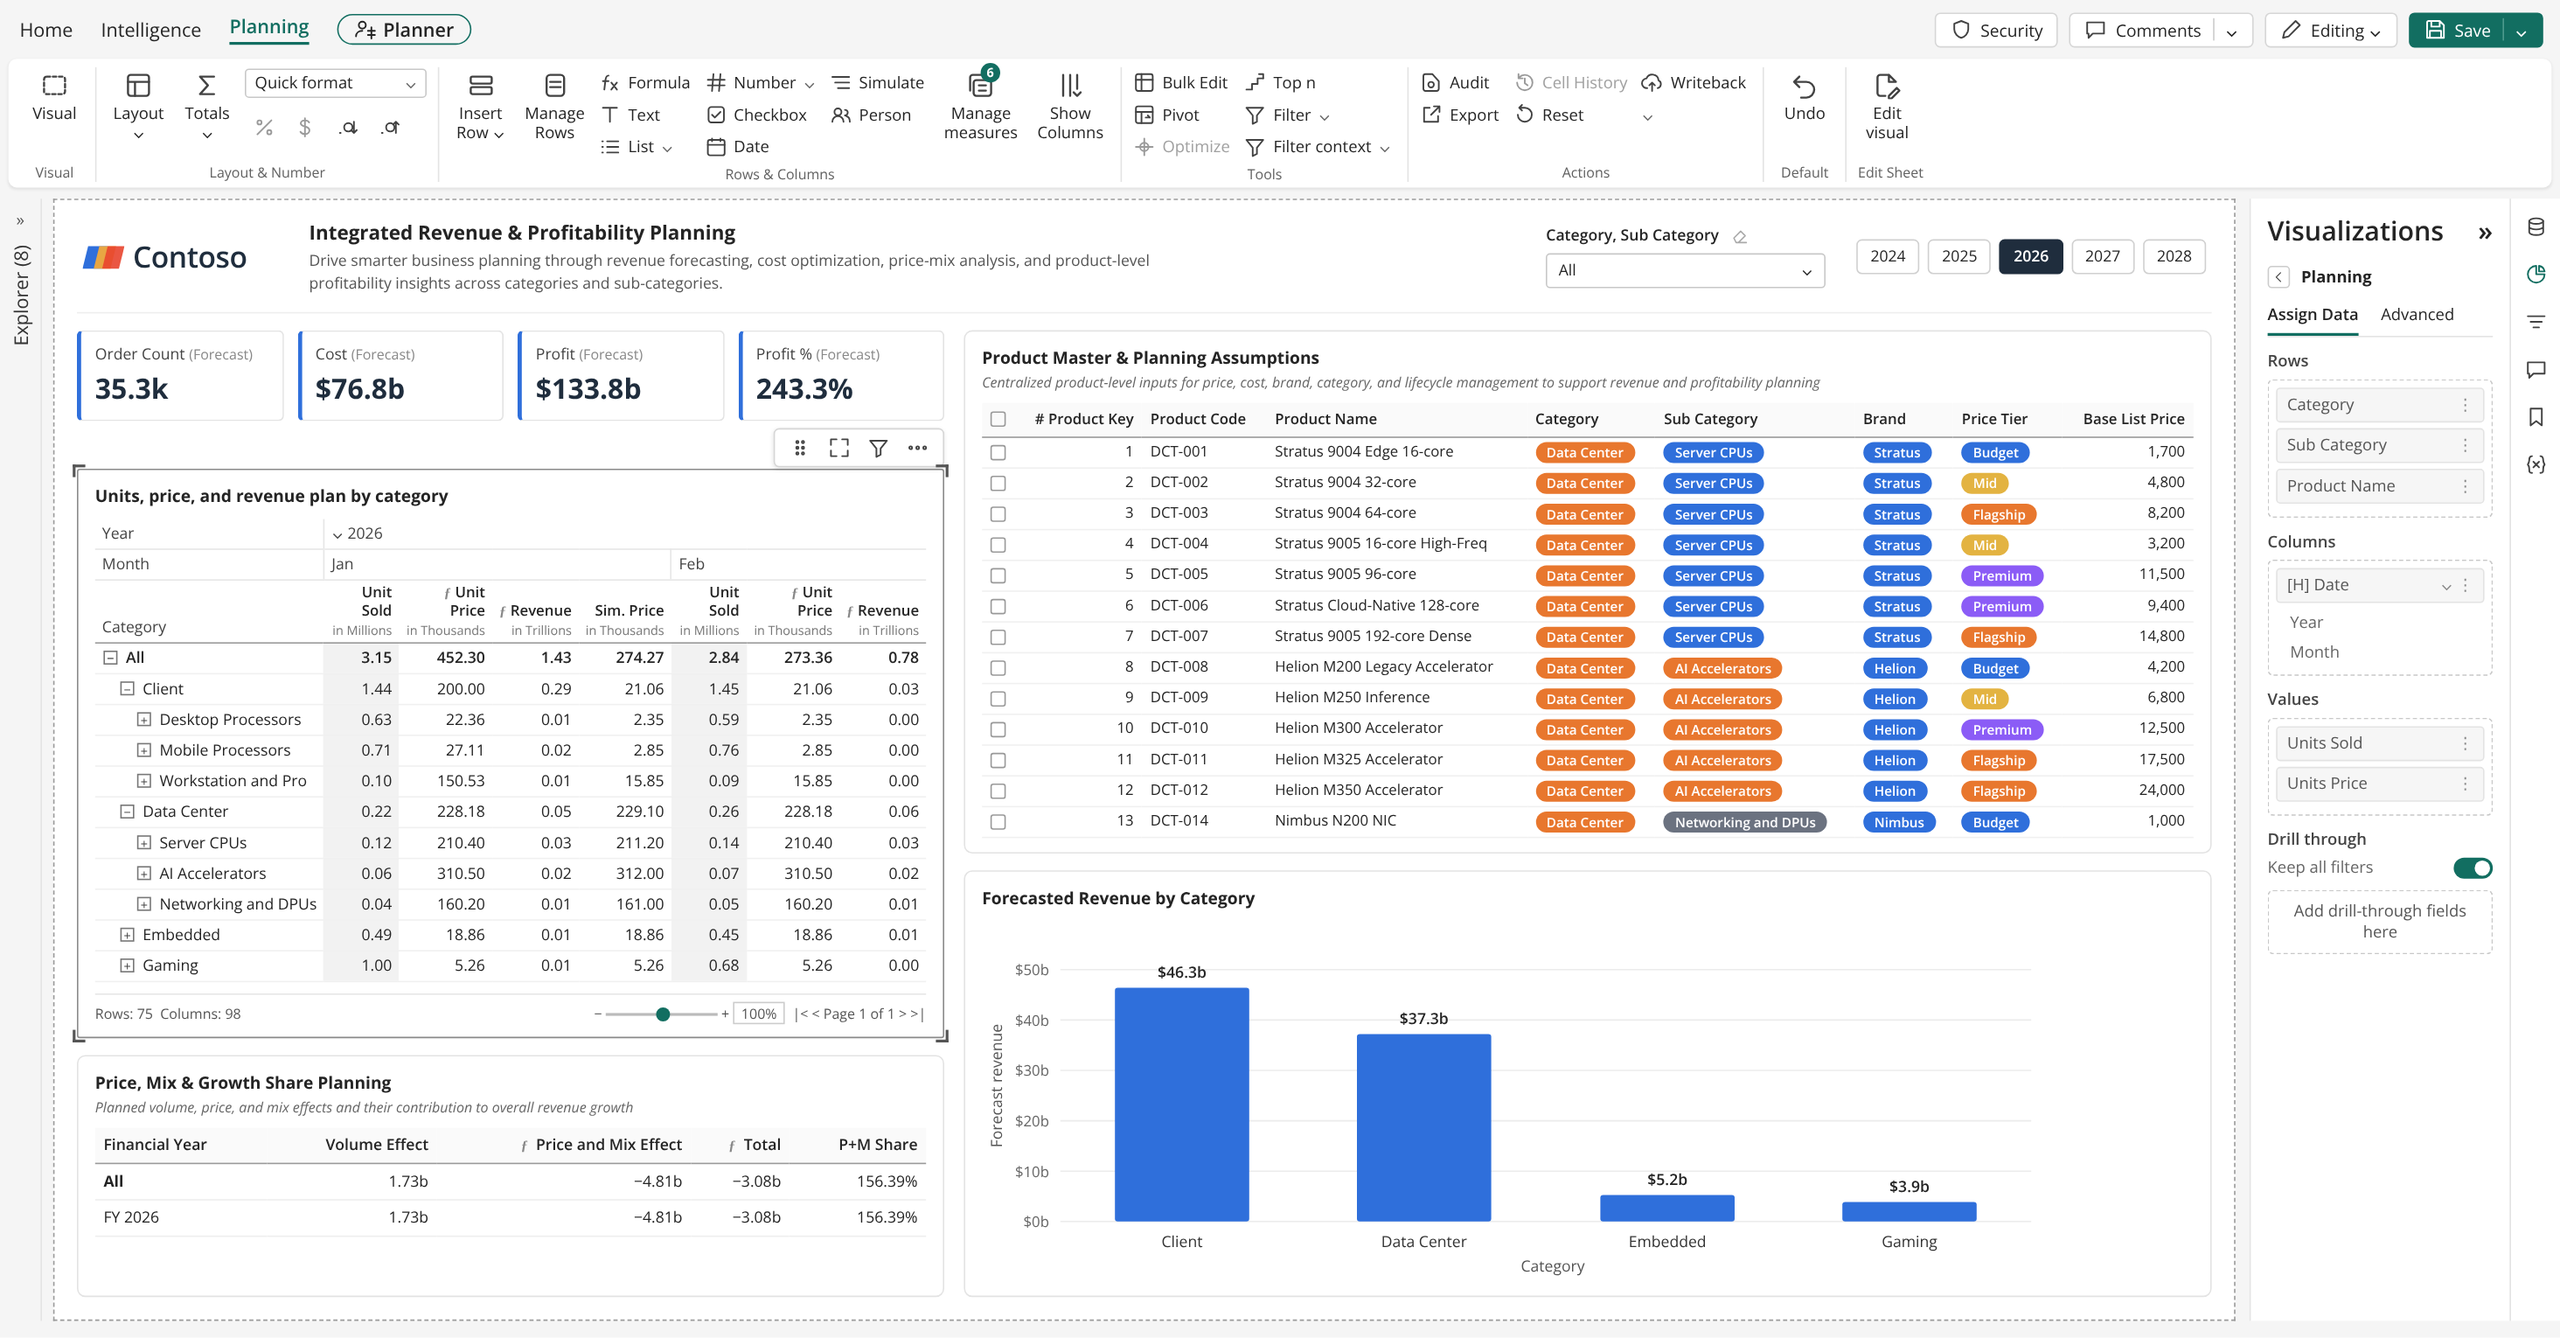
Quick Measure in PowerTable sheets now includes time intelligence. Add prior-period values, period-over-period change, and YTD, QTD, or MTD totals without writing date logic. PowerTable quick measures are also supported in Intelligence Sheets and can be used in any visual via From Sheets in the Data pane.
The new Organization Tree visual displays employee or cost center hierarchies from your semantic model as an interactive org chart.
To add it, select Tree in the Visualizations pane, then choose Organization Tree under Tree Types.
Organization Tree brings the hierarchy and organizational performance use cases of the xViz Performance Flow visual natively into Intelligence Sheets.
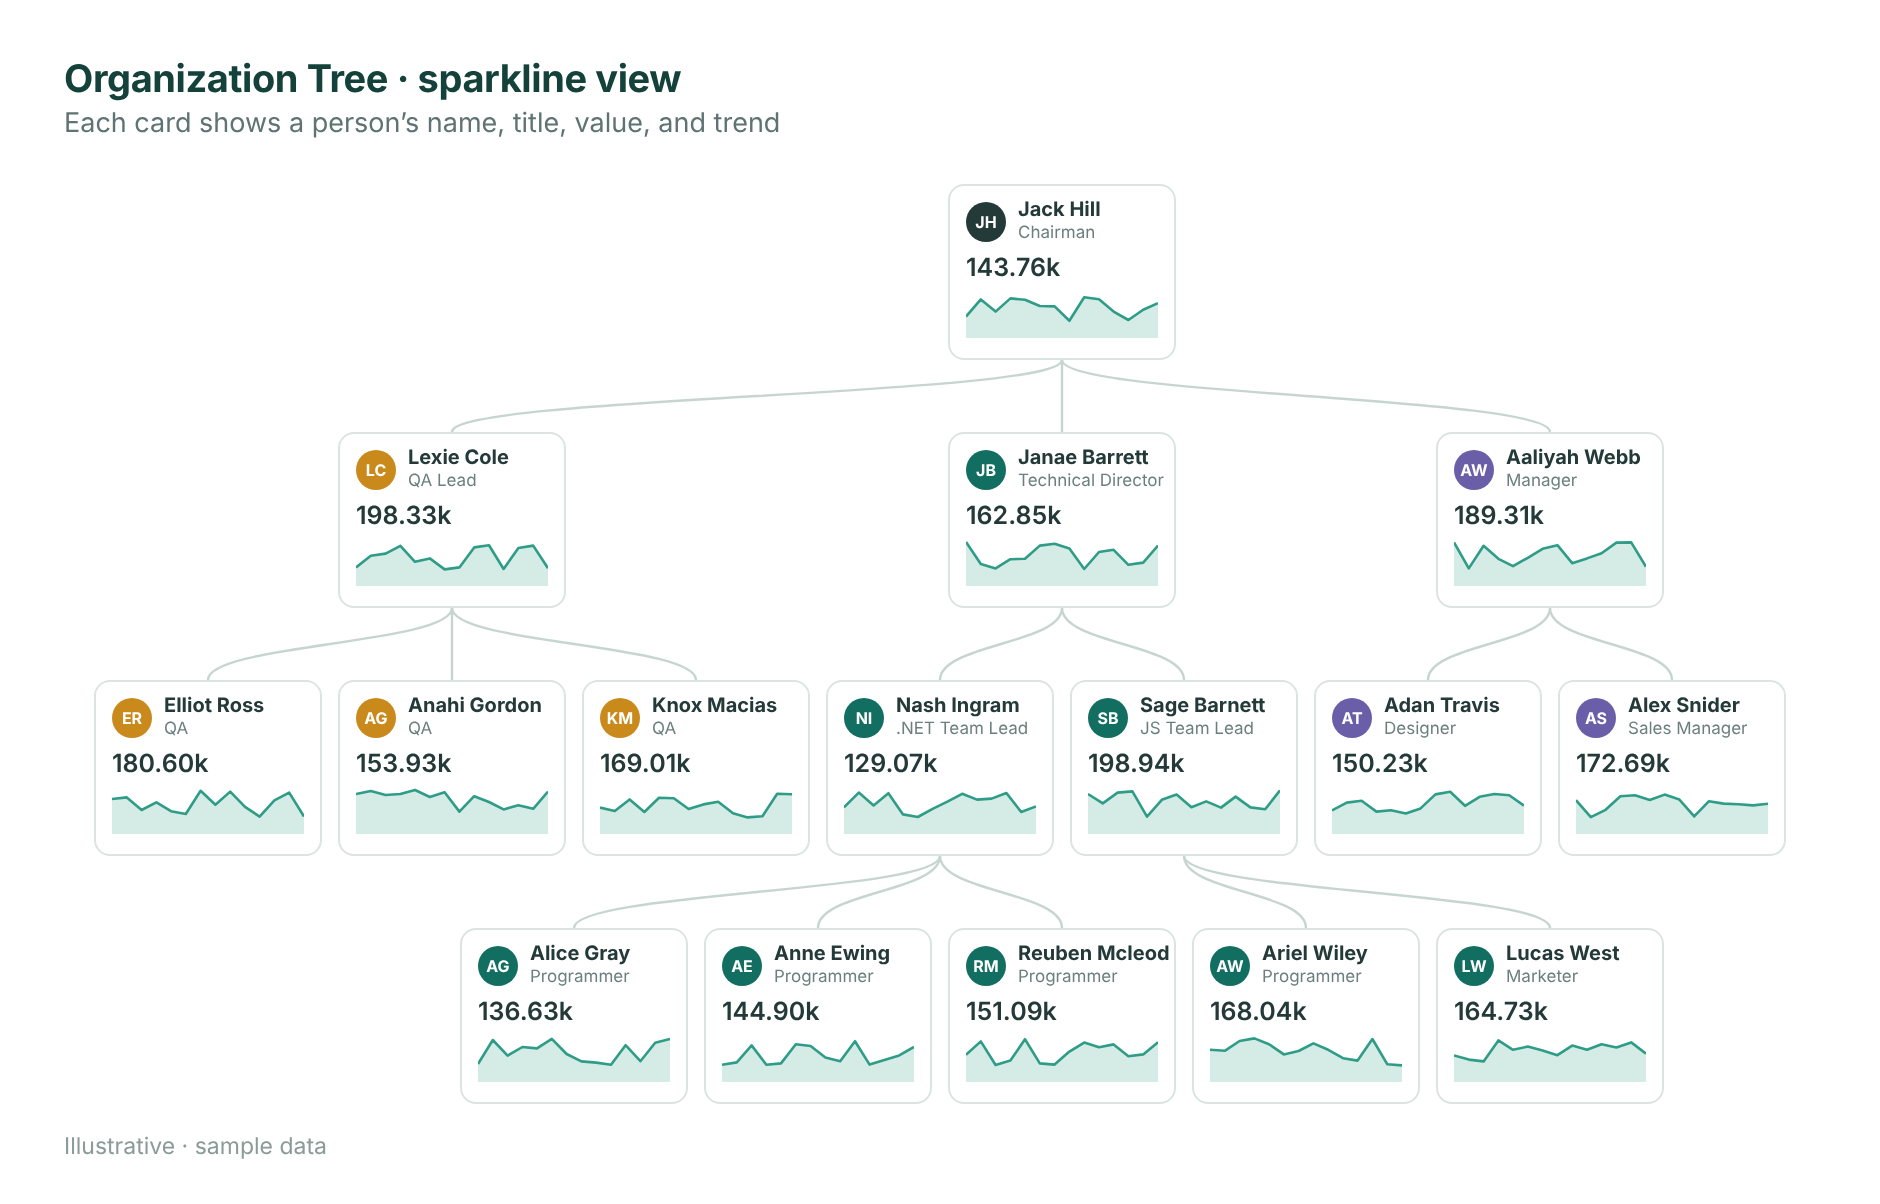
Organization Tree also supports a left-to-right layout for performance hierarchies, with the value, variance, and trend on every node.
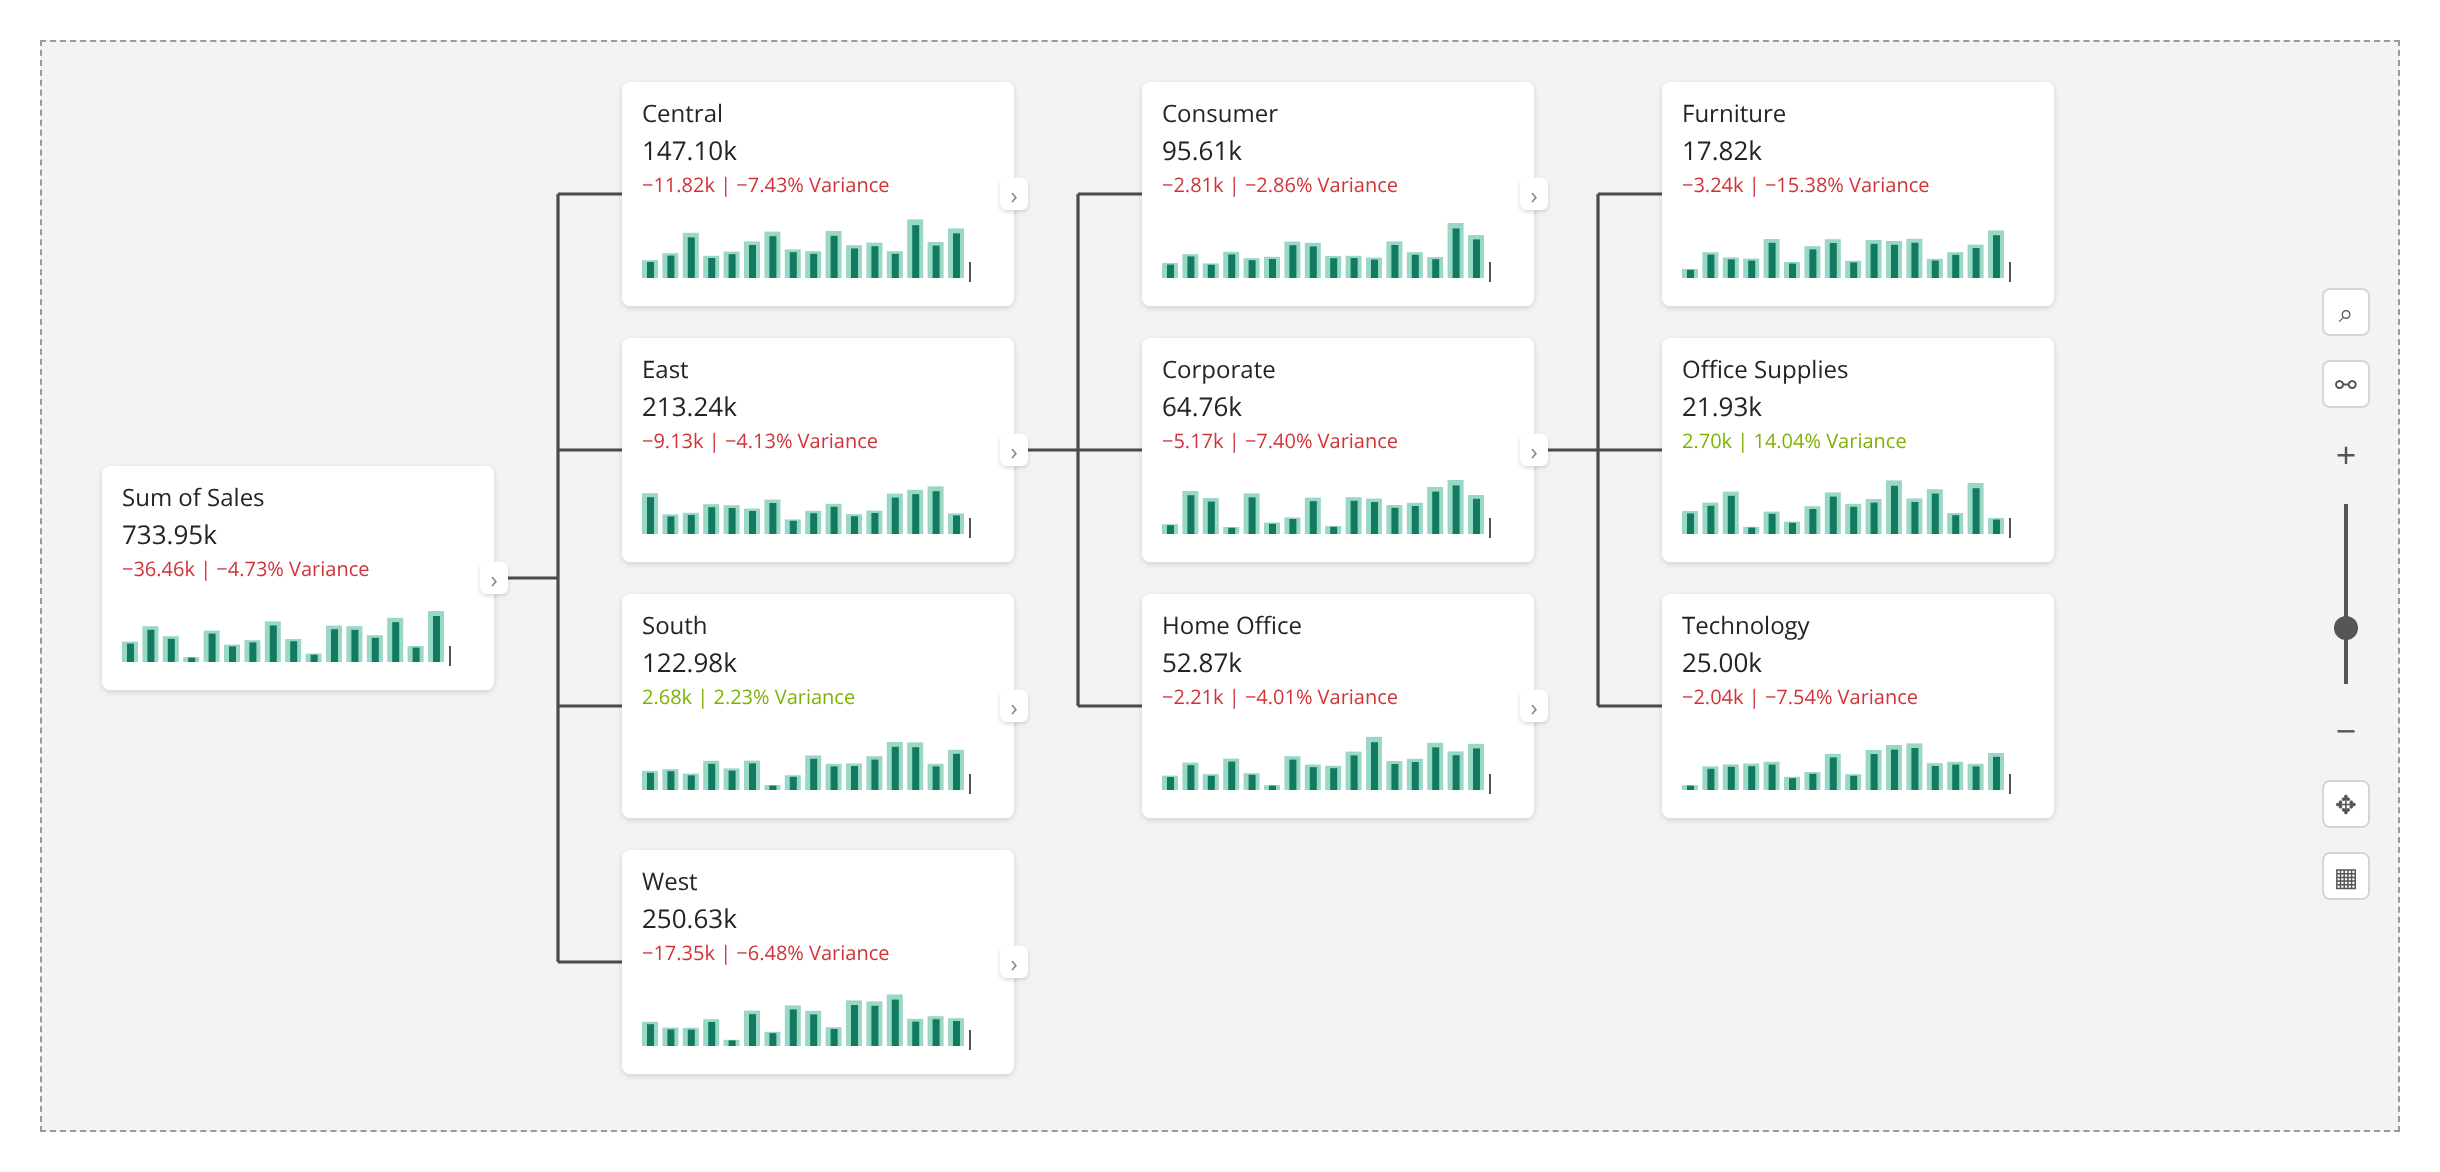
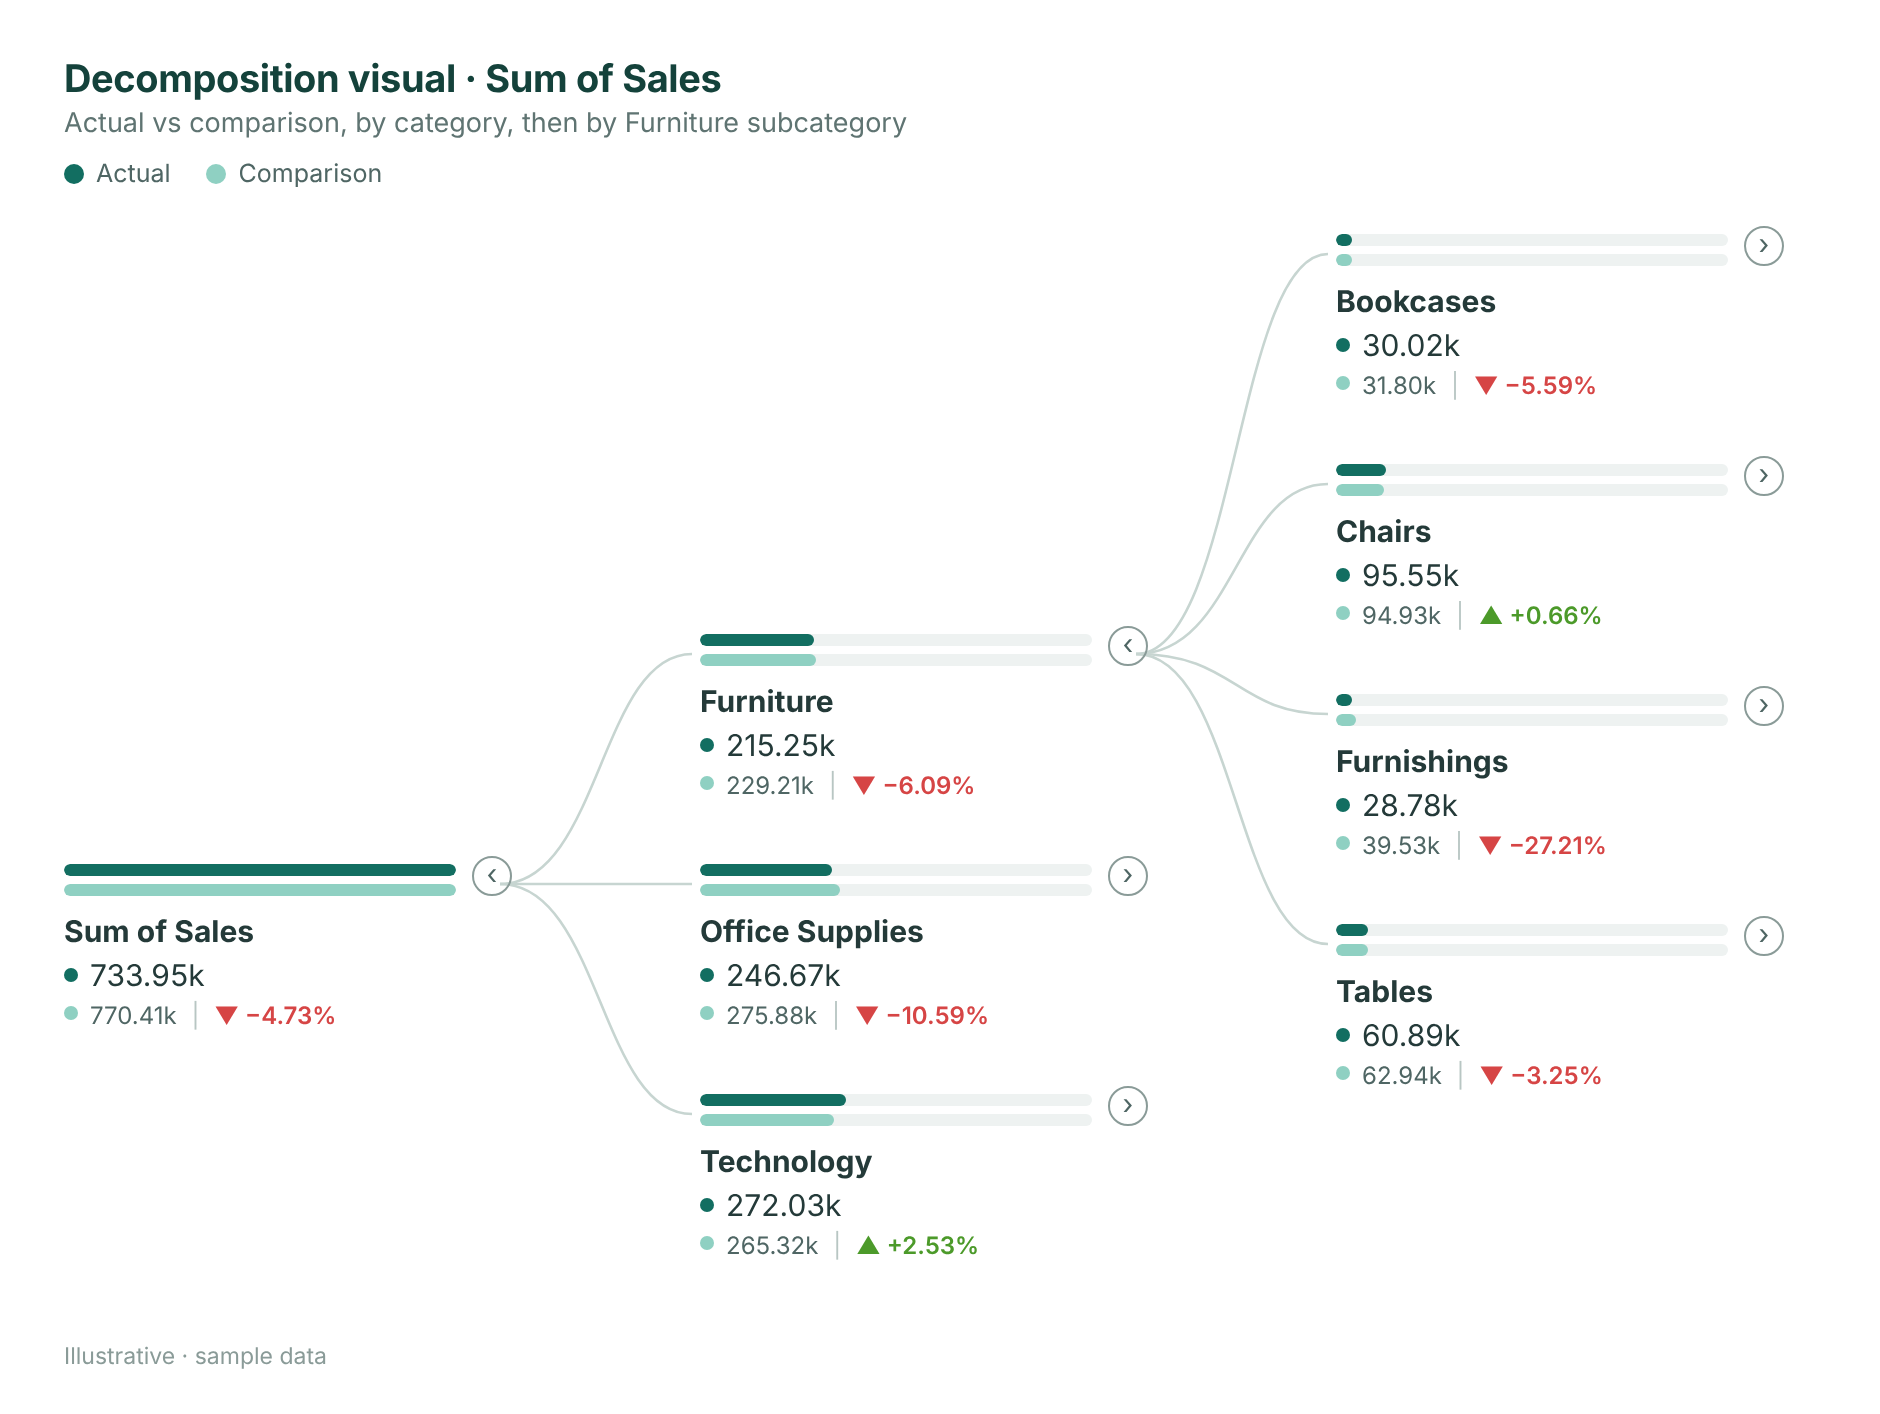
The new Decomposition visual breaks a measure down level by level, across dimensions and hierarchy levels, in the order you choose. Each level shows which branch contributes most.
To add it, select Tree in the Visualizations pane, then choose Decomposition Tree under Tree Types.
New options for matrices, tables, and charts:
Matrix and Table visuals have a new aggregation type, Visible Rounding. It calculates totals from the rounded values displayed, using the visual’s display precision and rounding rules, so totals match the visible values. Source data is unchanged, and other aggregation types work as before.
| Current assets | Value ($M) | Displayed, no decimals |
|---|---|---|
| Cash and cash equivalents | 14.4 | 14 |
| Accounts receivable | 2.3 | 2 |
| Inventory | 15.2 | 15 |
| Other receivables | 1.6 | 2 |
| Total, standard aggregation | 33.5 | 34 |
| Total, Visible Rounding | 33.5 | 33 |
Example: current assets on a balance sheet, shown without decimals. Standard aggregation rounds the actual total, 33.5, up to 34, but the lines a reader sees add up to 33. Visible Rounding adds the displayed values (14 + 2 + 15 + 2 = 33), so the balance sheet ties on screen.
Apply conditional formatting by rule, measure type, or custom measure, for example to flag missed targets, distinguish actuals from forecast, or mark thresholds. It’s ideal for multi-scenario forecasting and budget planning, where each scenario can be formatted differently so scenarios are easy to compare.
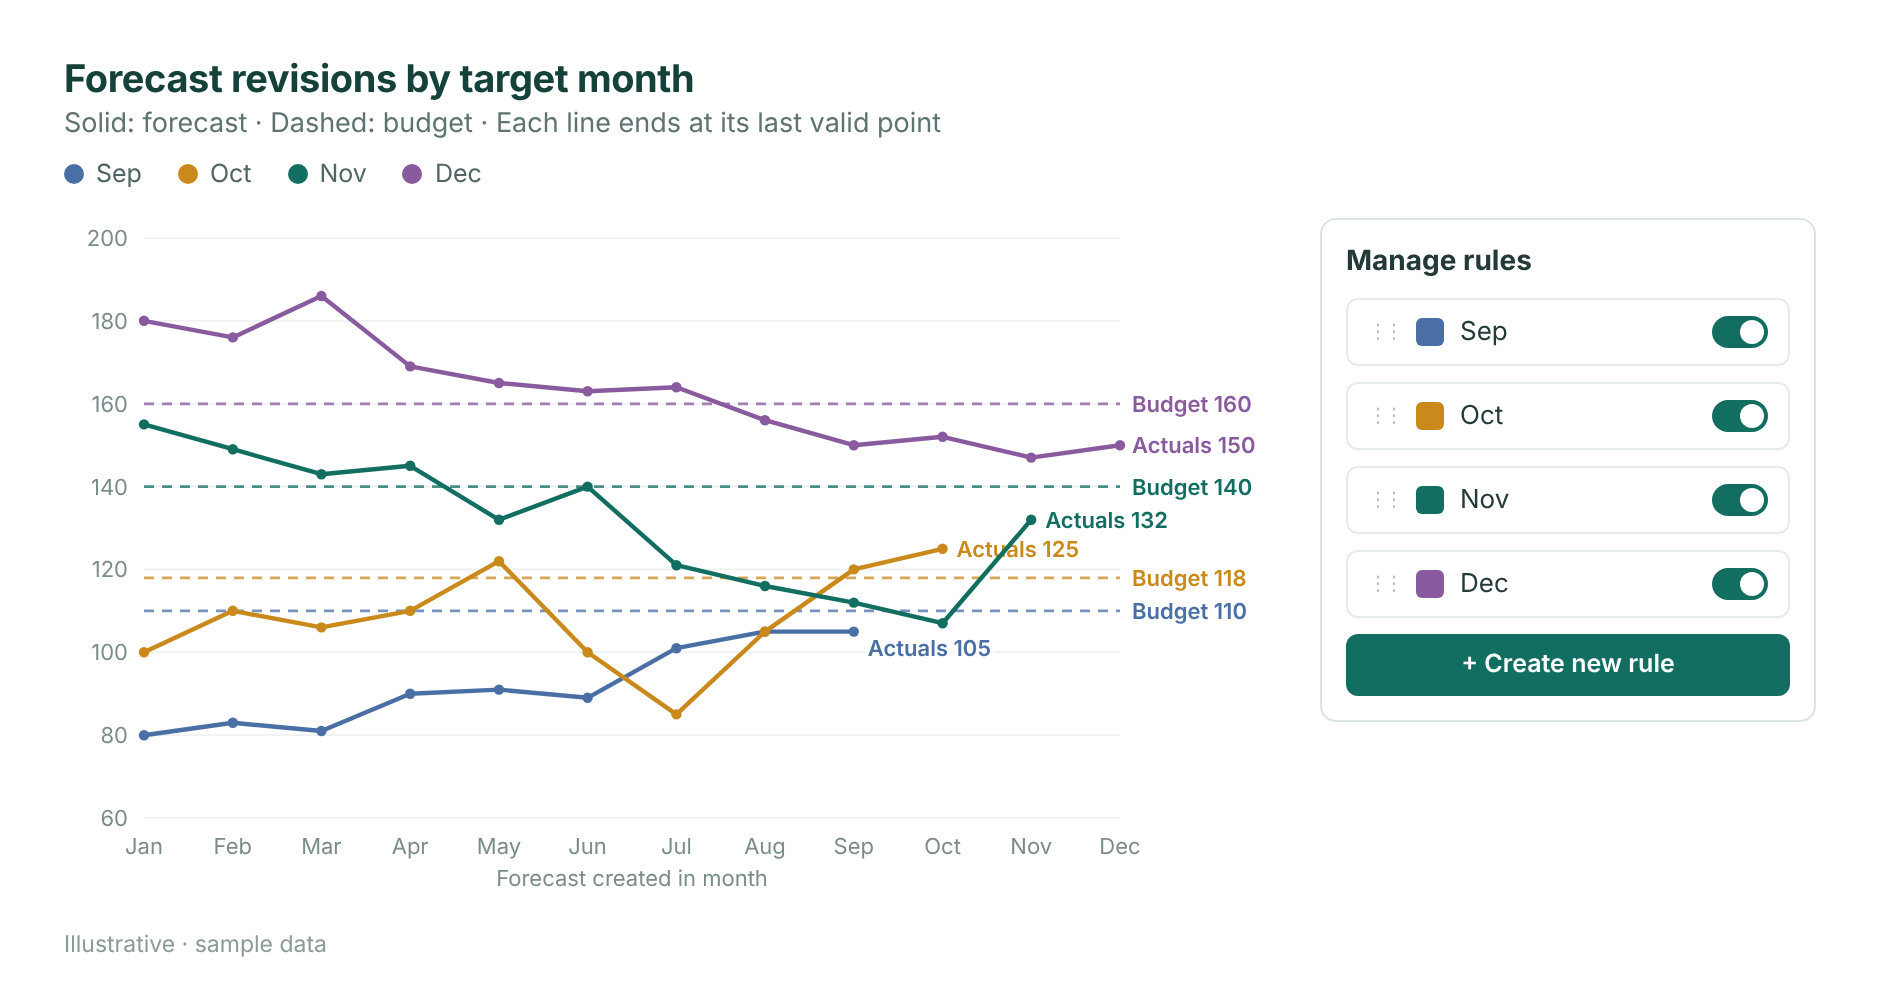
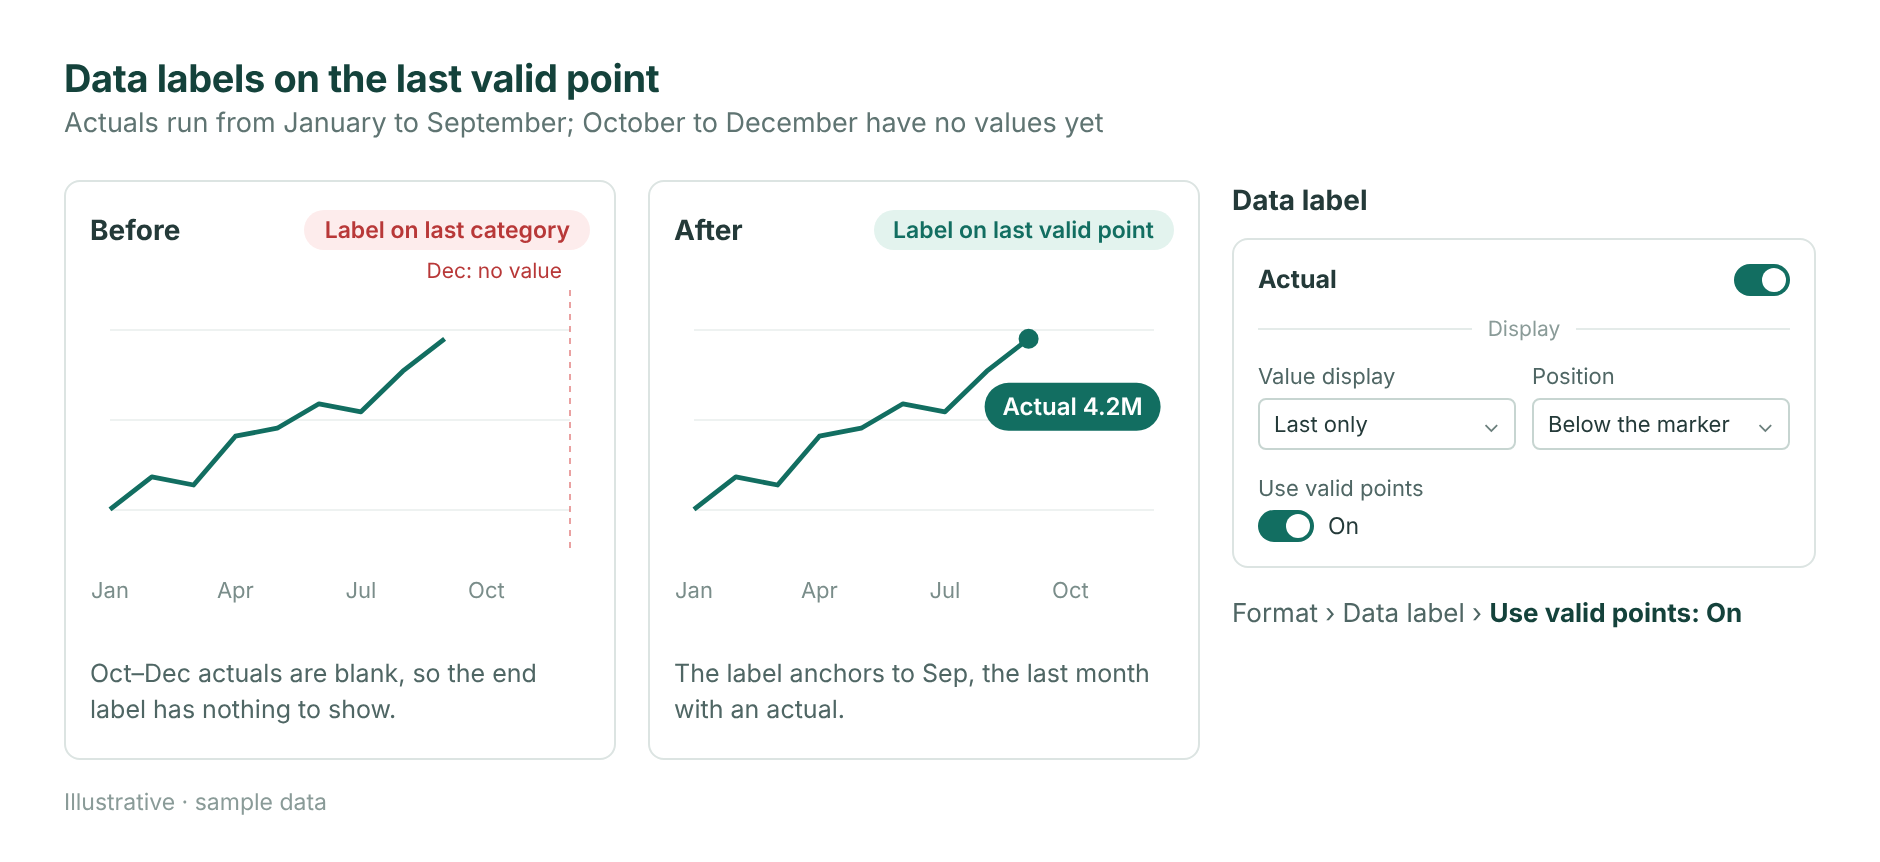
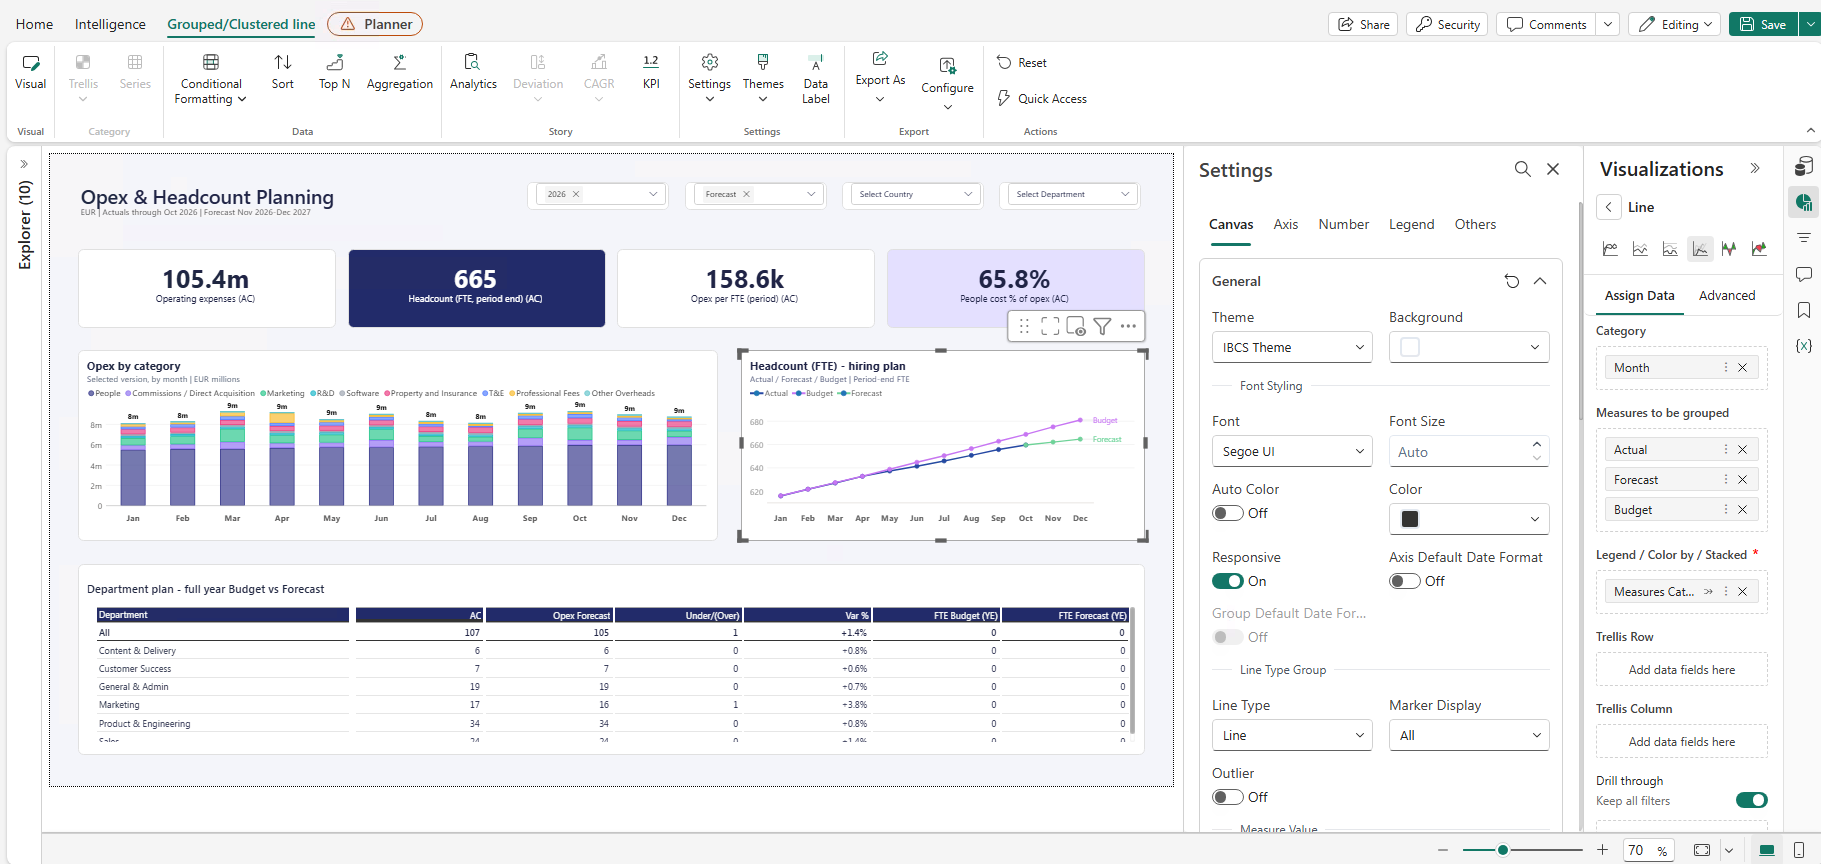
Line charts can plot only valid periods, so forecast and partial-year series don’t drop to zero. With Use valid points turned on in Format › Data label, the end label anchors to the last period with data instead of the last category.
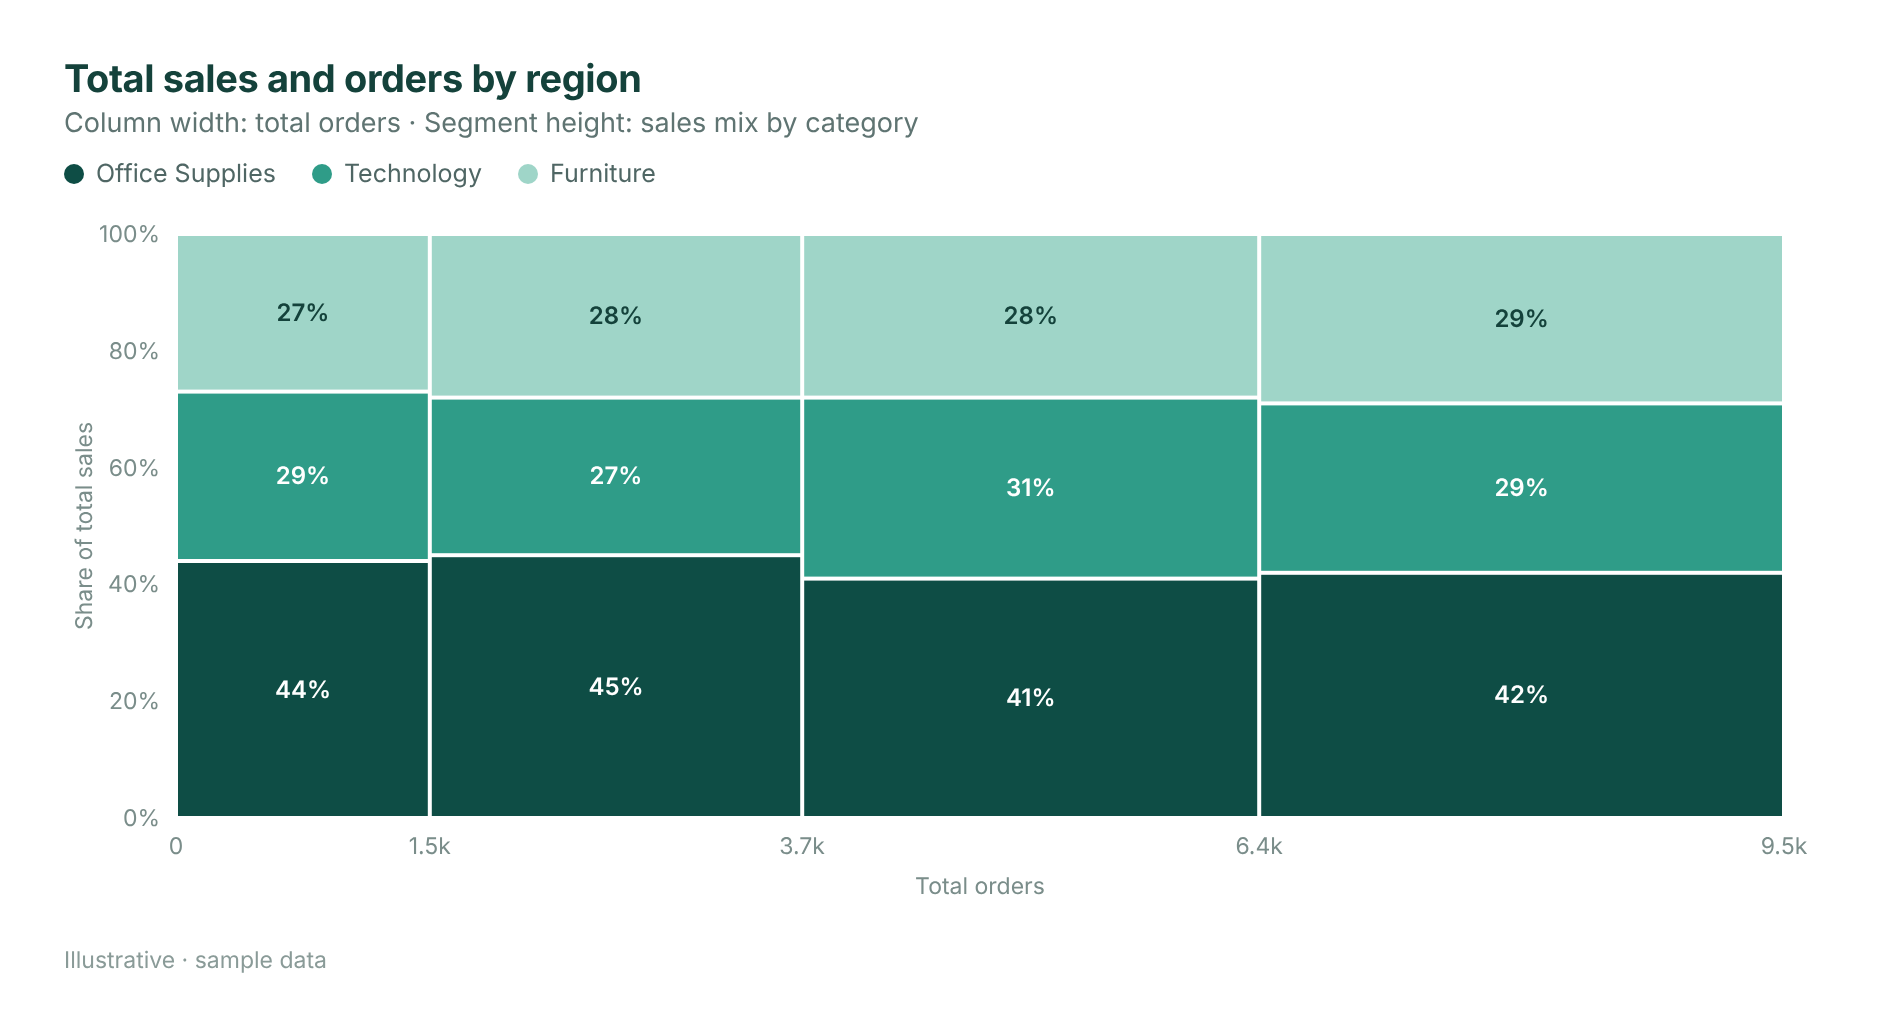
Marimekko charts can now show column width as a percentage of the total, together with category labels on the x-axis.
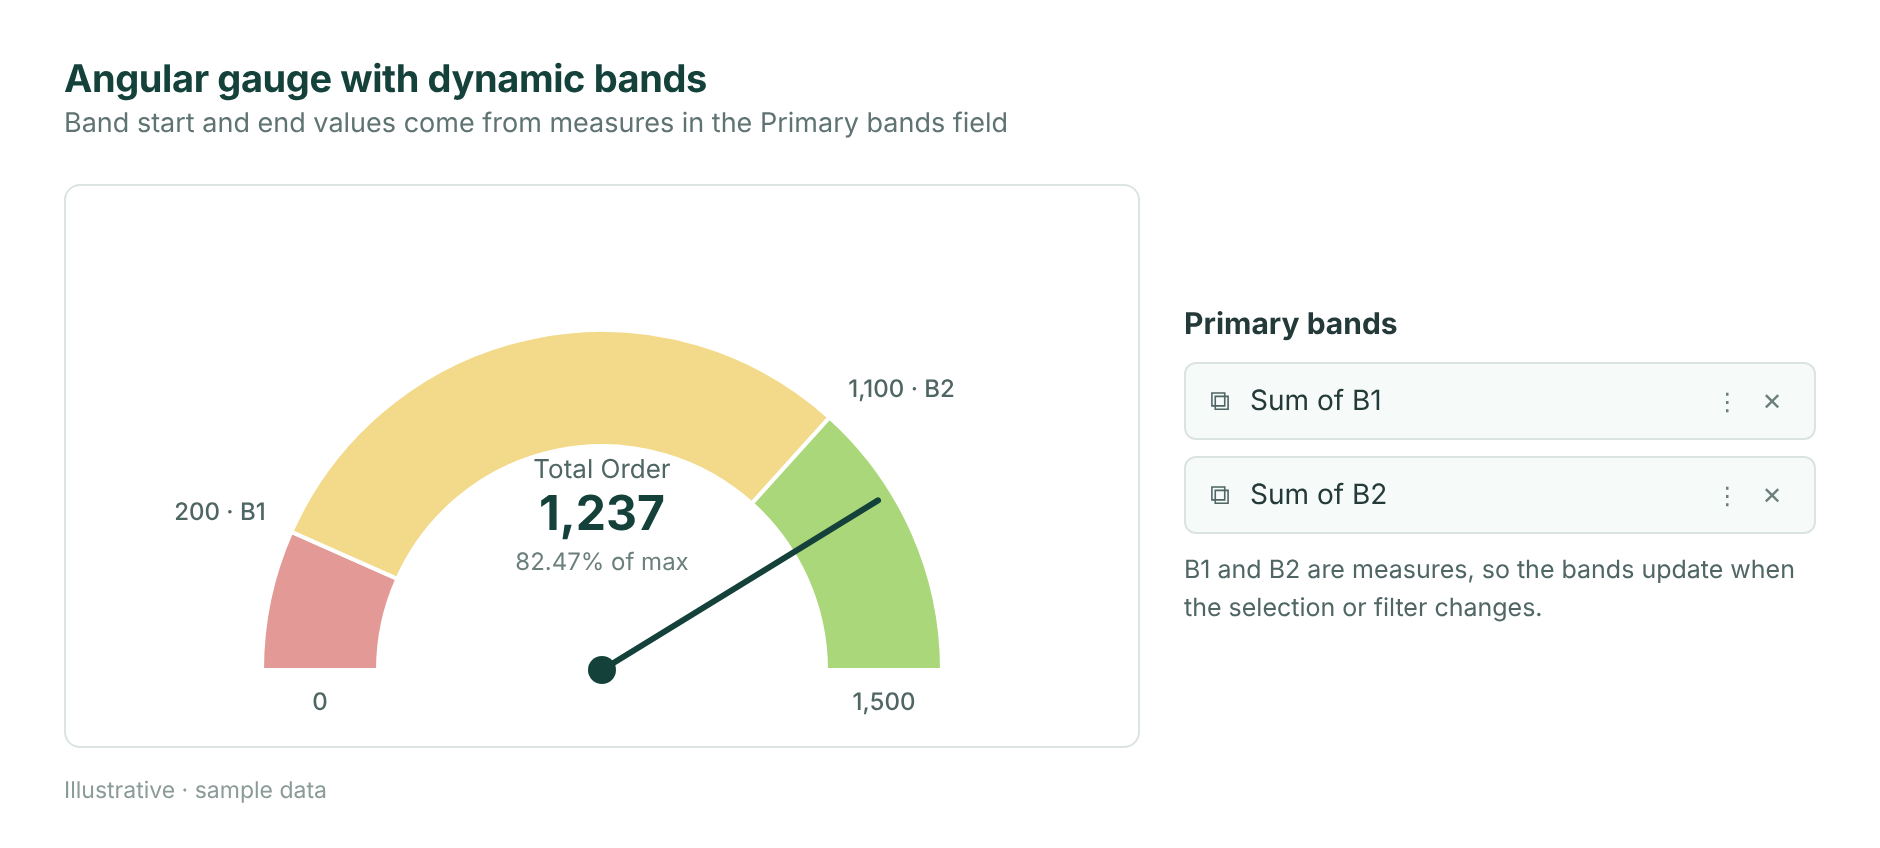
On angular and linear gauges, band start and end values follow the current selection or filter.
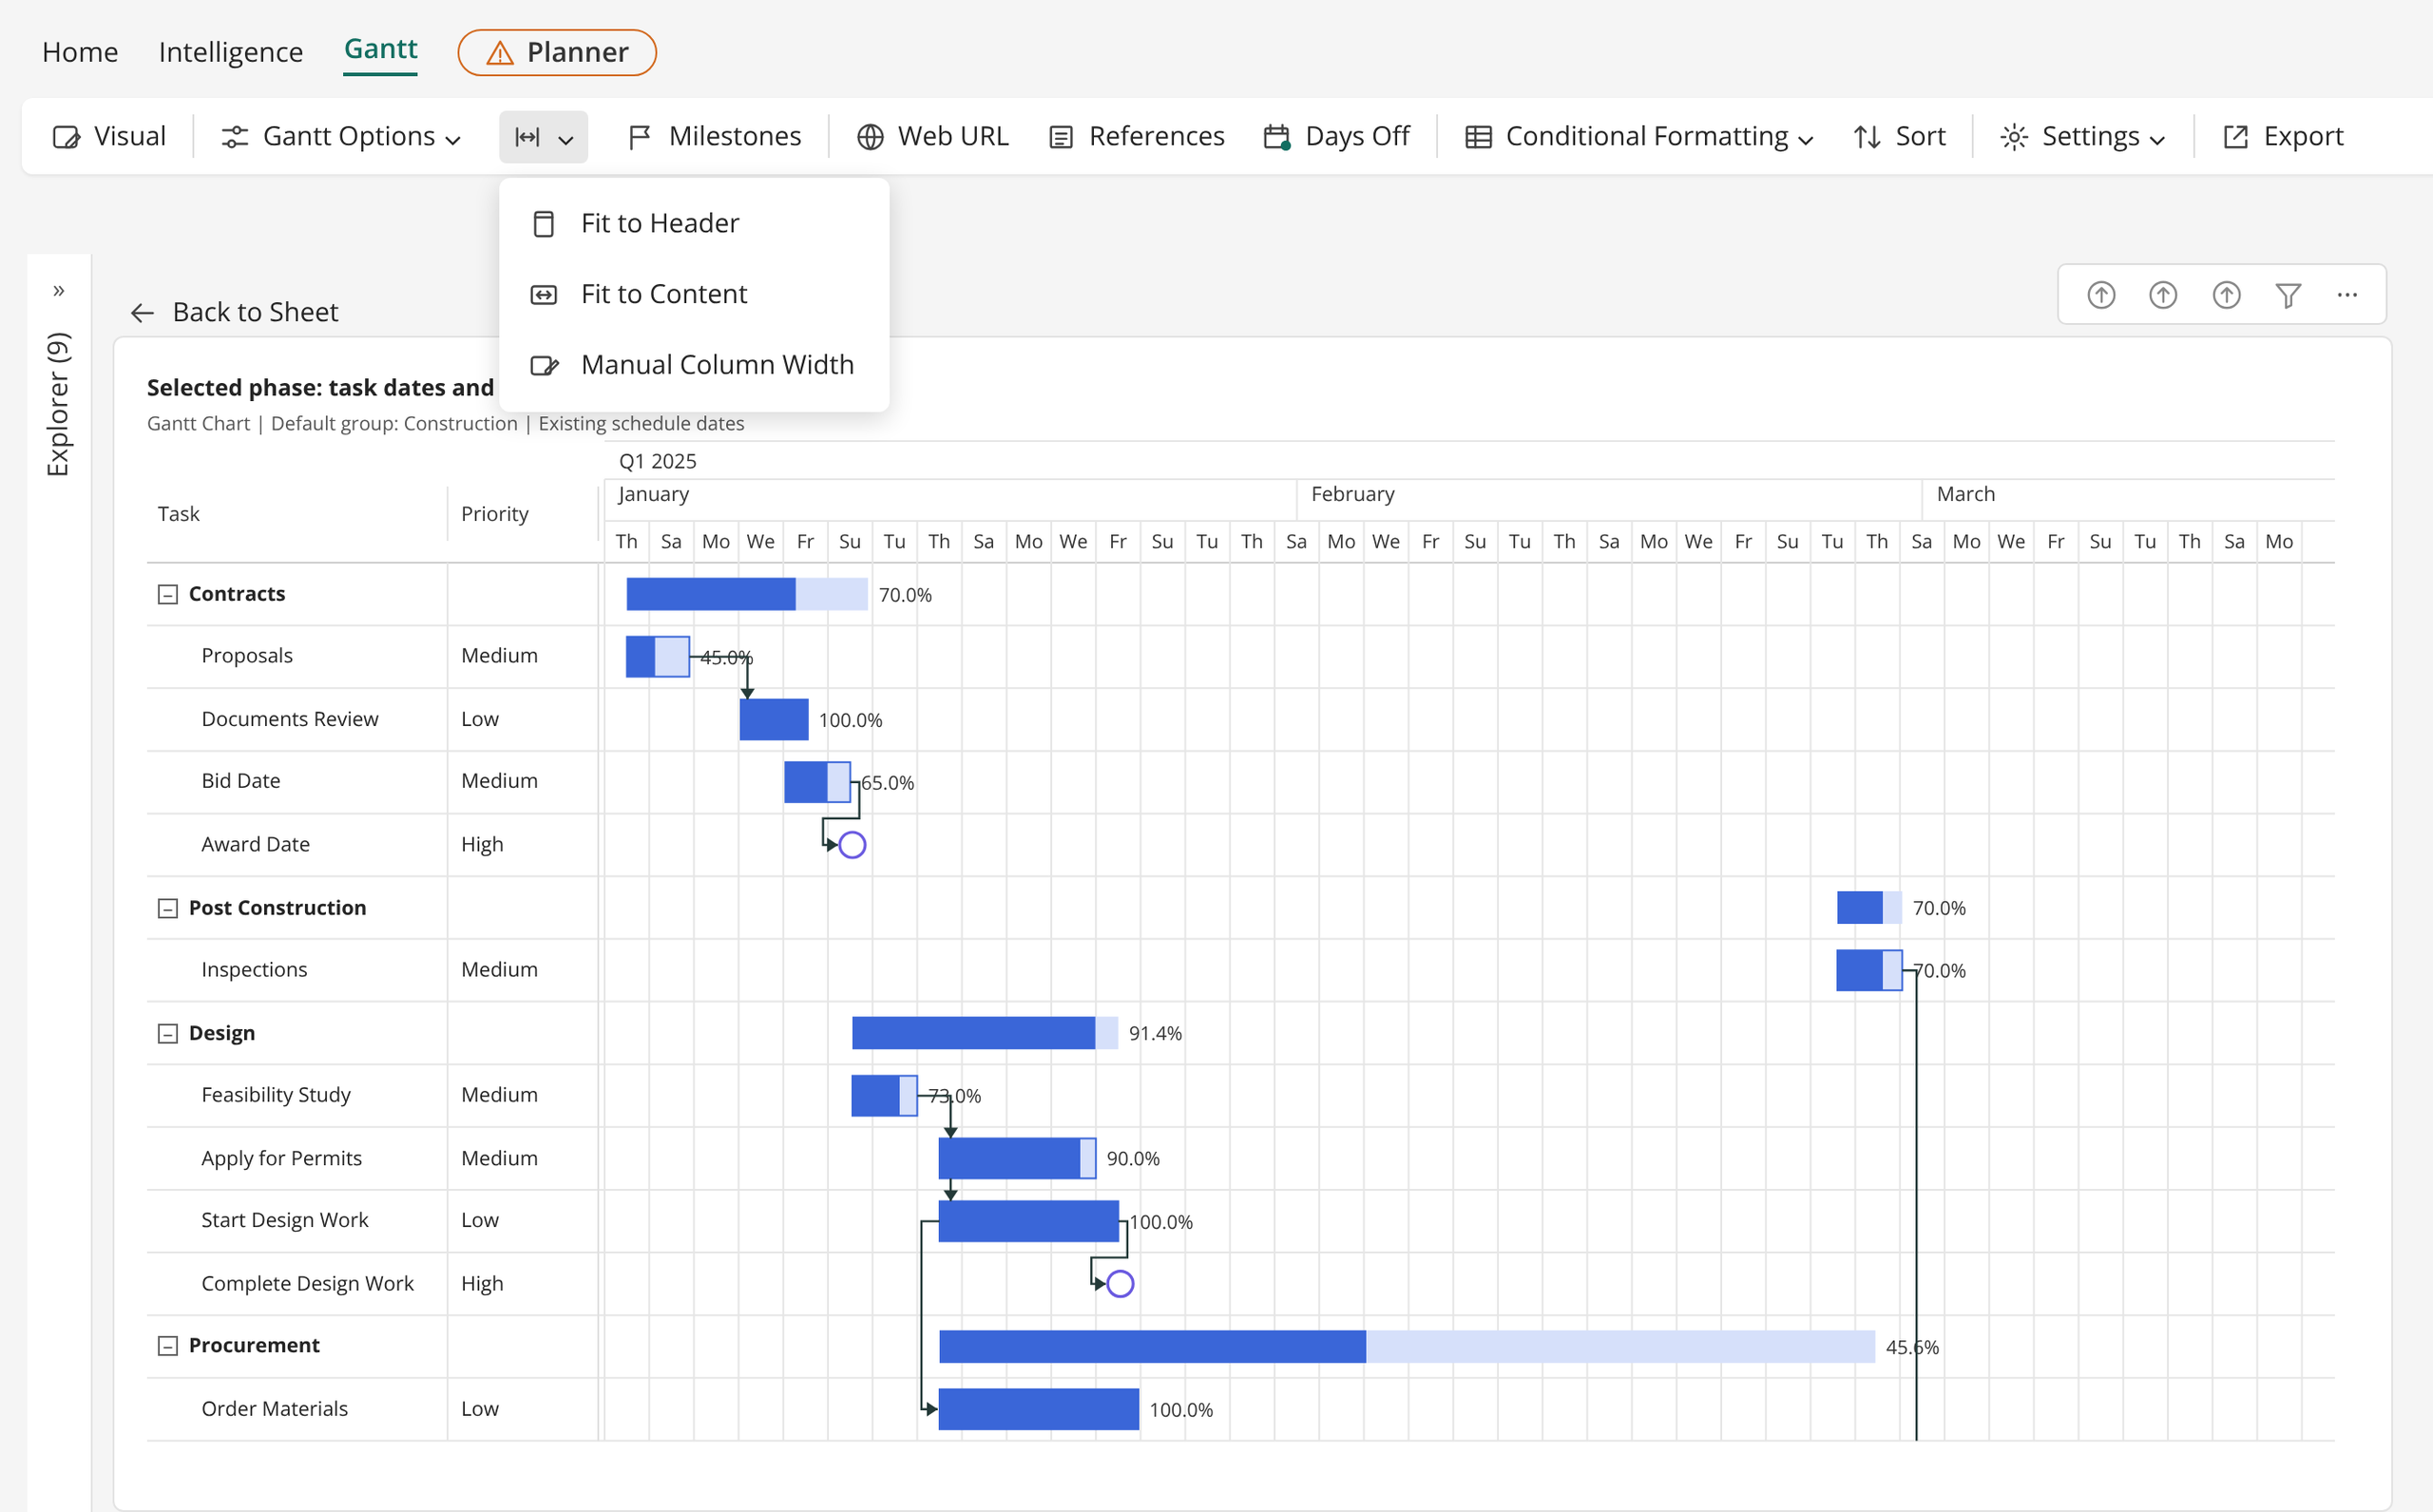
The Gantt visual supports the complete functionality of the xViz Gantt chart. New in this update:
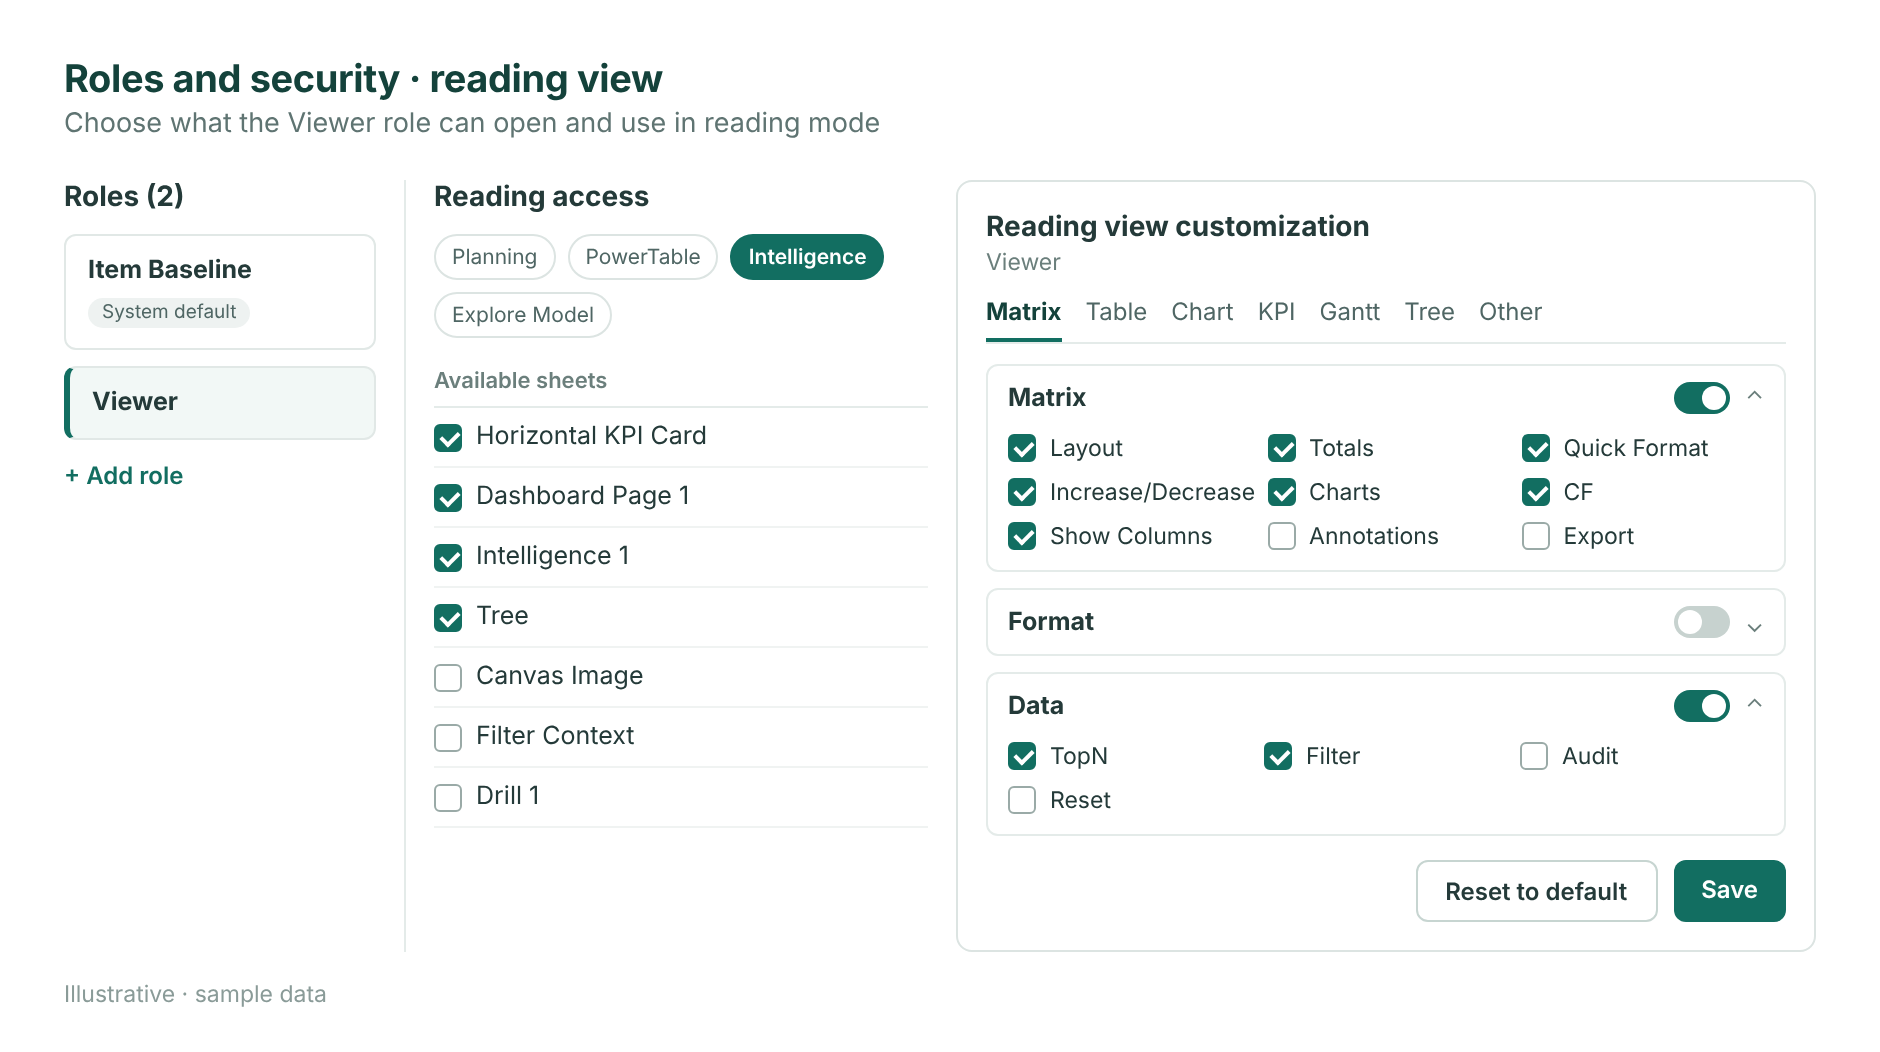
Administrators can now configure reading view settings for each role in Security › Roles › Reading View Customization.
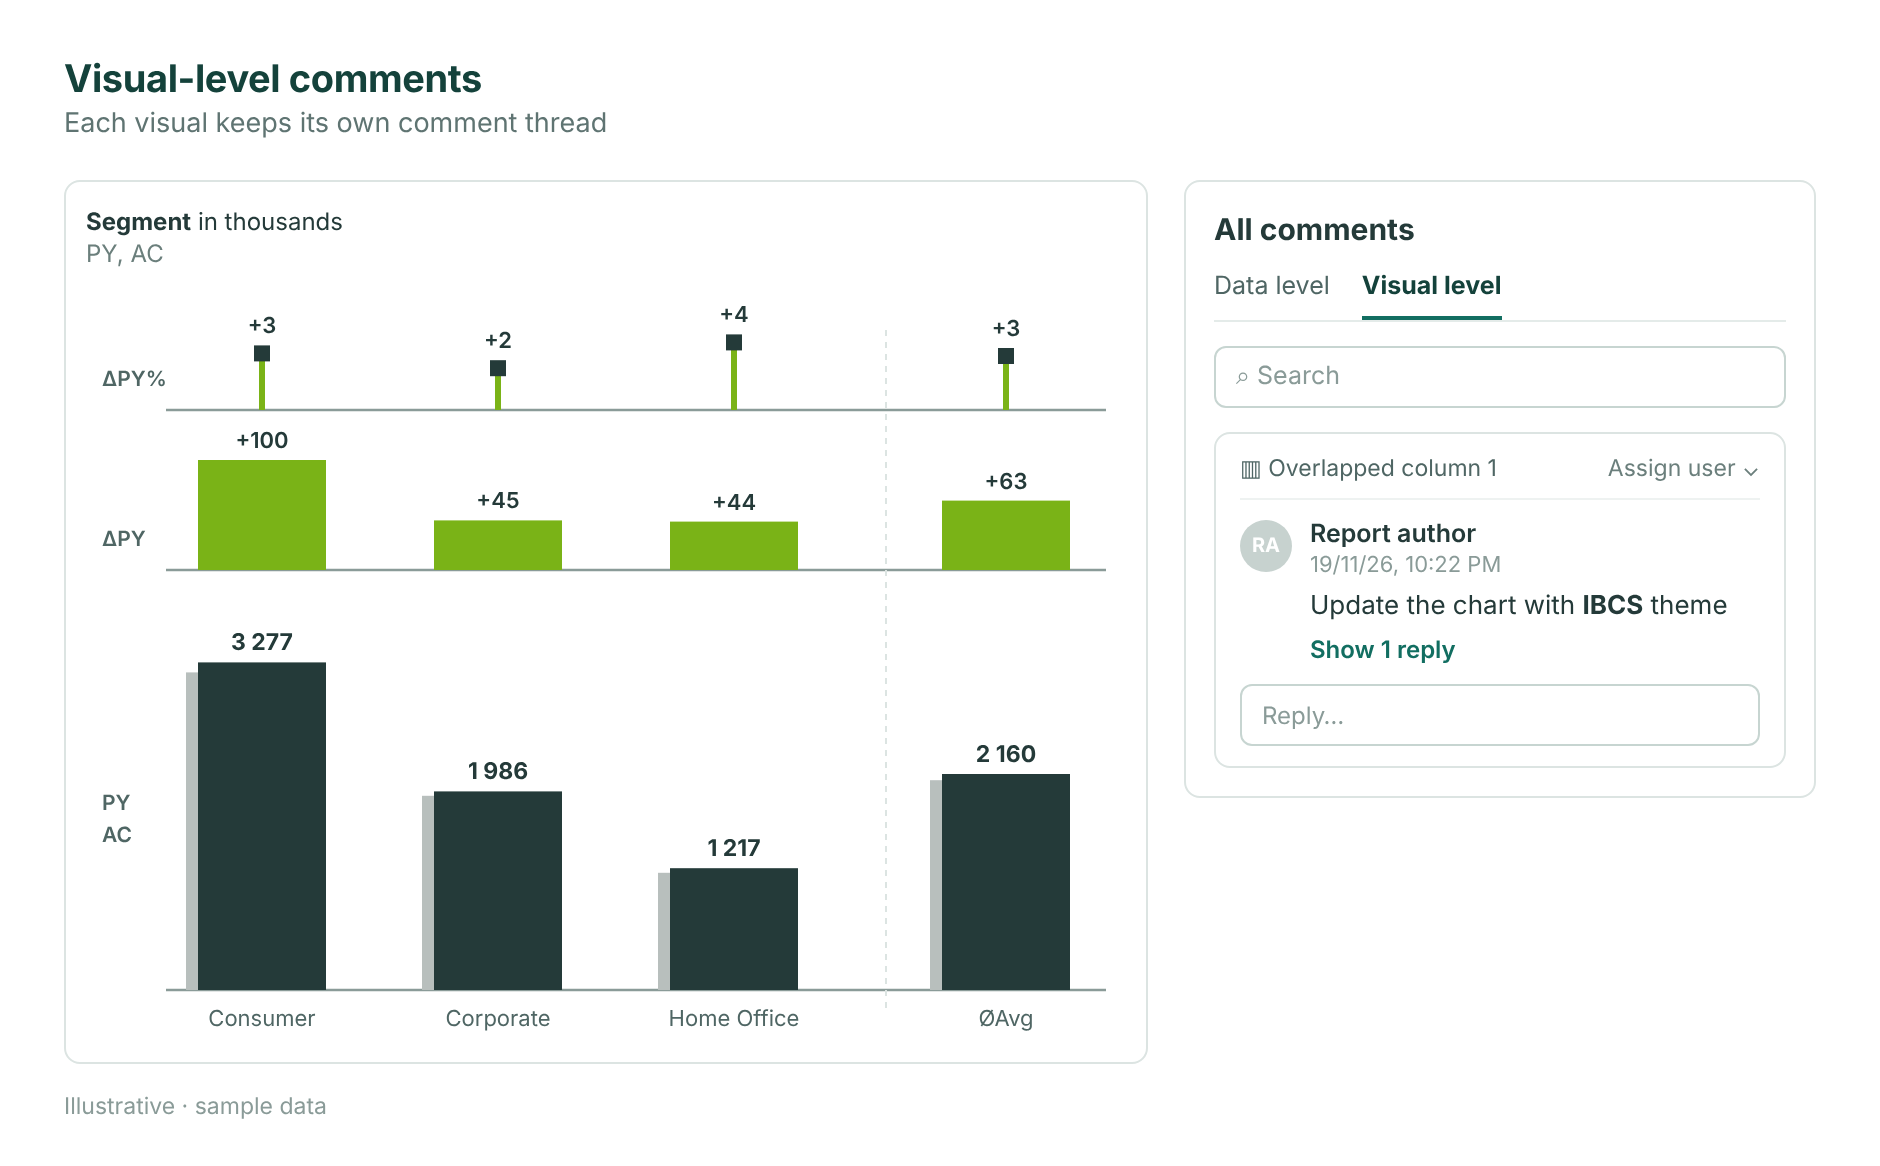
Fabric Plan is IBCS® certified, aligned with ISO 24896:2026. IBCS® notation, automatic AC, PL, PY, and FC scenarios, and themes are available across 100+ charts and templates.
Intelligence Sheets has seen major improvements in performance, UI, and capability. Business users can build financial, management, variance, and paginated reports, executive scorecards, and ad hoc analysis without code.
Reports can draw on semantic models, on Planning sheets with budgets, forecasts, and scenarios, on PowerTable sheets and queries, and on data from platforms such as Snowflake, Databricks, and SAP through shortcuts and mirroring. Combine the sources that best fit each analysis, blend measures across them, and plan, analyze, and update in one place.
New visuals, role-based reading views, and planning inside your reports, all in the place your teams already work.
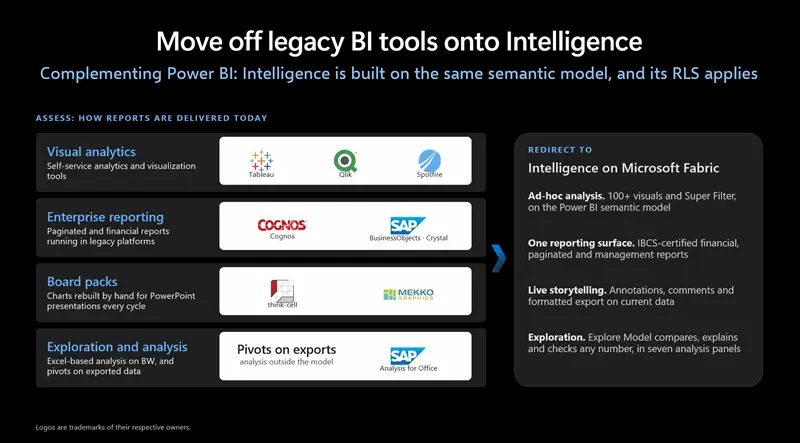
Planning to retire legacy BI tools such as Tableau, Qlik, or Cognos? Try Intelligence Sheets in Fabric Plan, a full BI suite on the Power BI semantic model.
Feature details reflect Fabric Plan at the time of writing.
Fabric Planning was announced at FabCon Atlanta in March 2026 to bring planning, analytics and decision-making together in one place. Finance and business teams often plan in one tool, report in another, and explain the numbers in slide decks and email threads. Each switch takes time, and the context behind the numbers gets lost.
The Intelligence Sheet brings management reporting into the same Plan item where planning happens. Teams connect to their semantic model, build planning models, create budgets and forecasts, and deliver reports in one place.
This release adds IBCS® certification, embedded planning, Intelligence Sheets in organizational apps alongside Power BI, and data-linked annotations, along with enhancements that make reports faster to build and easier to read.
Microsoft Fabric Planning is IBCS® CERTIFIED Charts+Tables (International Business Communication Standards). It is also certified to ISO 24896:2026, Notation for business reporting: the certification confirms that business charts and tables in the Intelligence Sheet are designed to the ISO standard. Finance users get a standard visual language they recognize on sight.
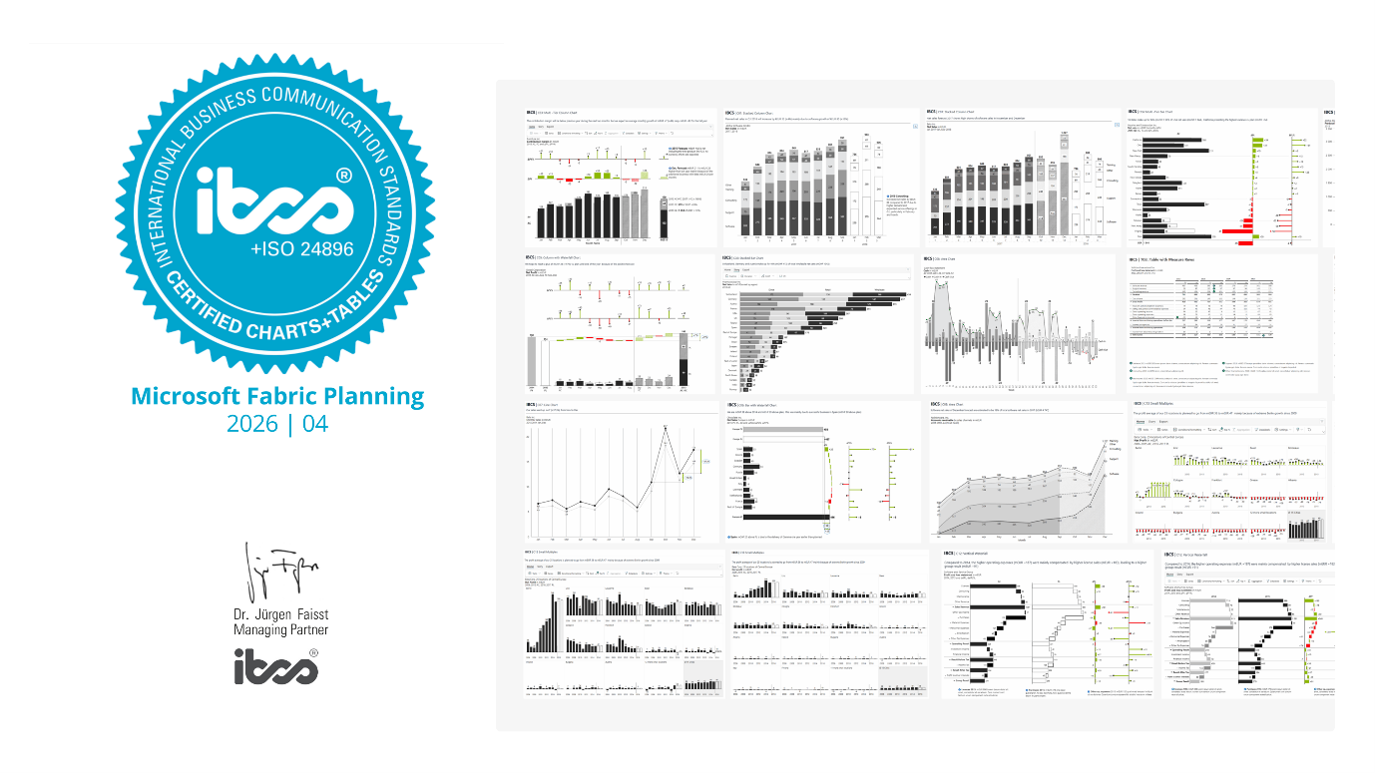
IBCS certified charts and tables in the Intelligence Sheet
Planning grids, PowerTable grids and Forms can now be embedded directly in an Intelligence Sheet, alongside charts, KPIs, and Gantt, Resource, Kanban and Calendar views.
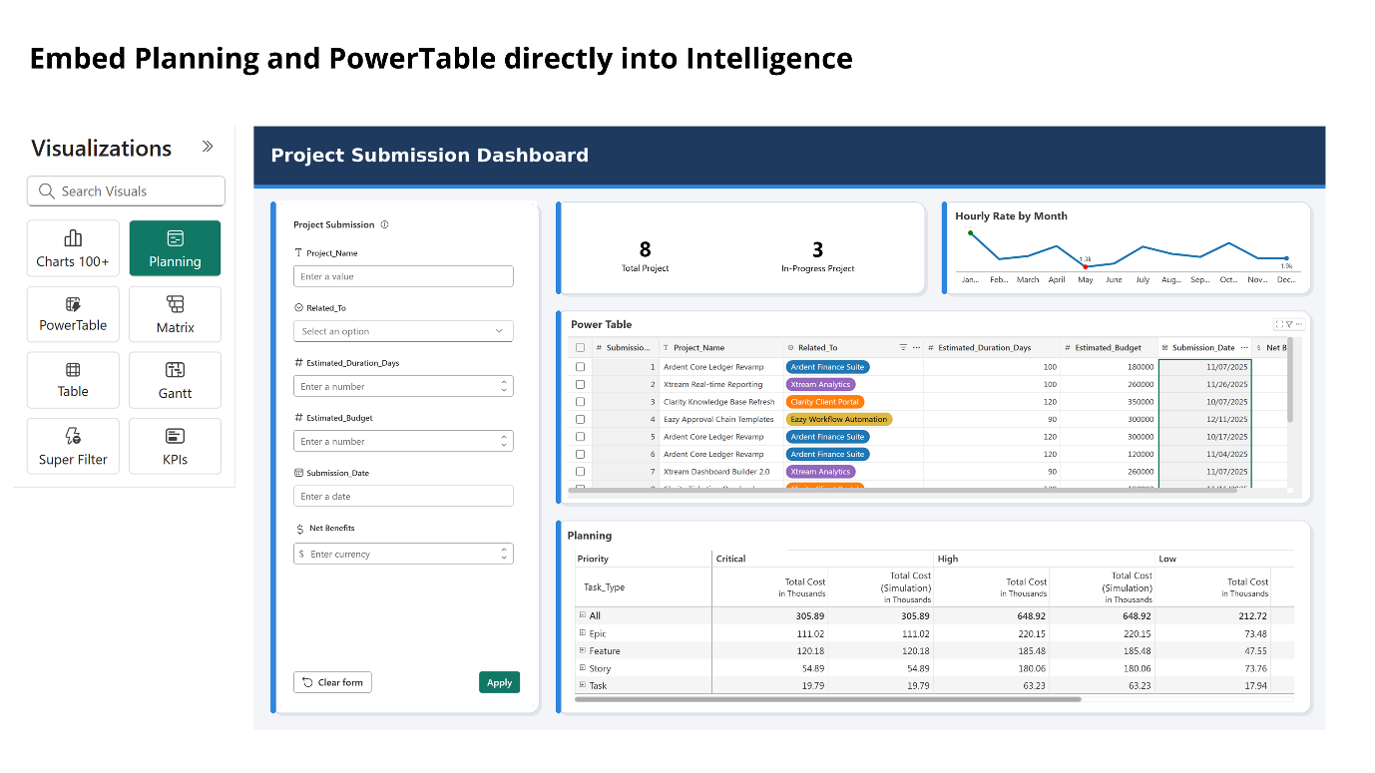
A PowerTable form, PowerTable grid and planning grid embedded beside KPIs and a chart
The report is no longer only the last step in the planning cycle. It is where teams analyze, decide and act.
Intelligence Sheet reports and Planning Sheets can now be added as pages in a Power BI or Fabric organizational app, alongside your existing Power BI reports. Intelligence Sheets and Power BI reports co-exist in the same app, so teams keep using the reports they already have and add planning and IBCS reporting next to them.
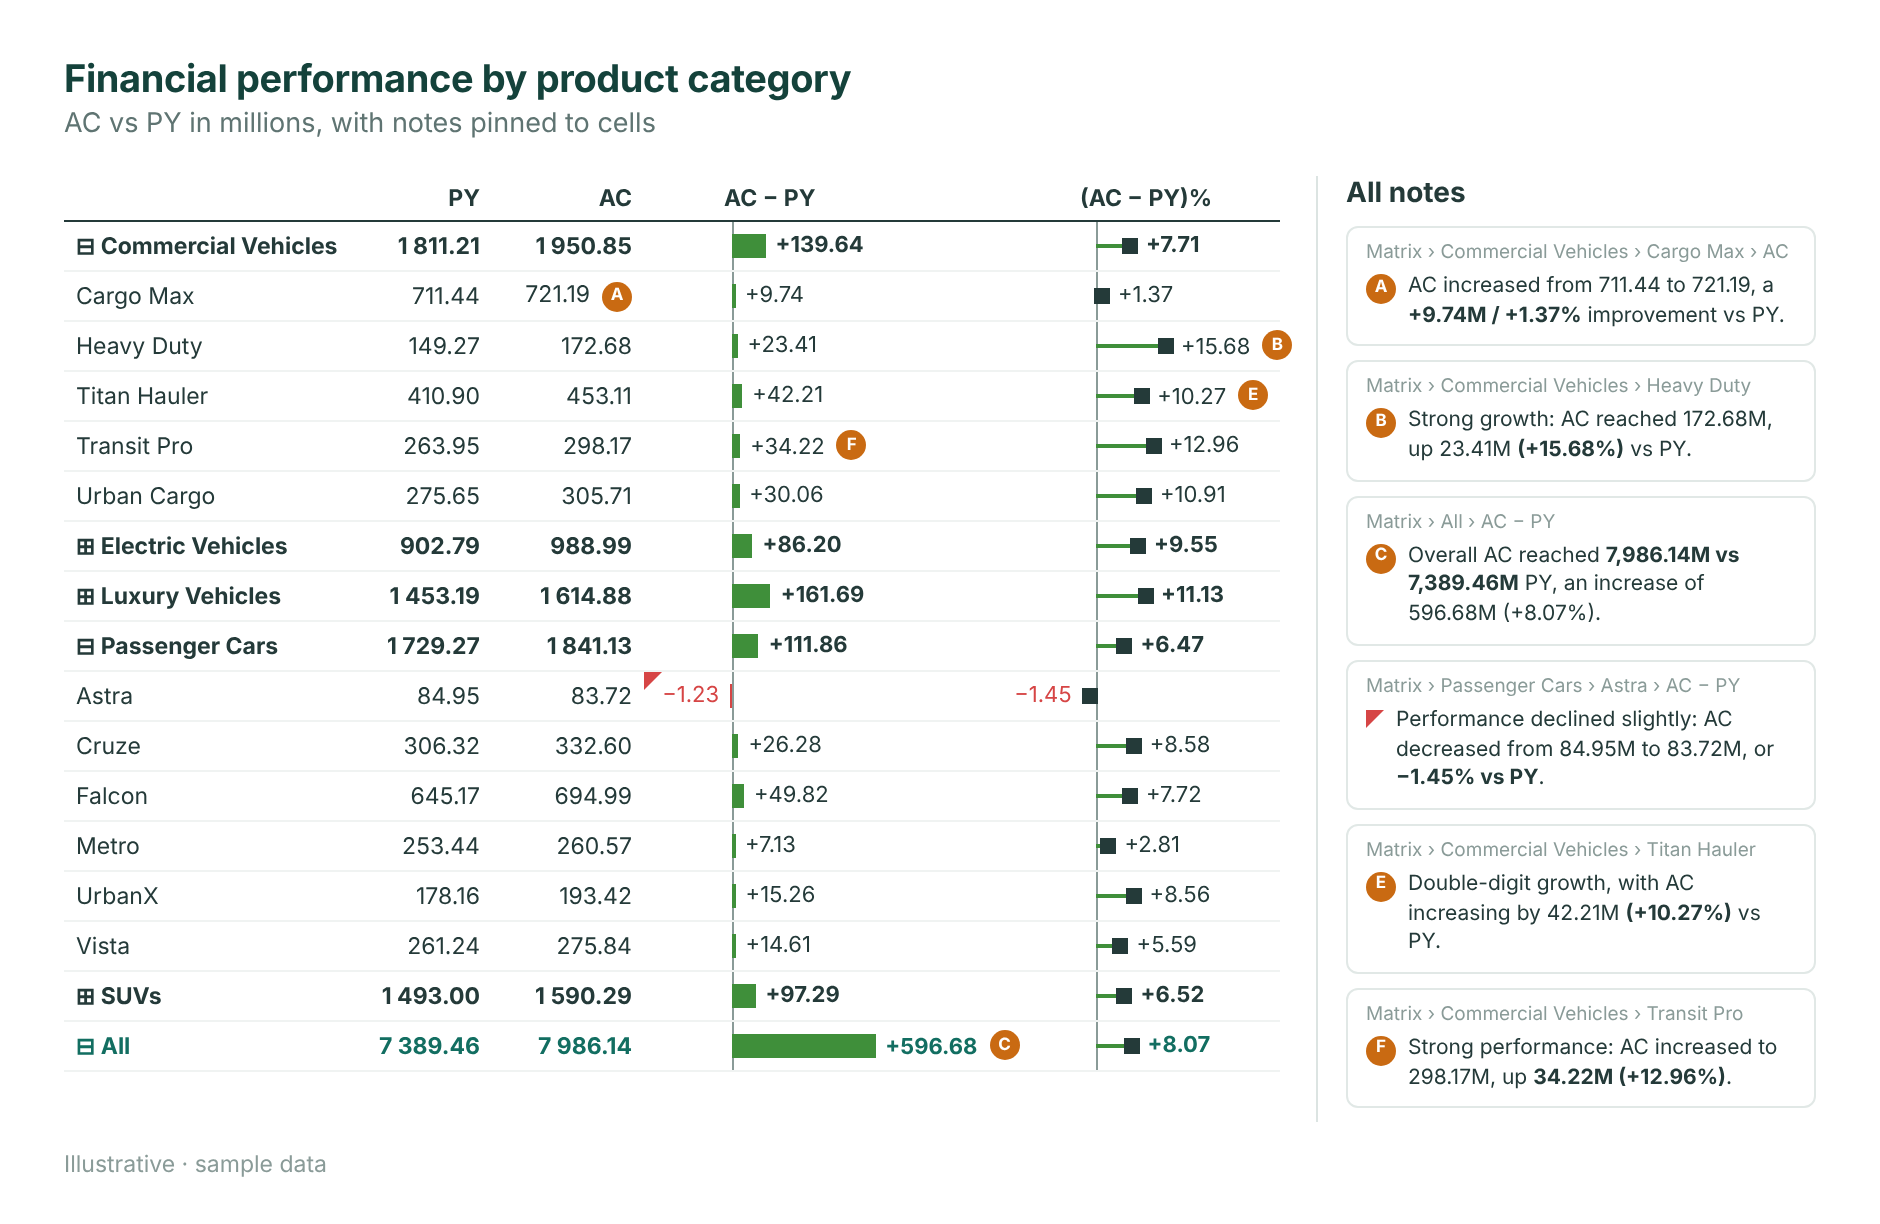
Notes, markers and annotations now stay connected to the data and the filter context behind them, so insights can be reviewed, presented and discussed directly in the report.
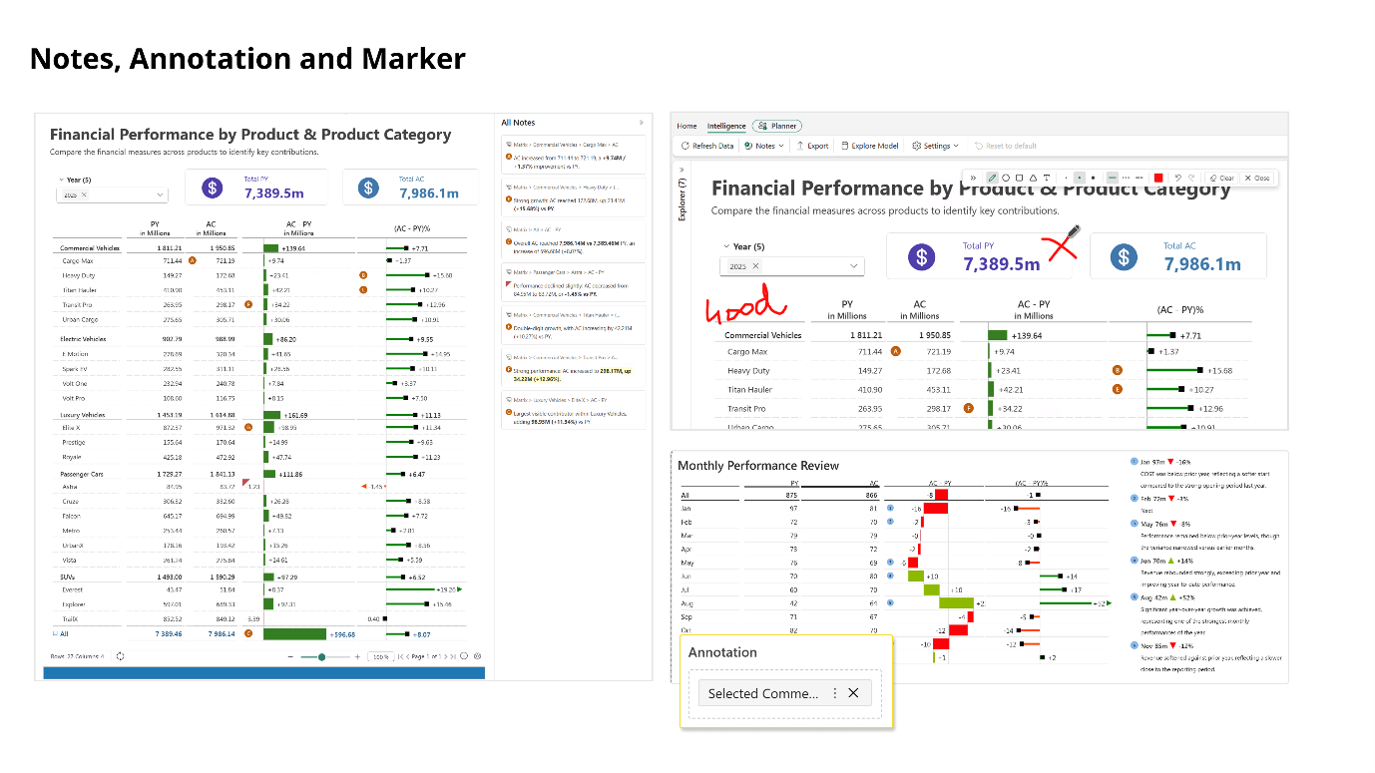
Notes, marker mode and annotations on a financial performance report
Row grouping and reordering, sorting, comments and themes, with better support for blended and non-semantic values.
Add images to the report canvas, and use image URLs and SVGs in charts and KPI visuals.
List, number, date and date-range variables put assumptions in the reader's hands. Variables drive formulas, formatting and actions, and can be bound per environment through Fabric variable libraries, so the same report points at the right values in test and in production.
Change how data is pivoted in a visual by grouping measures and splitting categories, without changing the source data. For example, show actual, plan and prior year side by side within each period.
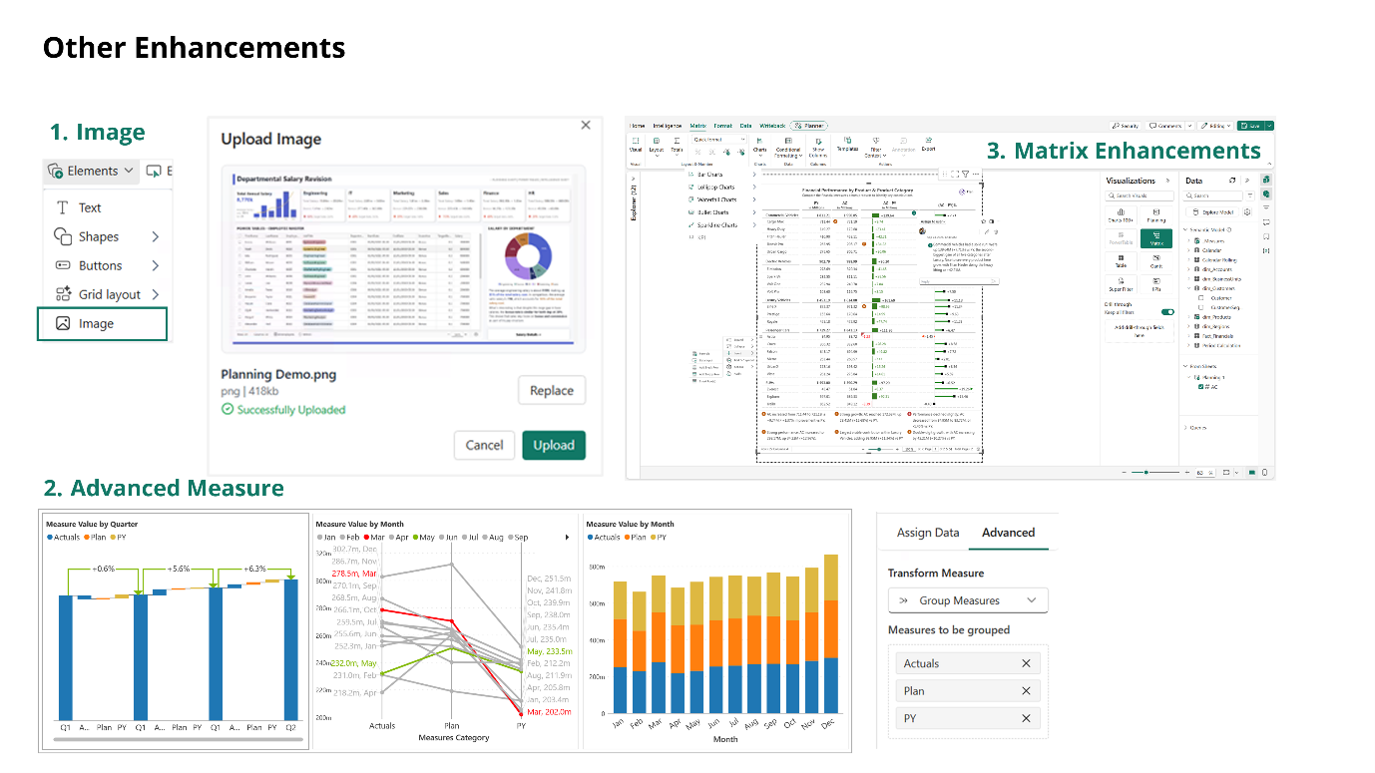
Images on the canvas, grouped measures and matrix enhancements
For more, visit the video library.
PowerTable sheets in Fabric Plan, is a no-code data app for managing dimensions, master and reference data, and business entities, stored and governed in Fabric SQL tables.
Here's a roundup of the latest updates, covering security, automation, data entry, tracking and everyday usability.
Protect sensitive data with security that builds in layers. Access starts at the database and narrows further in PowerTable, with flexible rules that adapt to how each organization defines who should see what.
Let every change set the next one in motion. New automation actions use the data entered in PowerTable to trigger further updates across Fabric items and databases, keeping connected systems in sync without manual effort:
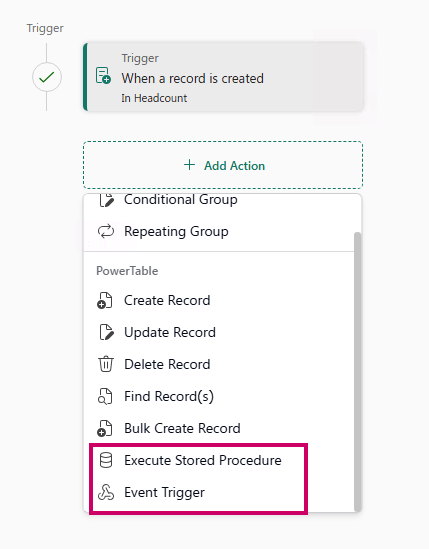
More data, more ease to bring it in. PowerTable now provides greater flexibility at the point of entry:
PowerTable now exposes more metrics and perspectives, making effort and workload easier to track:
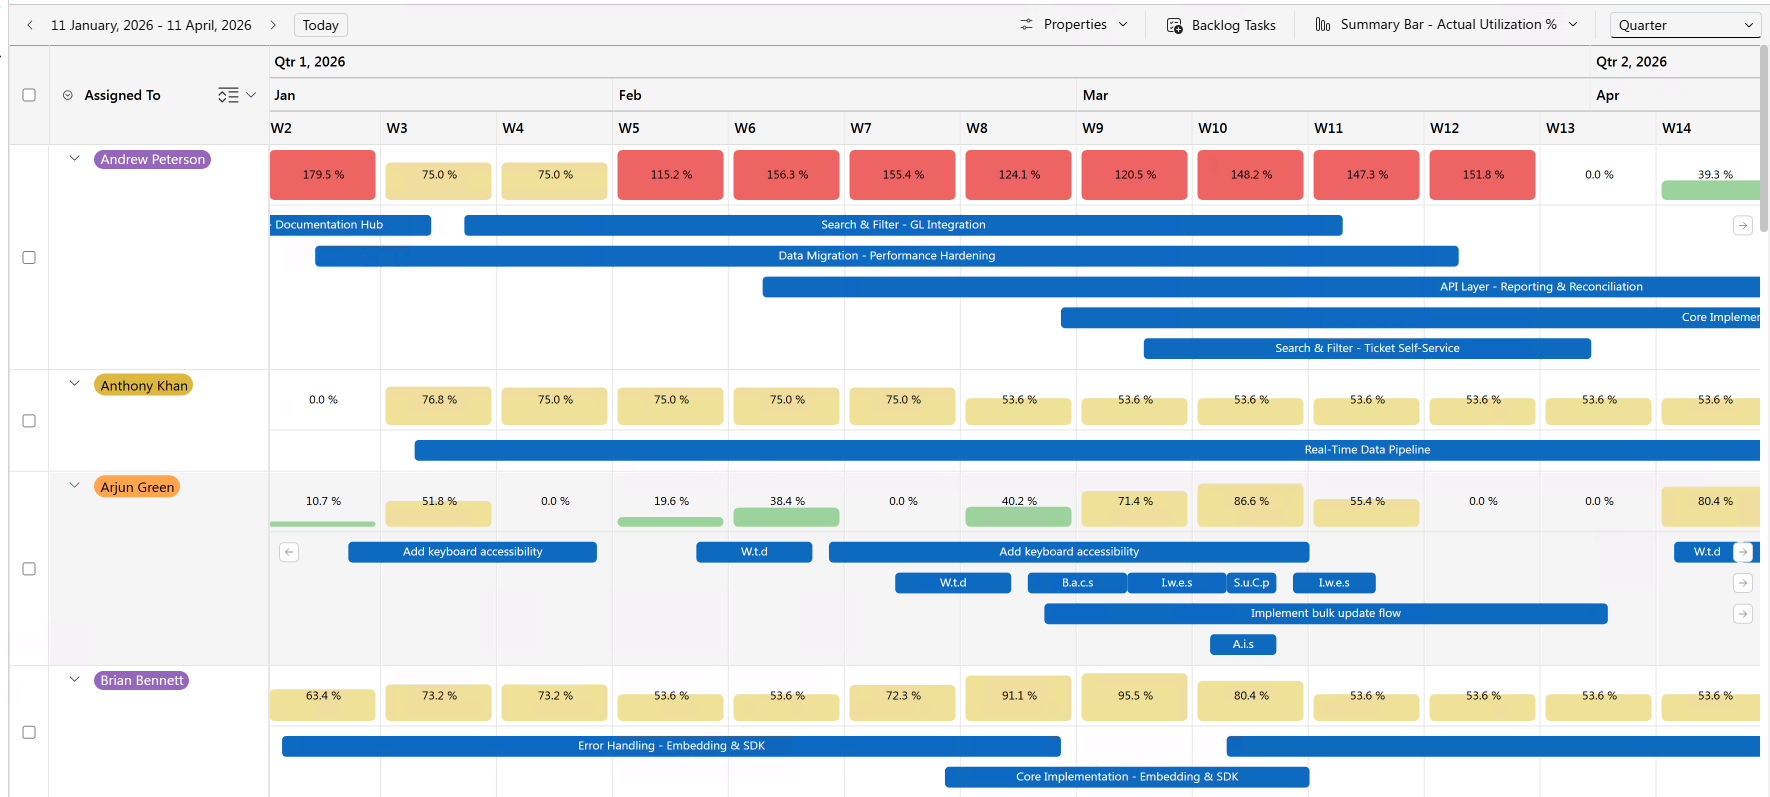
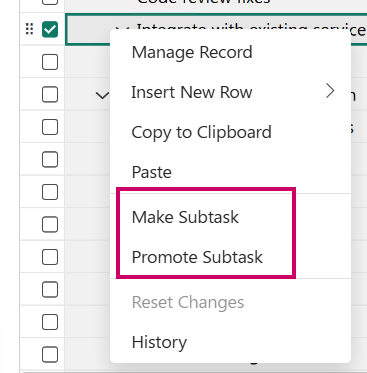
The most common scheduling and restructuring actions are now right where you work:
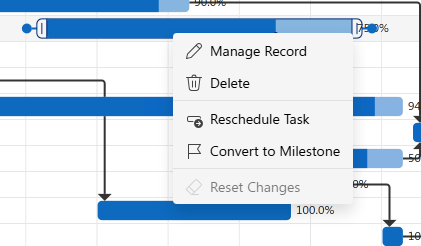
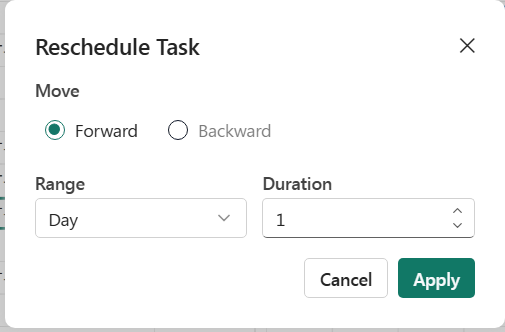
In the pursuit of a more intuitive, personalized and collaborative experience, PowerTable now includes the following updates:
That's the latest from PowerTable. Grab a table, try something new, and watch this space for what's next.
Every Fabric Planning update announced at FabCon Europe in Barcelona, with a short demo video for each feature.
At FabCon Europe 2026, Microsoft announced a new set of capabilities for Planning in Microsoft Fabric. The updates make planning simpler to set up, faster at enterprise scale, more tightly connected to Power BI semantic models and the rest of Fabric, and easier to govern as adoption grows.
Microsoft's announcement covers the headline features: Planning in Microsoft Fabric: From insight to action. This post goes through the full list of updates, shows each one in a demo video, and marks which features are in preview or coming soon.
The Planning updates are grouped into five areas, followed by the limitations removed in this release.
These updates cut down the setup needed before a team can begin working on the numbers.
Connecting a plan to a semantic model is now as simple as building a Power BI report: a single click, with the same workspace permissions you already use in Power BI.
Create Plan → choose semantic model → connect → start planning.Until now, most onboarding effort went into setting up and maintaining the DMTS connection, and into fixing plans when that connection expired. That setup is gone.
| Before | Now |
| Create and share a DMTS connection | Not needed |
| Recover plans after a DMTS connection expires | Not needed |
| Configure a shared cloud connection and service principal | Not needed |
| Turn on tenant settings, including XMLA | On by default |
| Workspace Admin or Member rights, and Build permission on the semantic model | Same permissions as building a Power BI report |
Existing permissions and data access controls continue to apply, so nothing new has to be secured.
Different teams often work inside the same Plan item but need different information. Home Layout lets you create dedicated landing pages for each role within one Plan item.
Each team lands on what it needs first, with less navigation, and one Plan item can serve every team.
These updates support detailed, driver-based plans that stay connected to enterprise targets.
The new Native Planning Engine is built on Rust and Apache Arrow with tight OneLake integration. It delivers up to 10x improvements in performance and scale.
Semantic models can hold billions of rows, but a plan usually works with a few dimensions in rows, time in columns and a set of measures. Most plans need no more than 1.2 million cells. With filters and row-level security (RLS) on the semantic model, that is enough scale for most customers.
The Native Planning Engine supports up to 12 million cells in a planning model. Large plans are still limited by two things outside the engine:
You can now test several drivers together and see their combined effect on the measures that matter.
These updates move approved plans and forecasts into analysis, agents and downstream workflows.
Planners can now write plan data back into the same semantic model the plan is built on, so actuals and plans live in one governed model.
Once plan data is in the connected semantic model, Fabric IQ can use plans and forecasts alongside actuals.
A plan rarely stops when a value is submitted. Event Triggers let planners configure, from the planning UI, what runs when a writeback starts, succeeds or fails.
PowerTable Automations already provide no-code actions for creating, updating and managing records. Some processes depend on logic that lives in the database. Execute Stored Procedure brings that logic into the same automated workflow.
Fabric Planning will add OneLake as a native writeback destination, as an alternative to Fabric SQL Database.
These updates bring planning into the apps people already use and extend it to the people who know the business.
Planning Sheets and Intelligence Sheet reports can now be embedded as pages in a Power BI or Fabric organizational app, alongside Power BI reports and related analytics.
A planner who builds a detailed planning sheet often also needs KPIs, charts and a management-ready view of the same plan. The Intelligence Sheet can now hold Planning and PowerTable content together in one sheet.
A Plan item can now be shared directly with any user, even if they are not a member or viewer of the workspace it lives in.
Guest users invited through Microsoft Entra B2B can now access and collaborate on Plan items in the same way as internal users.
Report authors can add narrative and context directly around the data, so a report explains itself when it is presented.
Fabric Planning is IBCS® certified, aligned with ISO 24896:2026.
These updates give administrators control over access, capacity and permissions as more teams adopt planning.
Until now, any user who entered data, wrote back changes or collaborated was upgraded automatically from a Viewer session to a Stakeholder session. Three new Plan tenant settings in the Fabric Admin Portal let administrators decide who can upgrade and see capacity impact before it happens.
Fabric capacity controls now apply consistently to planning as it reaches a wider audience.
Teams that write back to shared tables rarely need the same access to the same data. Row-level security brings data-driven access control into PowerTable, down to the individual row.
A new setting will let administrators control which Contributors can change security and governance settings in a Plan item.
Fabric Planning supports Microsoft Fabric Private Link at both tenant and workspace level.
Microsoft recently announced a billing change for non-planning editors. For PowerTable-only data management, editors are billed as Stakeholders and consumers as Viewers, so teams get full data management without a Planner session.
Several limitations from earlier releases have now been removed.
| Feature | March 2026 | Now |
| B2B user support | No | Yes |
| Private Link support | No | Yes (Preview) |
| Semantic model connection authentication | OAuth / service principal | All supported authentication methods |
| Admin/Build permission required on semantic model | Required | No |
| Direct Lake semantic models need extra configuration | Yes | No |
| Feature | March 2026 | Now |
| Power BI Pro / PPU / lower-capacity SKUs (no XMLA support) | No | Yes |
| Bulk data input limit | 1M rows | 10M rows |
| Feature | March 2026 | Now |
| CI/CD deployment with a service principal | No | Yes |
| Database-level row-level security (RLS) | No | Yes |
| DMTS connection recovery | Manual rebuild needed | Yes |
| Contributor role: create/share cloud connections | No | Not applicable |
| Contributor role: Plan items requiring embed tokens | No | Not applicable |
Microsoft's stated next step is an API surface for the planning lifecycle, so an agent can work inside a plan the way a planner does: draft a forecast, run a simulation across drivers, compare scenarios before a commitment is made, write the result back, and start the downstream work it sets in motion.
We will walk through these updates in a live session, with demos and time for questions: Register now


